2026-09-17 · B1 — Final-value flags, masking and revision nowcasting
Archived experiment. Results and figures describe the recorded protocol; current execution instructions are in the Workflow page.
Best models by season
Top three configurations by the reported combined score (all configurations if fewer than three). Season columns are seed means. Lower is better; 1 is the matched Hub ensemble.
| Model | 2023-2024 | 2024-2025 | 2025-2026 | Combined |
|---|---|---|---|---|
C1 · b1:v2:h12:tr_4rt:ed_logit:geo1:dyn1:lw_obj:enc_mlp:sp_none:hd_sh:dec_leg:nz_glob |
0.9681 | 0.8932 | 0.9553 | 0.9389 |
C2 · b1:v2:h12:tr_4rt:ed_logit:geo1:dyn1:lw_obj:enc_mlp:sp_none:hd_sh:dec_leg:nz_glob |
0.9914 | 0.9311 | 0.9328 | 0.9518 |
C3 · b1:v2:h12:tr_4rt:ed_logit:geo1:dyn1:lw_obj:enc_mlp:sp_none:hd_sh:dec_leg:nz_glob |
0.9715 | 0.9464 | 0.9411 | 0.9530 |
| Hub ensemble | 1.0000 | 1.0000 | 1.0000 | 1.0000 |
| B0 reference | 1.0179 | 0.7485 | 0.9003 | 0.8889 |
C1–C3 are the three lowest saved combined scores. B0 is the reproduced stage09 reference on the same seasons. Inputs, training recipes and forecast sampling can differ; this is contextual, not a paired intervention. Archive dates identify first recorded publication.
Protocol
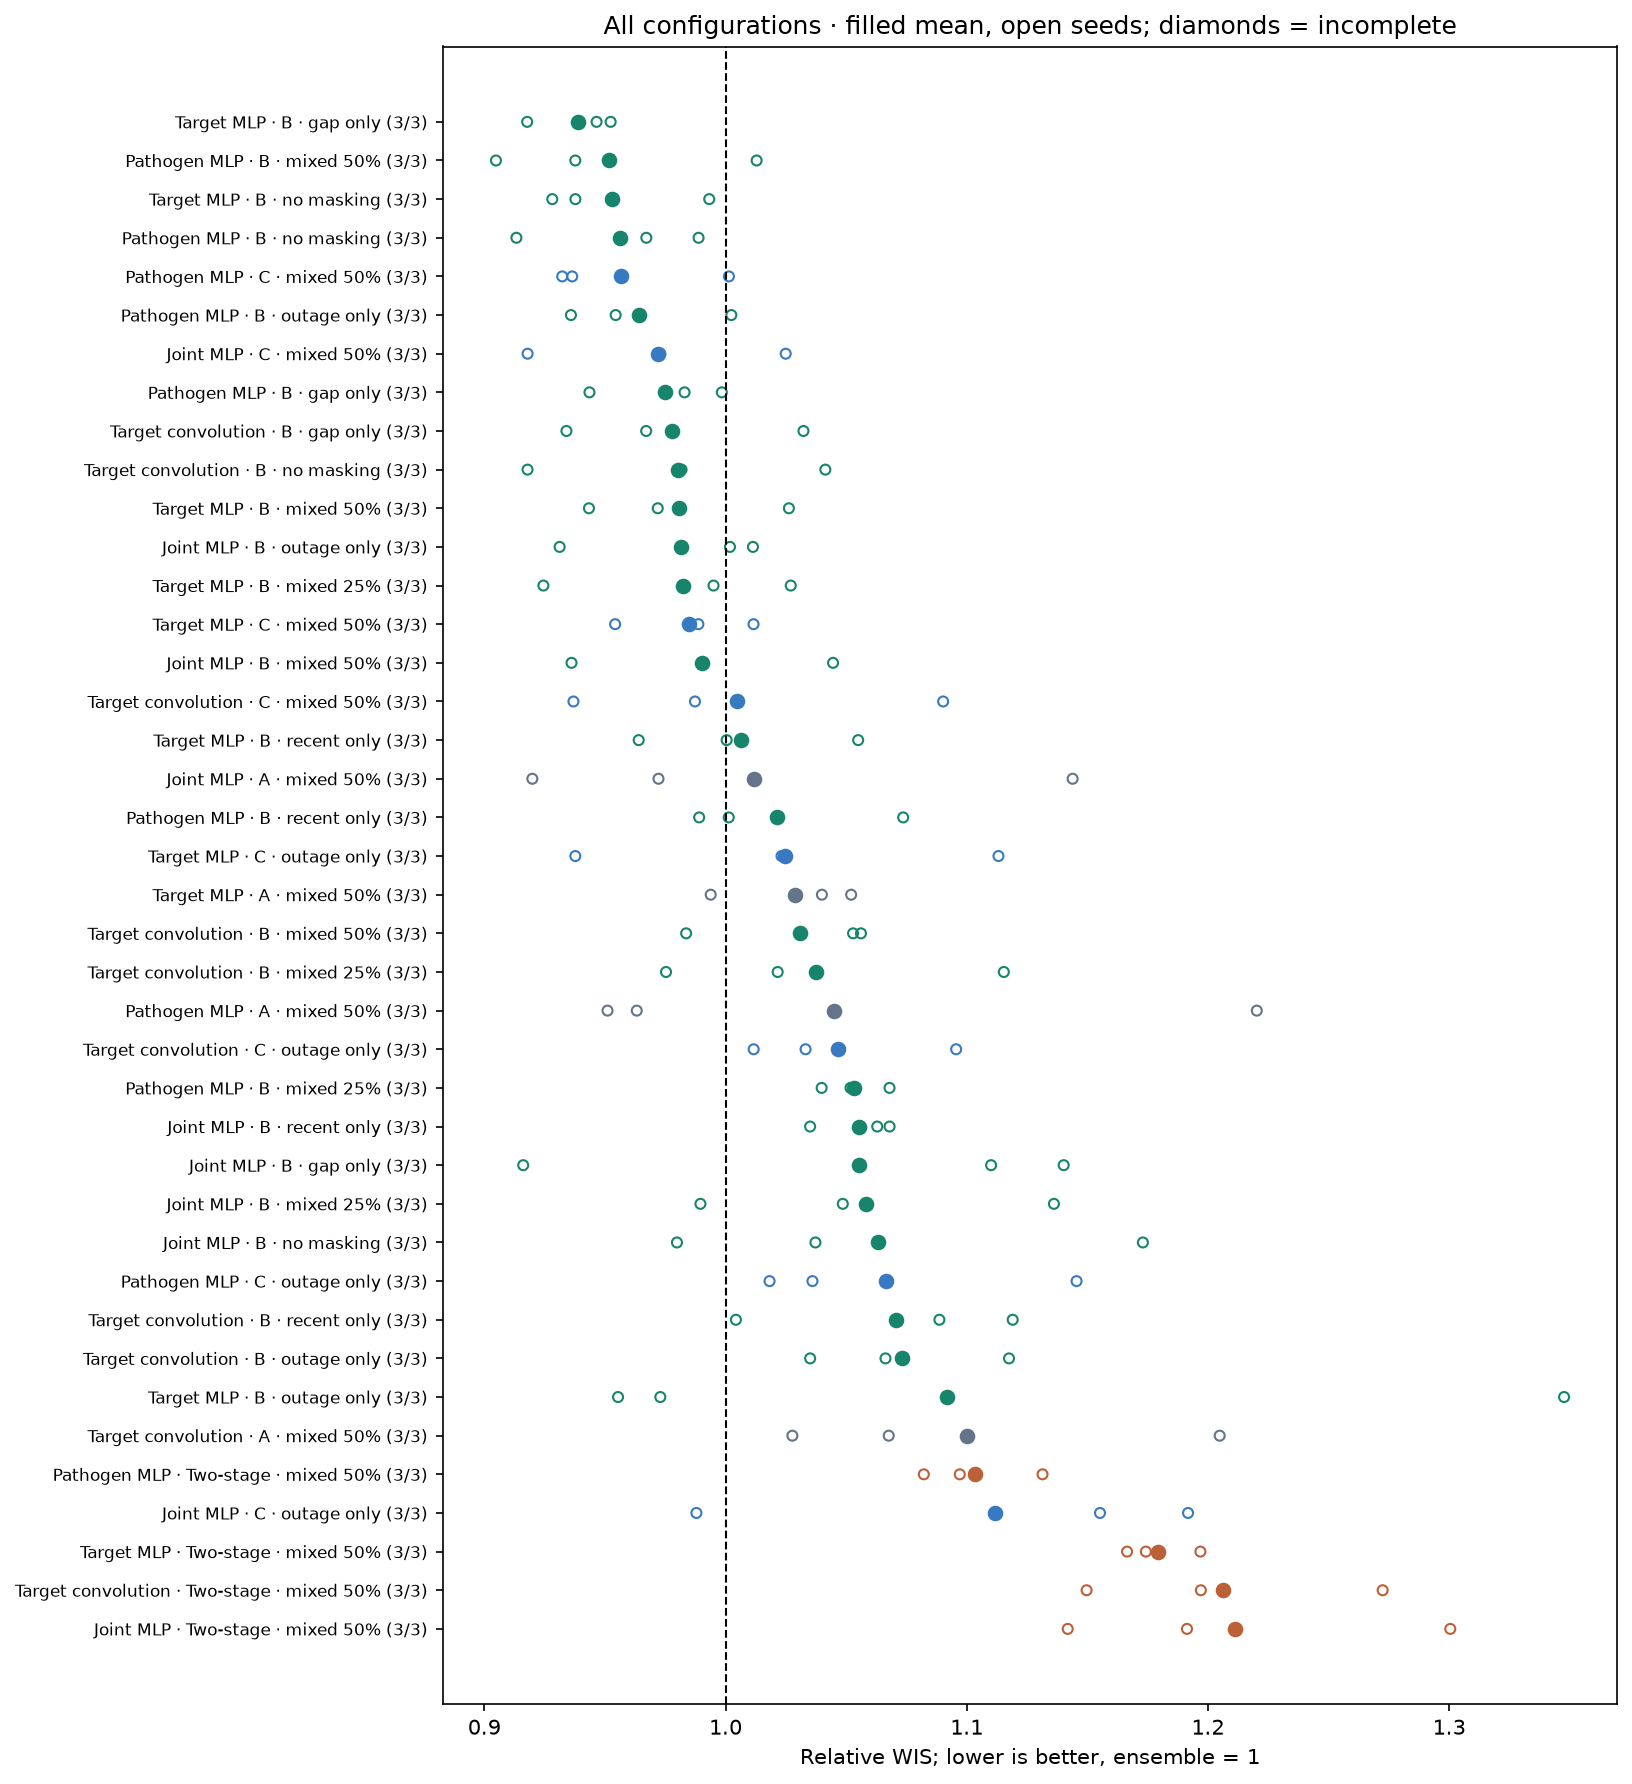
15 of 40 configurations beat the Hub ensemble on the combined forecast score. The leading configuration is Target MLP · B · gap only, at 0.939 (6.1% lower relative WIS). These headline numbers describe the original overnight screen. The separate 300-epoch comparison is reported below, followed by the revision experiment, which scores forecasting, nowcasting and reconstruction as three separate questions.
If you read one thing
B gap-only/no-mask controls still have the best forecast means. The gated branch improves matched target B and is the strongest tested revision family, but its benefit depends on backbone and masking. The 11% nowcast headline is conditional on a post-hoc near-zero-denominator exclusion. Reconstruction must be assessed on matched, normalized errors; outage failures are model behavior, not an established scorer artifact. See the corrected revision analysis below.
Snapshot and experiment
Generated 2026-09-17T21:23-04:00. 120/120 seed runs complete; status: {'complete': 120}. The page is a snapshot, not a live dashboard. Incomplete averages show their seed count; paired contrasts use only seeds completed on both sides. No missing run receives an imputed score.
Four architectures × ten formulation/masking settings × seeds 42/43/44 = 120 runs, with three held-out season folds per run. Target MLP, pathogen MLP and target convolution use a 100-epoch cap; joint MLP uses 300. All use patience 30 and select then refit. Evaluation uses 256 trajectories and the frozen 23 Hub quantiles. See the screen specification (not retained in the experiment archive) and 300-epoch follow-up (not retained in the experiment archive).
The score divides model WIS by ensemble WIS within target/season/location, weights states/DC 80% and US 20%, then admissions 1 and ED 0.5 within each season, and averages seasons equally. Lower is better; 1 is ensemble parity. Target support is flu admissions in 2023–24; flu/COVID admissions in 2024–25; and all six targets in 2025–26. Combined skill is not a claim of winning every target or season.
What the formulations mean
| Formulation | Outputs and training |
|---|---|
| A — direct | Forecasts four future weeks; no explicit nowcast output. |
| B — supplied-final flags | Direct forecasts with indicators identifying supplied finalized inputs; no nowcast output. |
| C — auxiliary nowcast | Shared representation, separate recent/future heads, supplied-final flags; forecast loss + 0.25 × recent loss; forecast-only checkpoint selection. |
| Two-stage | Sample recent values and feed them into forecasting; supplied-final flags and exact visible-final bypass; equally weighted recent/future selection loss. |
Independent fits still receive all six input histories. Target models have six components, pathogen models three, joint models one. Each component selects its epoch count separately, then a fresh model refits on all permitted training weeks. Held-out seasons are excluded.
Training budget and the 300-epoch question
For the matched pathogen-MLP formulation panel:
| Formulation | Selections | Hit cap | Best epoch ≥90 |
|---|---|---|---|
| A | 27 | 17 | 6 |
| B | 27 | 18 | 9 |
| C | 27 | 17 | 13 |
| Two-stage | 27 | 19 | 15 |
Hitting a cap, or selecting a late epoch, suggests that a longer budget merits testing; it does not establish undertraining as the cause of poor held-out WIS. Selection loss differs between formulations and cannot be read as the final Hub WIS. The separate follow-up raises the cap to 300 while retaining patience 30, three seeds, four formulations, and all four architectures. Joint MLP already had cap 300, so its repeats are controls rather than a cap contrast.
Season splits
No known season-split graph or description.
Findings
Formulations at matched mixed masking
Every entry uses a 50% probability of corrupting a training episode, with a conditional recent/gap/outage mixture of 50/30/20. Parentheses give completed seeds out of three.
| Architecture | A | B | C | Two-stage |
|---|---|---|---|---|
| Target MLP | 1.029 (3/3) | 0.980 (3/3) | 0.985 (3/3) | 1.179 (3/3) |
| Pathogen MLP | 1.045 (3/3) | 0.952 (3/3) | 0.957 (3/3) | 1.104 (3/3) |
| Target convolution | 1.100 (3/3) | 1.031 (3/3) | 1.005 (3/3) | 1.206 (3/3) |
| Joint MLP | 1.012 (3/3) | 0.990 (3/3) | 0.972 (3/3) | 1.211 (3/3) |
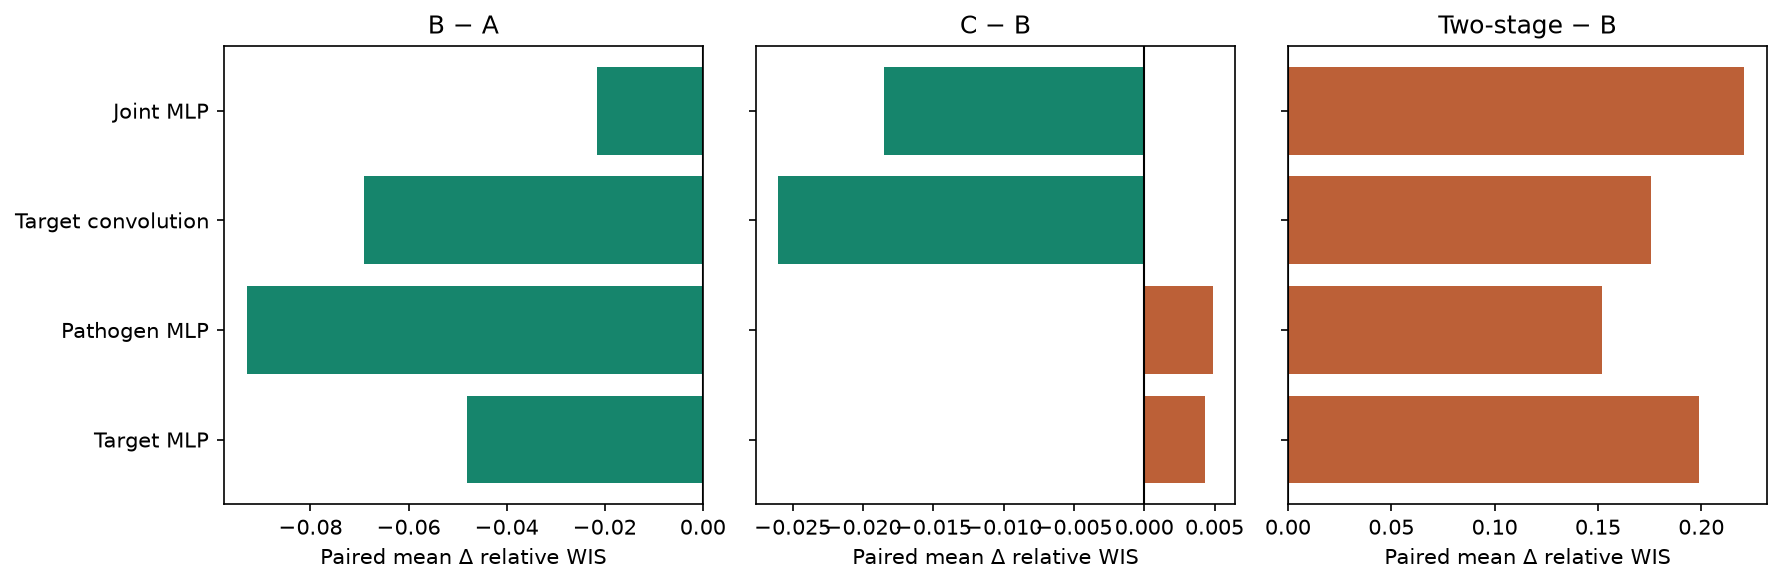
Negative differences favor the first model named in the contrast (for example, C in C − B). These compare the complete formulations: the two-stage/B contrast changes the decoder, anchoring, and loss weighting as well as feedback.
| Architecture | Contrast | Paired seeds | Mean Δ WIS | Seed Δ SD | Seeds improved |
|---|---|---|---|---|---|
| Target MLP | B − A | 3 | -0.048 | 0.021 | 3 |
| Target MLP | C − B | 3 | 0.004 | 0.017 | 1 |
| Target MLP | Two-stage − B | 3 | 0.199 | 0.030 | 0 |
| Pathogen MLP | B − A | 3 | -0.093 | 0.100 | 3 |
| Pathogen MLP | C − B | 3 | 0.005 | 0.023 | 2 |
| Pathogen MLP | Two-stage − B | 3 | 0.152 | 0.059 | 0 |
| Target convolution | B − A | 3 | -0.069 | 0.070 | 3 |
| Target convolution | C − B | 3 | -0.026 | 0.053 | 2 |
| Target convolution | Two-stage − B | 3 | 0.175 | 0.101 | 0 |
| Joint MLP | B − A | 3 | -0.022 | 0.170 | 1 |
| Joint MLP | C − B | 3 | -0.018 | 0.001 | 3 |
| Joint MLP | Two-stage − B | 3 | 0.221 | 0.031 | 0 |
What works, what does not
Supplied-final flags are the most consistent improvement over direct forecasting. B lowers mean WIS versus A in 4/4 architectures, by 0.022–0.093. The target MLP, pathogen MLP and target convolution improve on all three matched seeds; the joint MLP improves on only one seed despite its better mean, so that contrast is less stable.
Auxiliary nowcasting is competitive, not a general failure. At mixed masking 50%, C scores 0.957 versus B's 0.952 for pathogen MLP. The target MLP also changes little. C improves mean WIS for the target convolution and joint MLP; the joint comparison improves on all three seeds. These results do not establish that producing a nowcast is itself the cause: C changes the training objective as well as the outputs.
Two-stage is worse on natural inputs in every matched architecture and seed. Its mean penalty relative to B is 0.152–0.221. This is evidence against the current complete two-stage formulation for natural-input forecasting. It does not identify whether the problem is training duration, decoder/anchoring, objective weighting, or feeding recent estimates into the forecast. Those remain separate hypotheses.
There is no universally best masking recipe. Gap-only B wins overall for target MLP; mixed 50% B wins within pathogen MLP. Training without artificial masking is competitive in both families. The 25% setting is not an intermediate step in a monotonic improvement curve. Masking changes validation as well as training, so these are recipe comparisons, not isolated regularization effects.
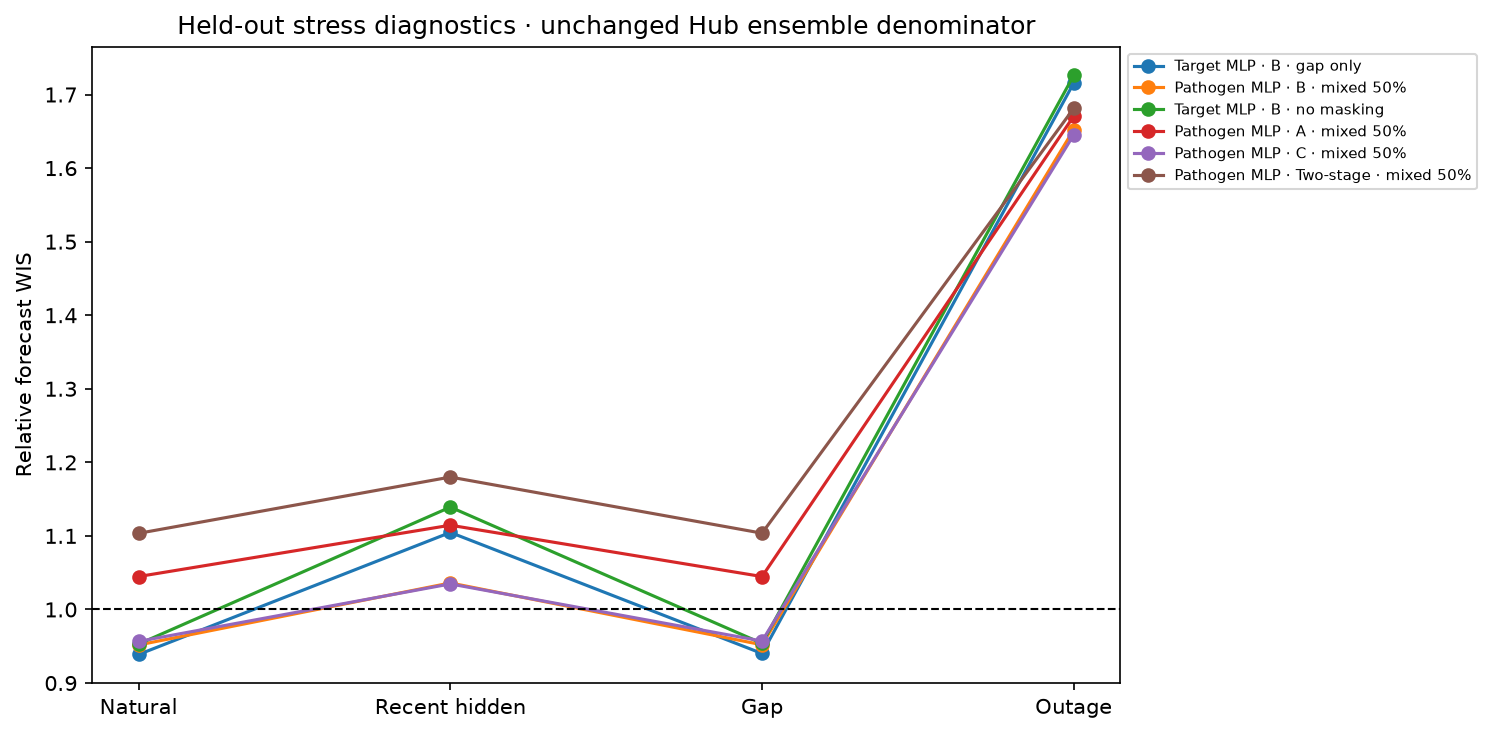
Natural-input winners are not necessarily the most robust to outages. The overall winner moves from 0.939 naturally to 1.716 under a full-channel outage. Two-stage target MLP and target convolution have lower outage scores than their B counterparts, despite losing on natural inputs. The following matched panel makes that tradeoff explicit; all values are forecast WIS relative to the original, uncorrupted ensemble baseline.
| Architecture | A | B | C | Two-stage |
|---|---|---|---|---|
| Target MLP | 1.650 | 1.645 | 1.617 | 1.432 |
| Pathogen MLP | 1.671 | 1.652 | 1.645 | 1.681 |
| Target convolution | 1.734 | 1.709 | 1.675 | 1.323 |
| Joint MLP | 1.669 | 1.651 | 1.648 | 1.787 |
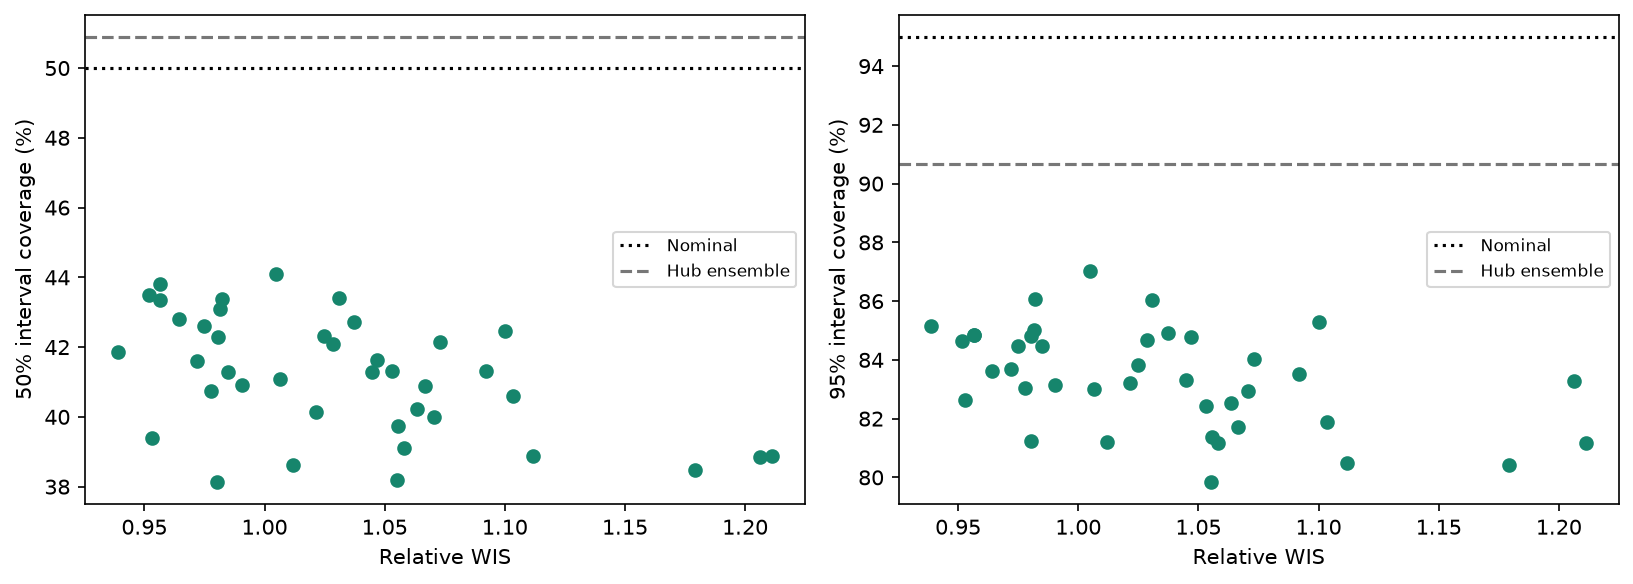
Calibration still needs work. The winning model's weighted 50% and 95% coverage are 41.9% and 85.2%. Winning on WIS does not mean its uncertainty intervals are calibrated.
For the next decision, retain the best natural-input B recipes, C as a competitive formulation, and the two-stage outage tradeoff. Use the 300-epoch experiment to test the training-budget explanation before changing the architecture or loss. Do not select a universal winner from small mean differences over only three seeds.
Held-out stress diagnostics
These scores use the same frozen target cells and unchanged Hub ensemble denominator, but artificially hide model inputs. They are robustness diagnostics, not additional independent evaluations or a comparison against an ensemble subjected to the same corruption.
| Configuration | gap | natural | outage | recent |
|---|---|---|---|---|
| Target MLP · B · gap only | 0.940 | 0.939 | 1.716 | 1.105 |
| Pathogen MLP · B · mixed 50% | 0.952 | 0.952 | 1.652 | 1.036 |
| Target MLP · B · no masking | 0.954 | 0.953 | 1.726 | 1.139 |
| Pathogen MLP · A · mixed 50% | 1.045 | 1.045 | 1.671 | 1.115 |
| Pathogen MLP · C · mixed 50% | 0.957 | 0.957 | 1.645 | 1.035 |
| Pathogen MLP · Two-stage · mixed 50% | 1.104 | 1.104 | 1.681 | 1.180 |
Target, season, geography, and calibration
The combined score can hide different behavior by pathogen or season. The panels below use only available frozen Hub support; an absent target/season combination is not filled in.
Where the gains and failures occur
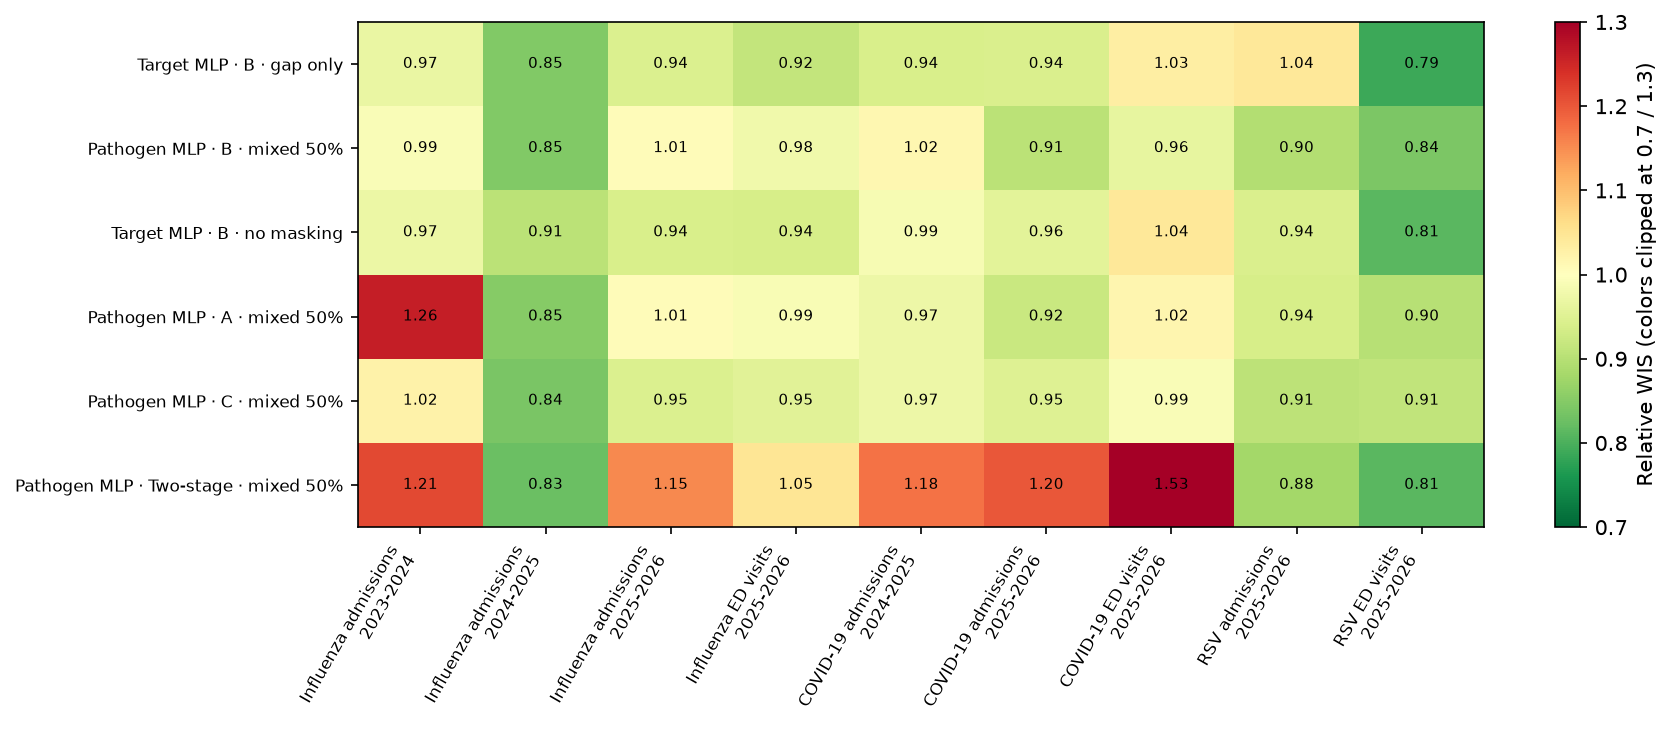
The overall leader uses target MLP, B, gap-only masking. The other columns fix pathogen MLP and mixed 50% masking; values average all three seeds. These are the nine available target/season cases, not nine equally weighted contributions to the combined score: seasons receive equal weight and targets are weighted within seasons.
| Season | Target | Overall leader | Pathogen B | Pathogen C | Pathogen two-stage |
|---|---|---|---|---|---|
| 2023-2024 | Influenza admissions | 0.968 | 0.991 | 1.023 | 1.215 |
| 2024-2025 | Influenza admissions | 0.847 | 0.847 | 0.841 | 0.826 |
| 2025-2026 | Influenza admissions | 0.944 | 1.006 | 0.945 | 1.153 |
| 2025-2026 | Influenza ED visits | 0.915 | 0.978 | 0.953 | 1.049 |
| 2024-2025 | COVID-19 admissions | 0.940 | 1.016 | 0.973 | 1.175 |
| 2025-2026 | COVID-19 admissions | 0.943 | 0.905 | 0.950 | 1.200 |
| 2025-2026 | COVID-19 ED visits | 1.032 | 0.964 | 0.992 | 1.532 |
| 2025-2026 | RSV admissions | 1.044 | 0.895 | 0.907 | 0.880 |
| 2025-2026 | RSV ED visits | 0.787 | 0.842 | 0.911 | 0.810 |
The overall leader still loses to the ensemble on RSV admissions and COVID ED in 2025–26. Its strongest case-level gains are RSV ED in 2025–26 and flu admissions in 2024–25. Pathogen C improves on B for flu admissions in 2025–26 while losing ground on COVID admissions and RSV ED that season; the similar combined scores therefore conceal meaningful differences across targets.
The pathogen two-stage model's failures are concentrated in flu admissions in 2023–24 and COVID admissions/ED and flu admissions in 2025–26. It remains competitive on flu admissions in 2024–25 and RSV in 2025–26. These score-based observations do not identify whether bias, spread, or timing causes those failures.
Coverage here uses the same geography, target and season weighting as the combined score, then averages seeds. It is a diagnostic, not an alternative ranking objective. Coverage below nominal can reflect bias, narrow intervals, or both; these plots alone do not isolate the cause. Coverage data · Target/season scores.
Assumptions and limits
- Retrospective development CV: older inputs are finalized and missing recent vintage reports can receive supplied finals. This is not prospective deployment performance.
- The same seasons informed architecture selection and this ranking. Three seeds do not measure all sources of uncertainty; small gaps remain unresolved.
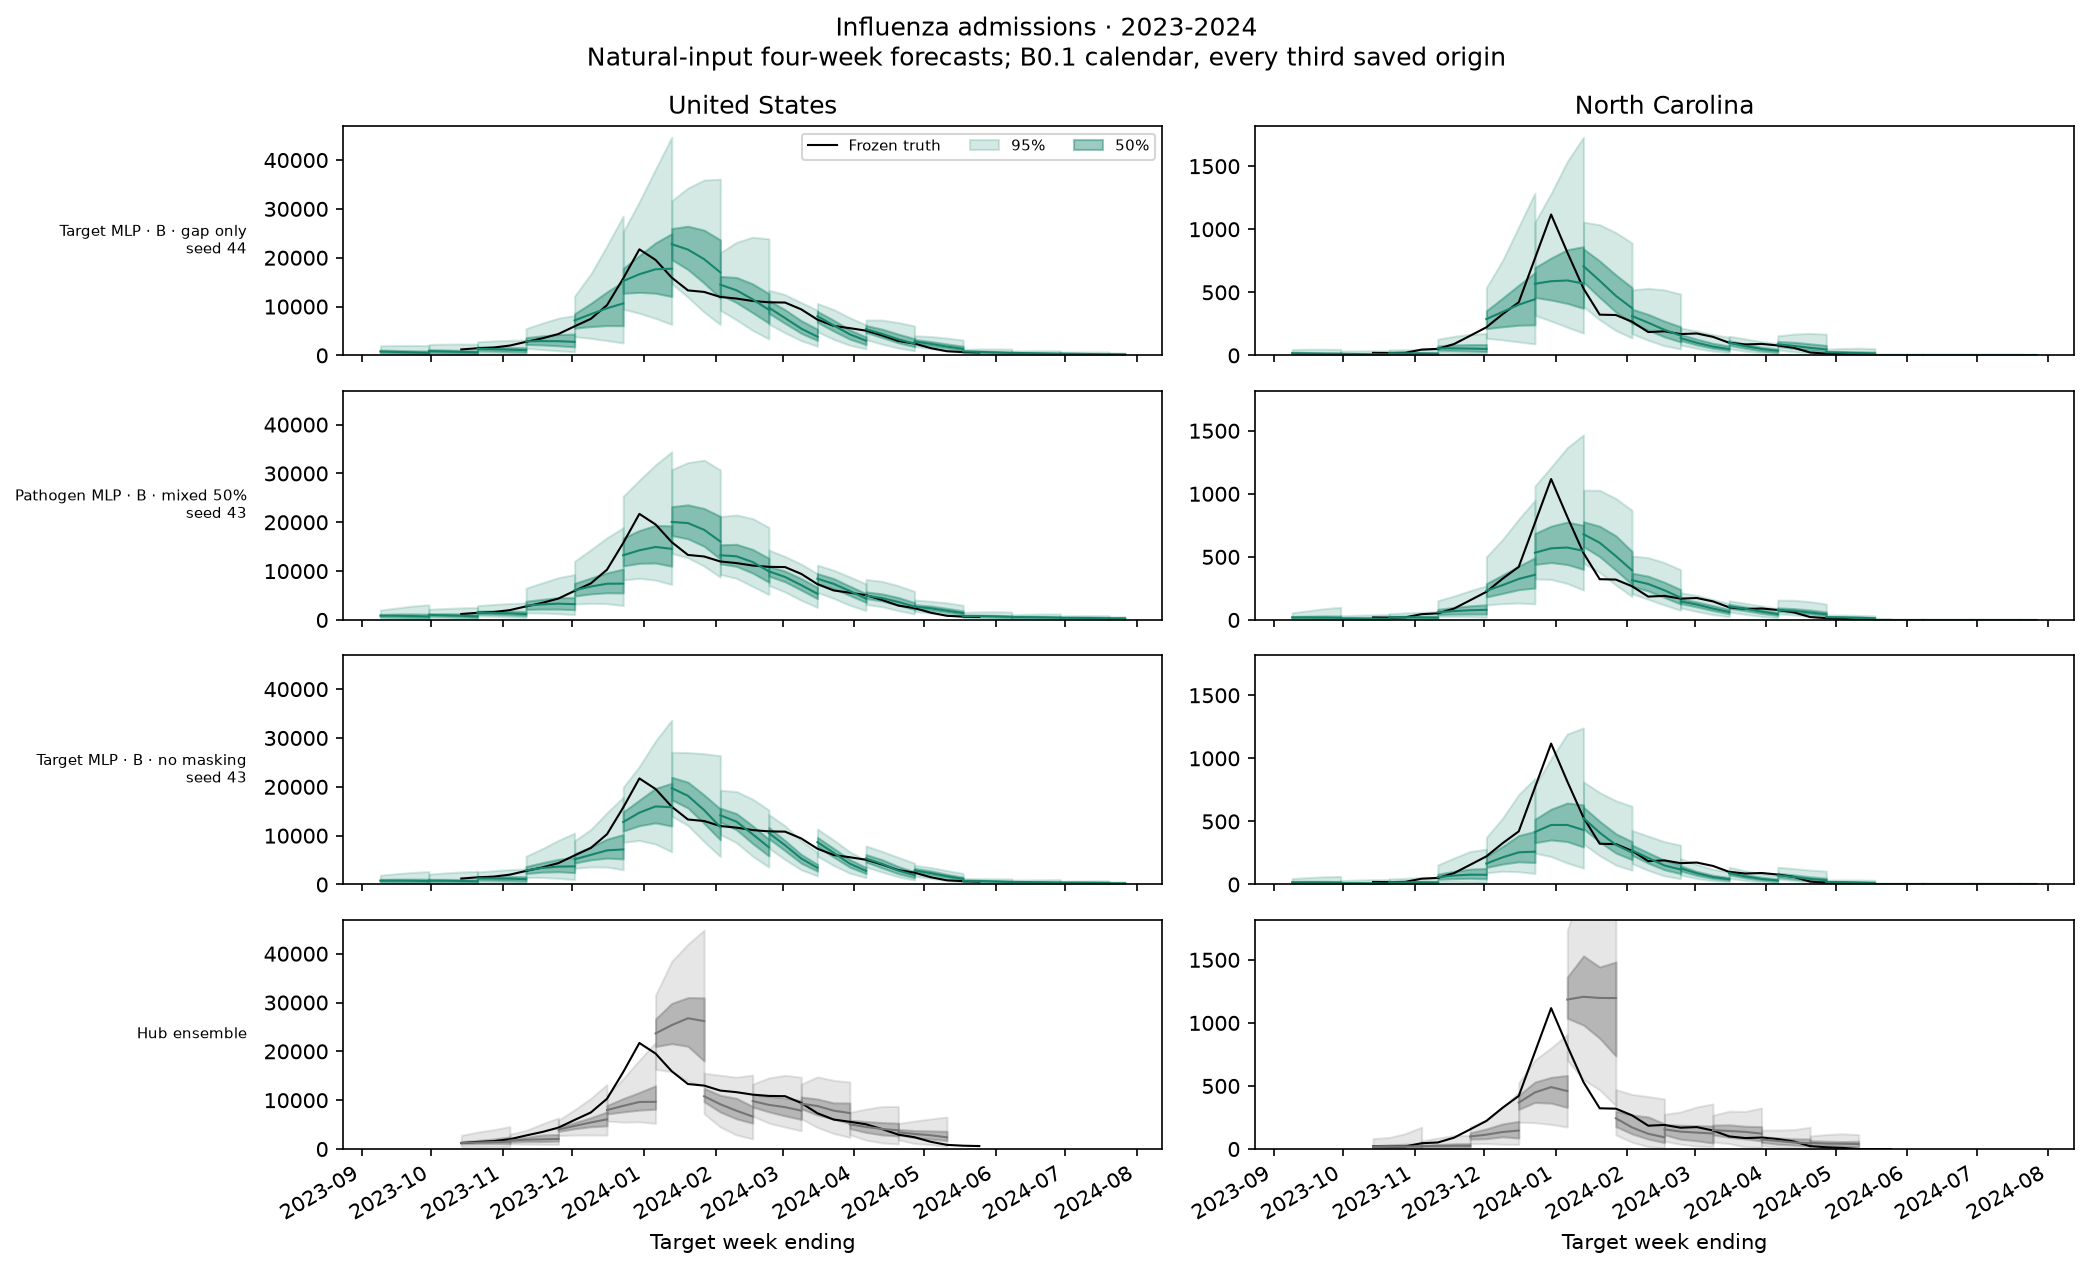
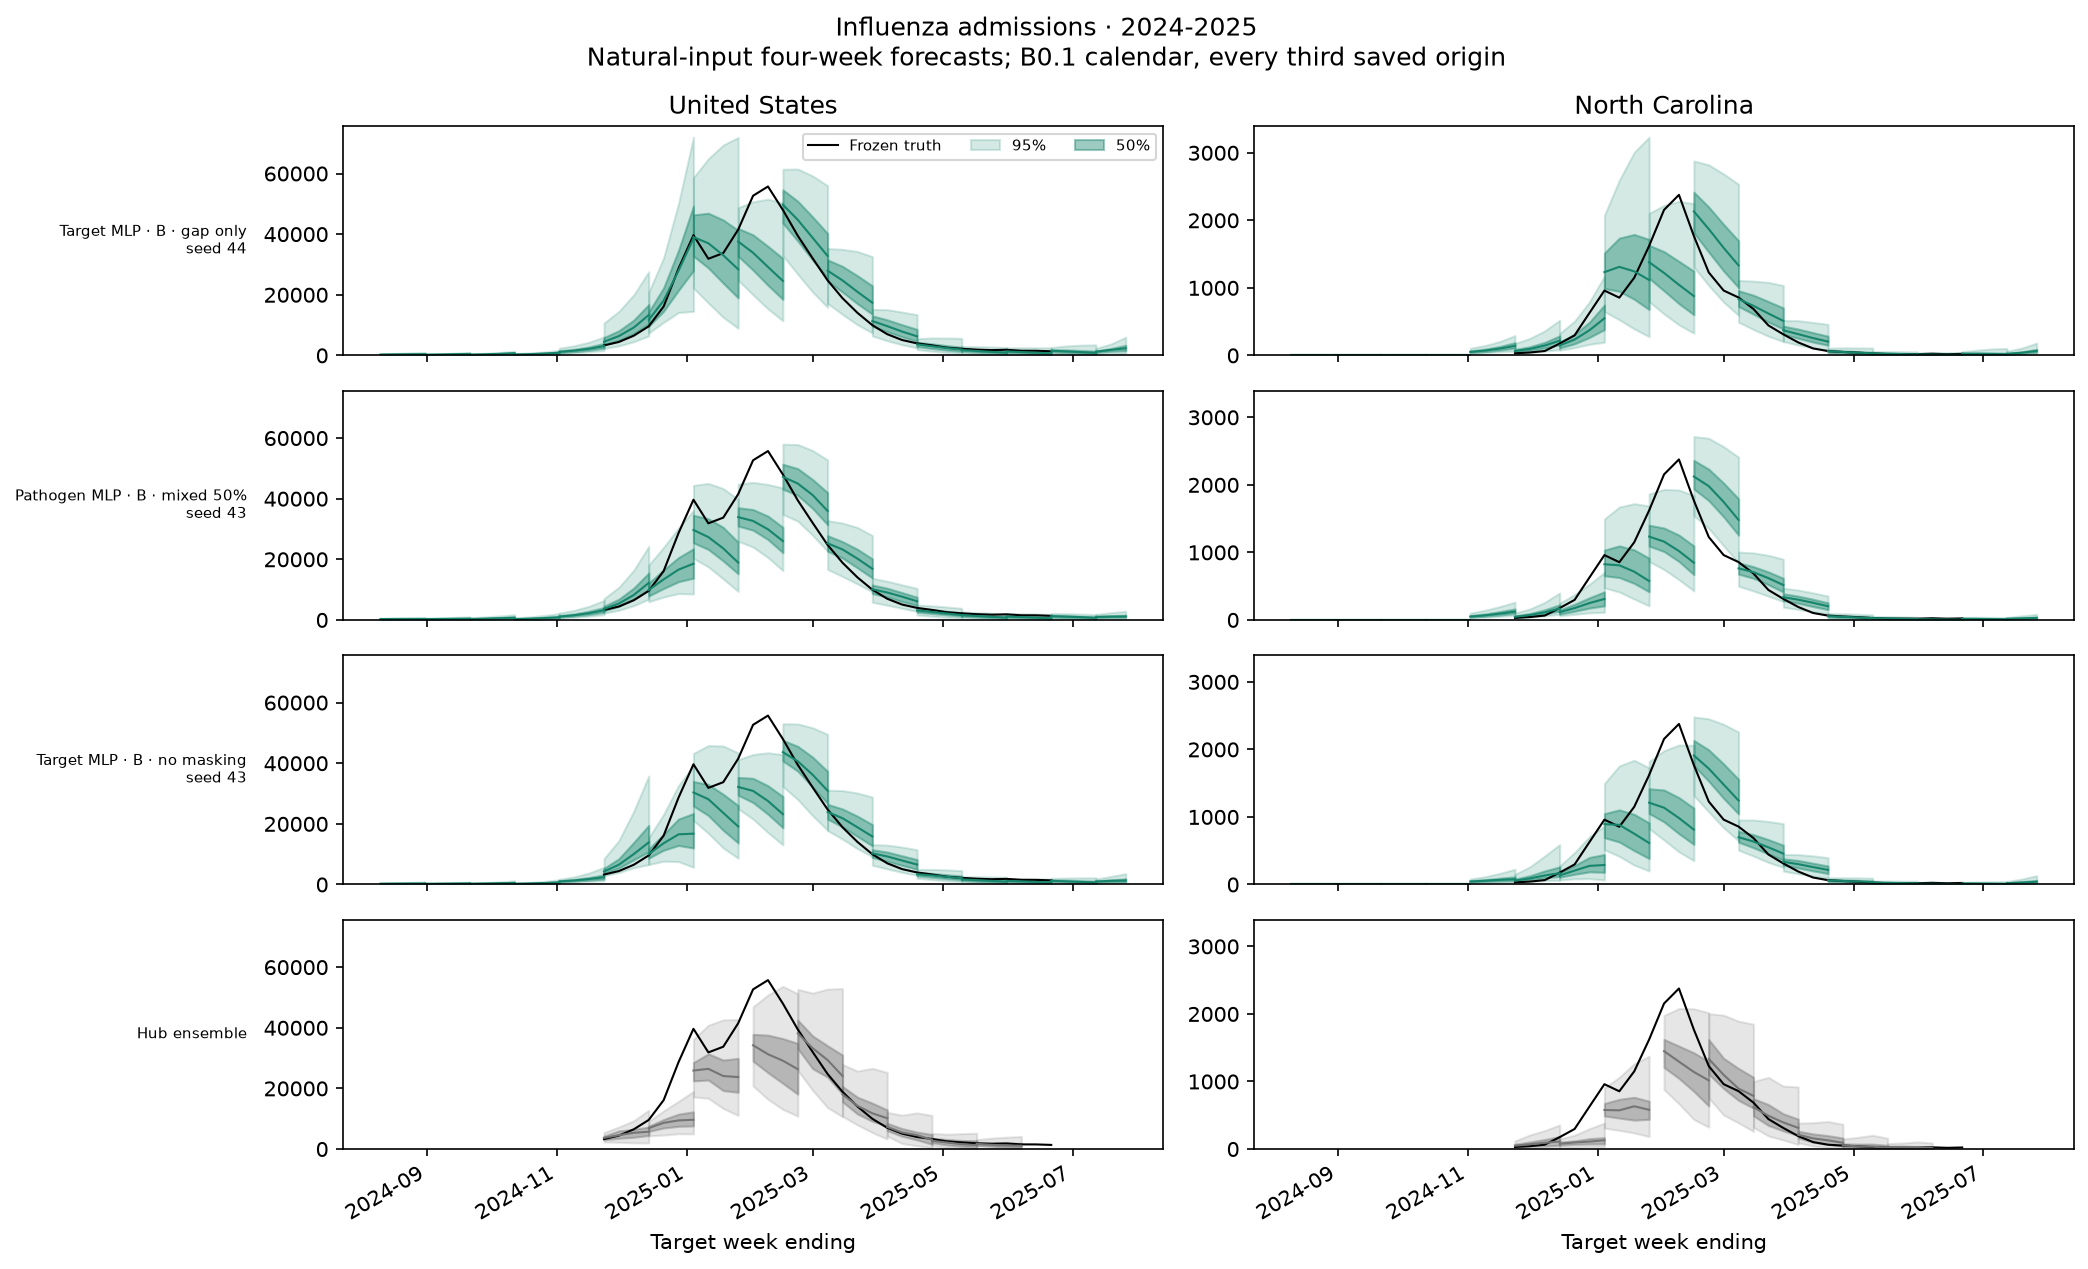
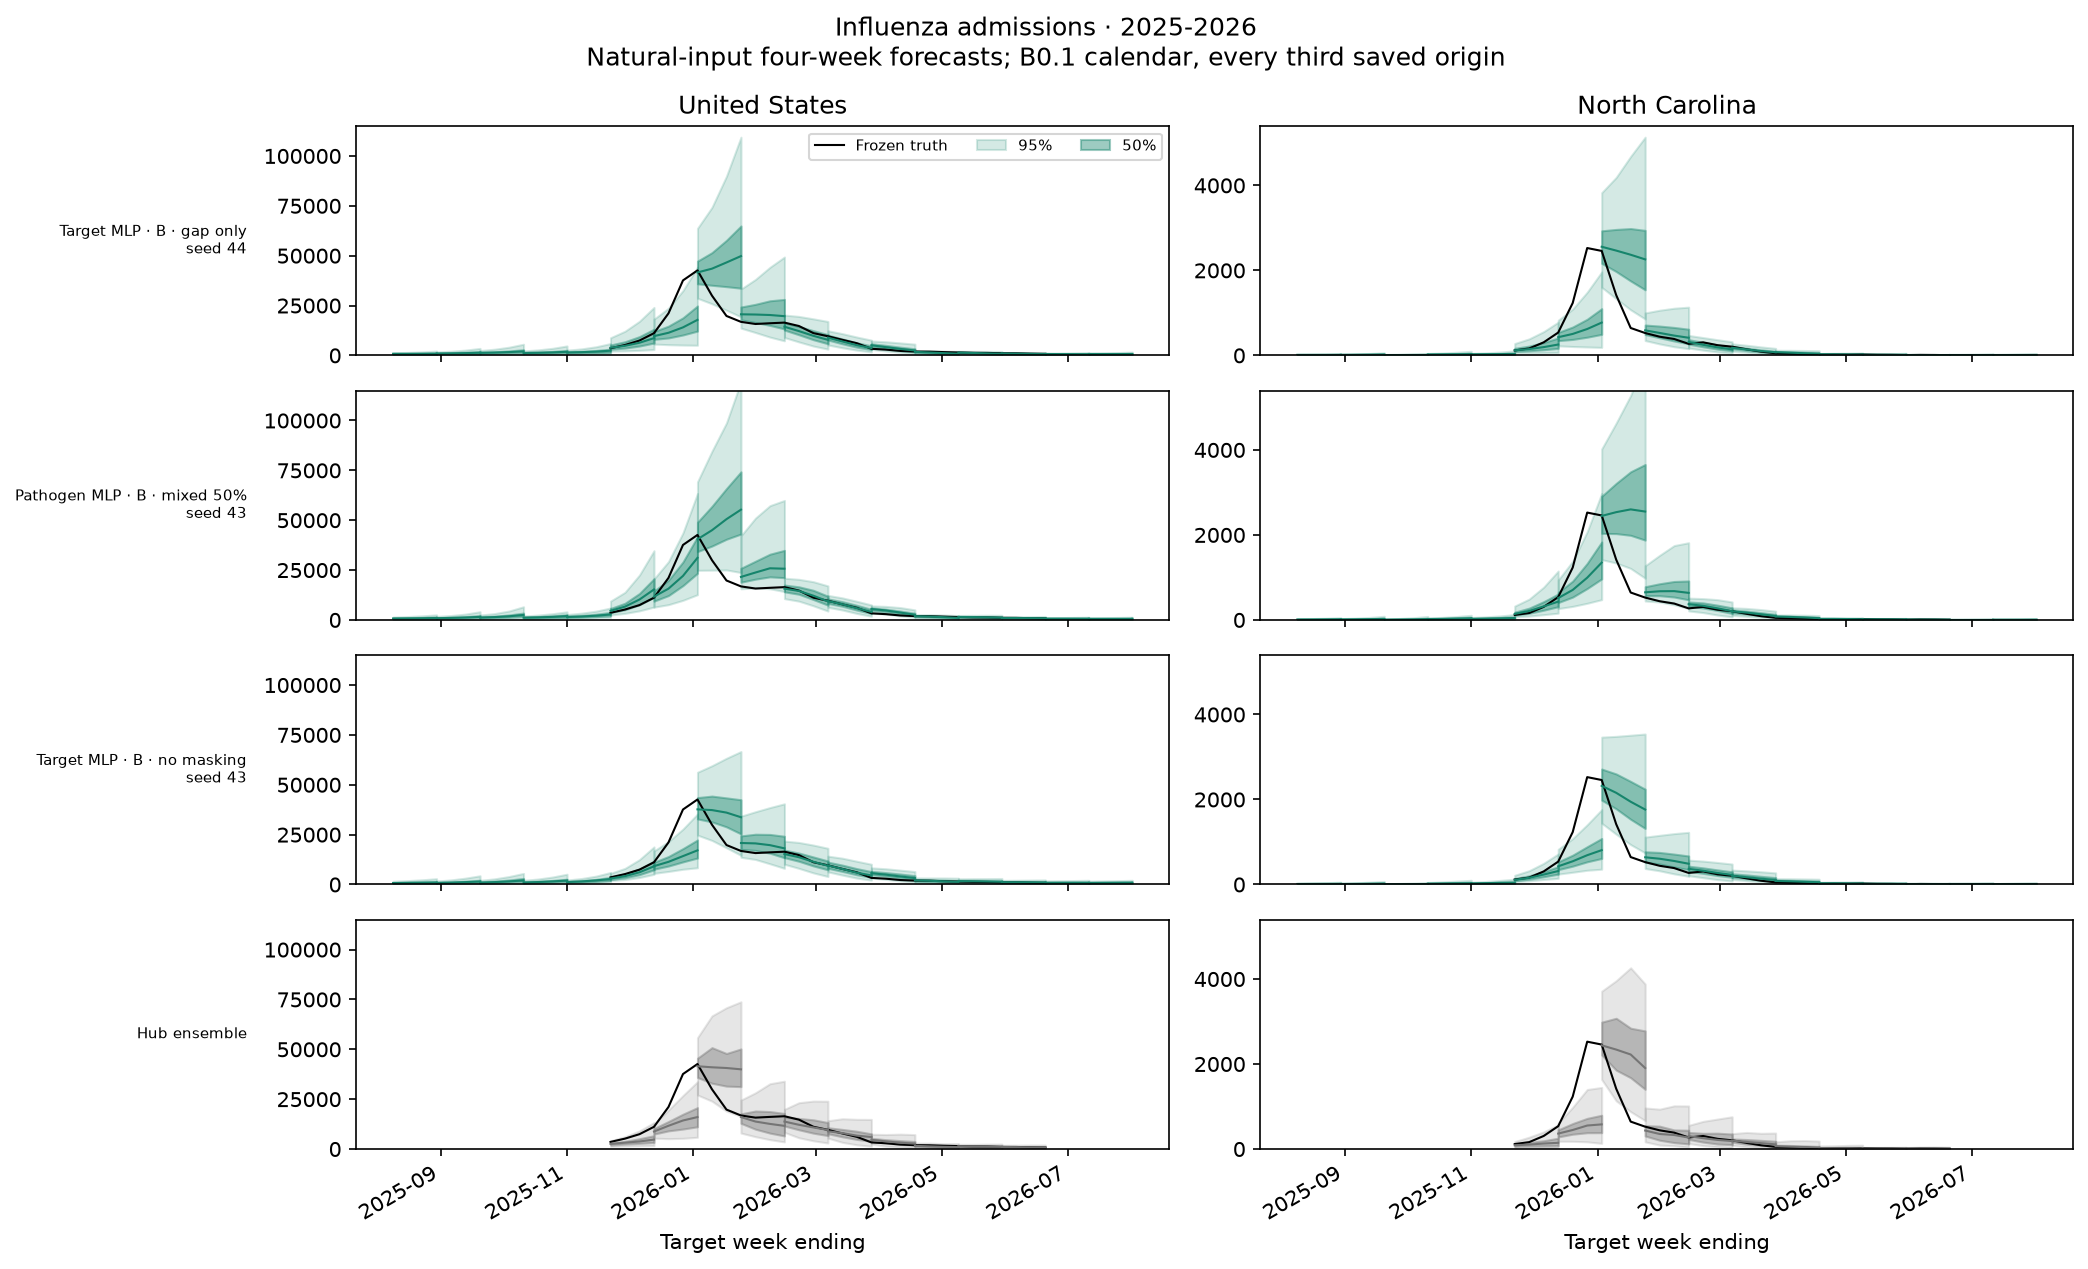
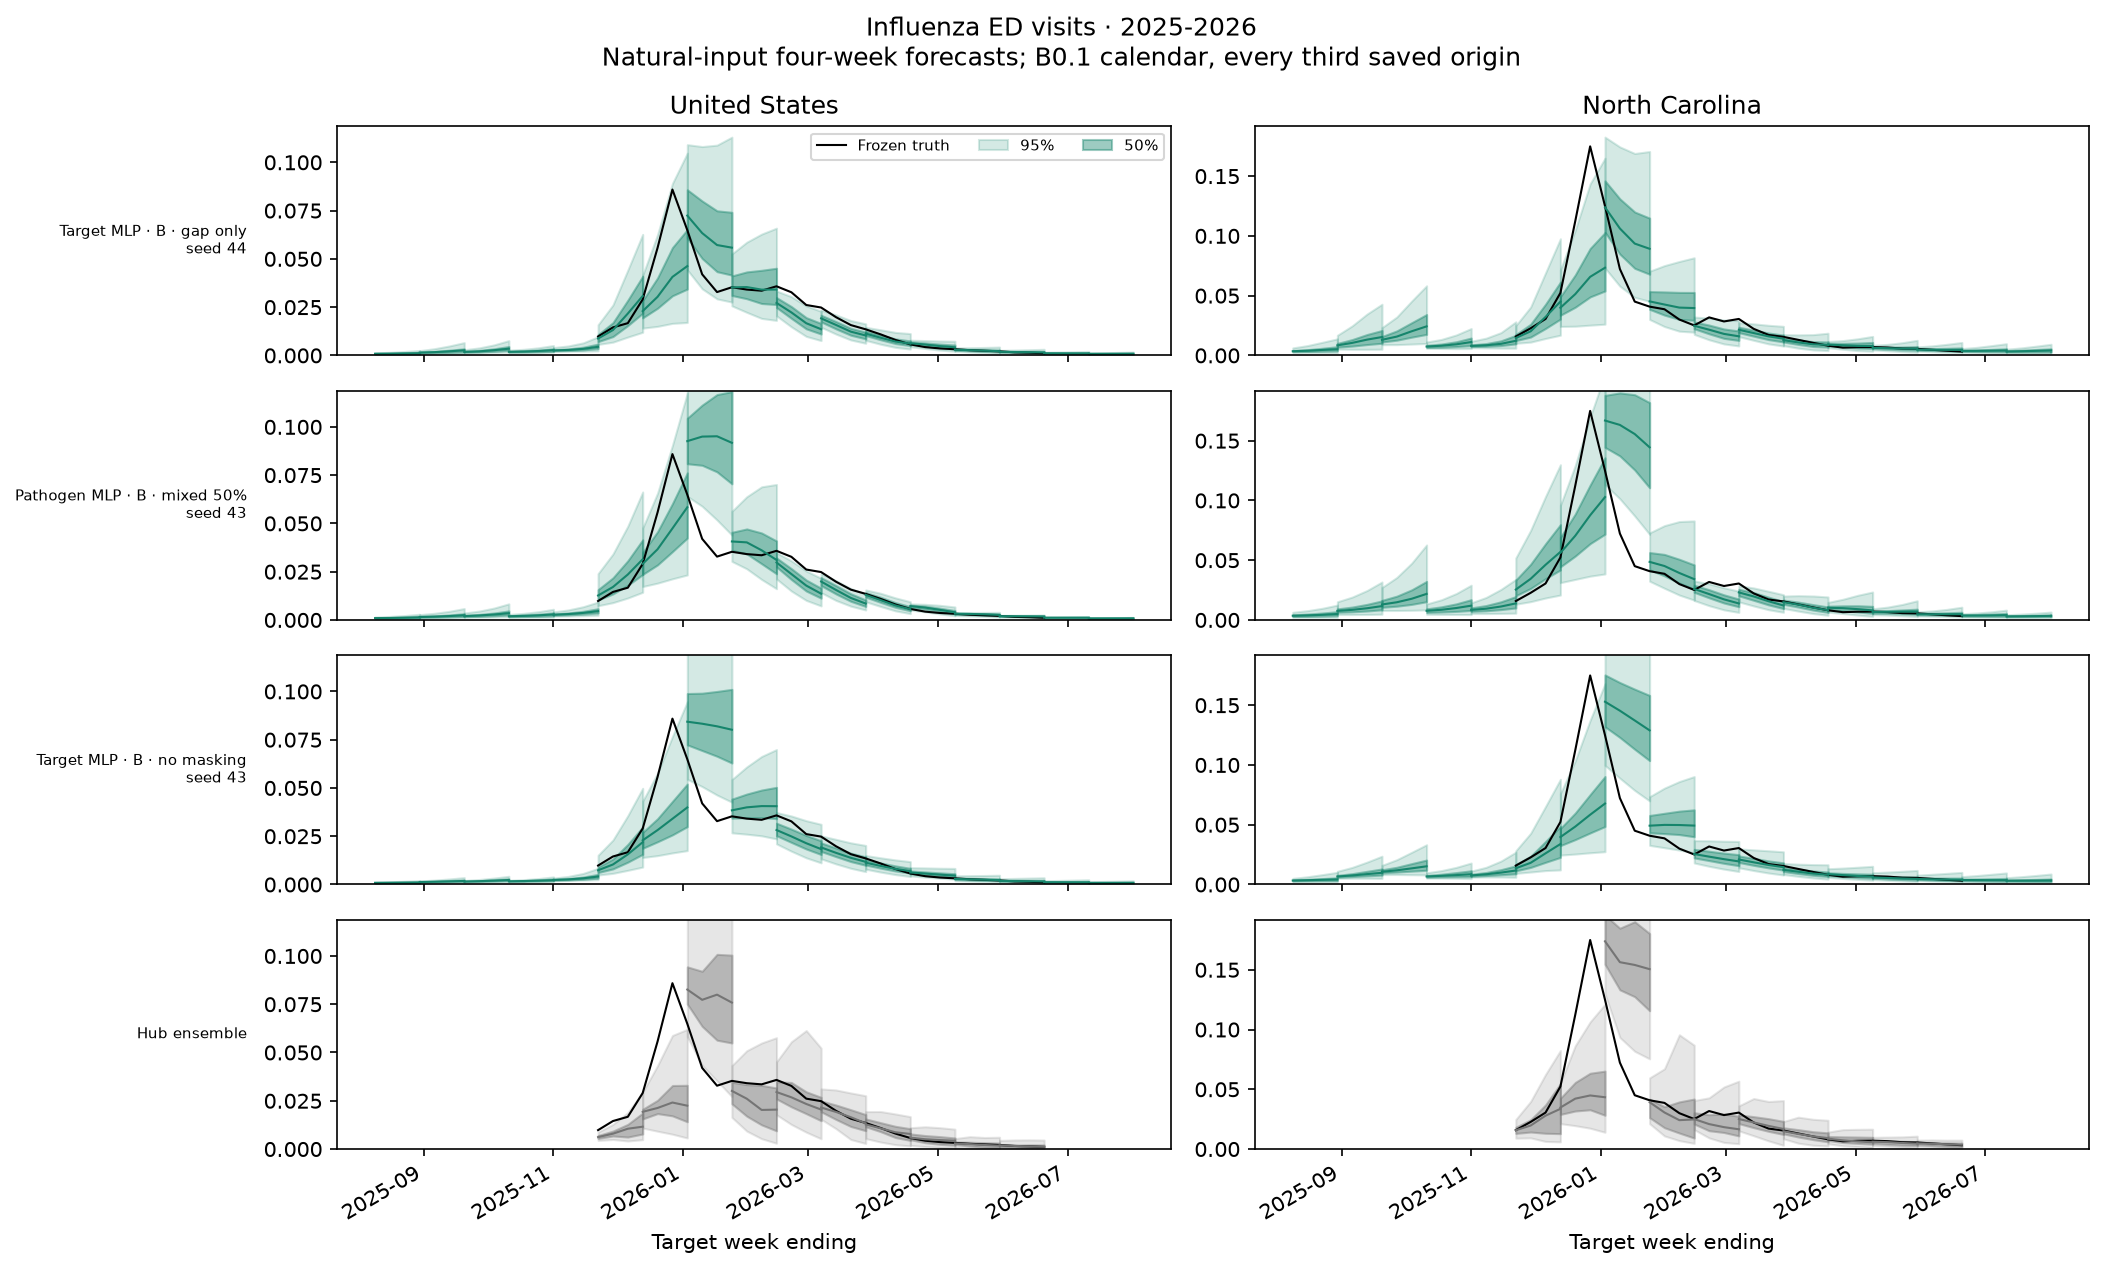
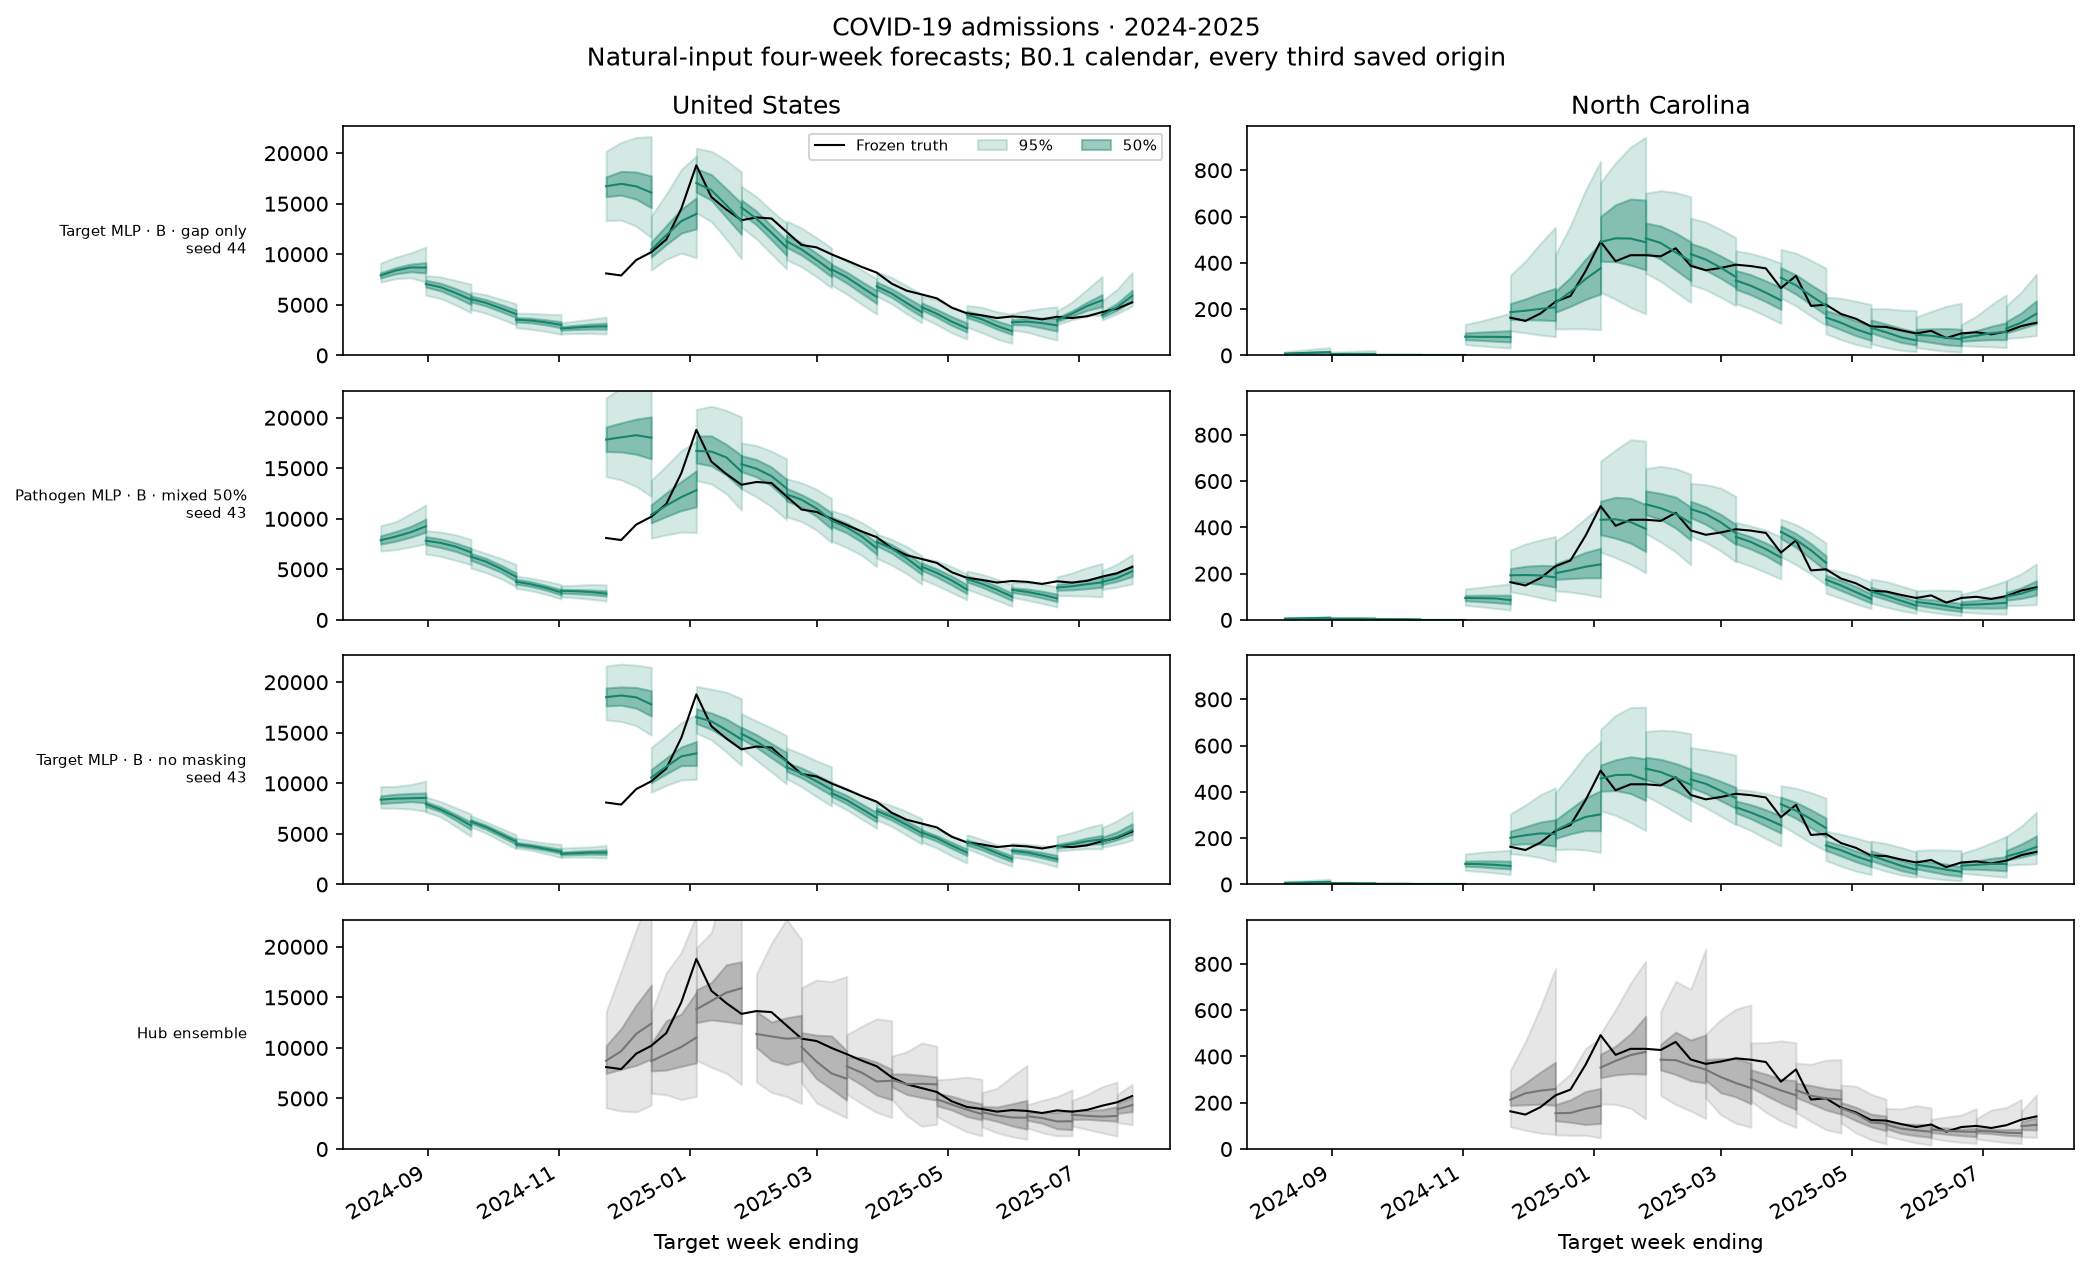
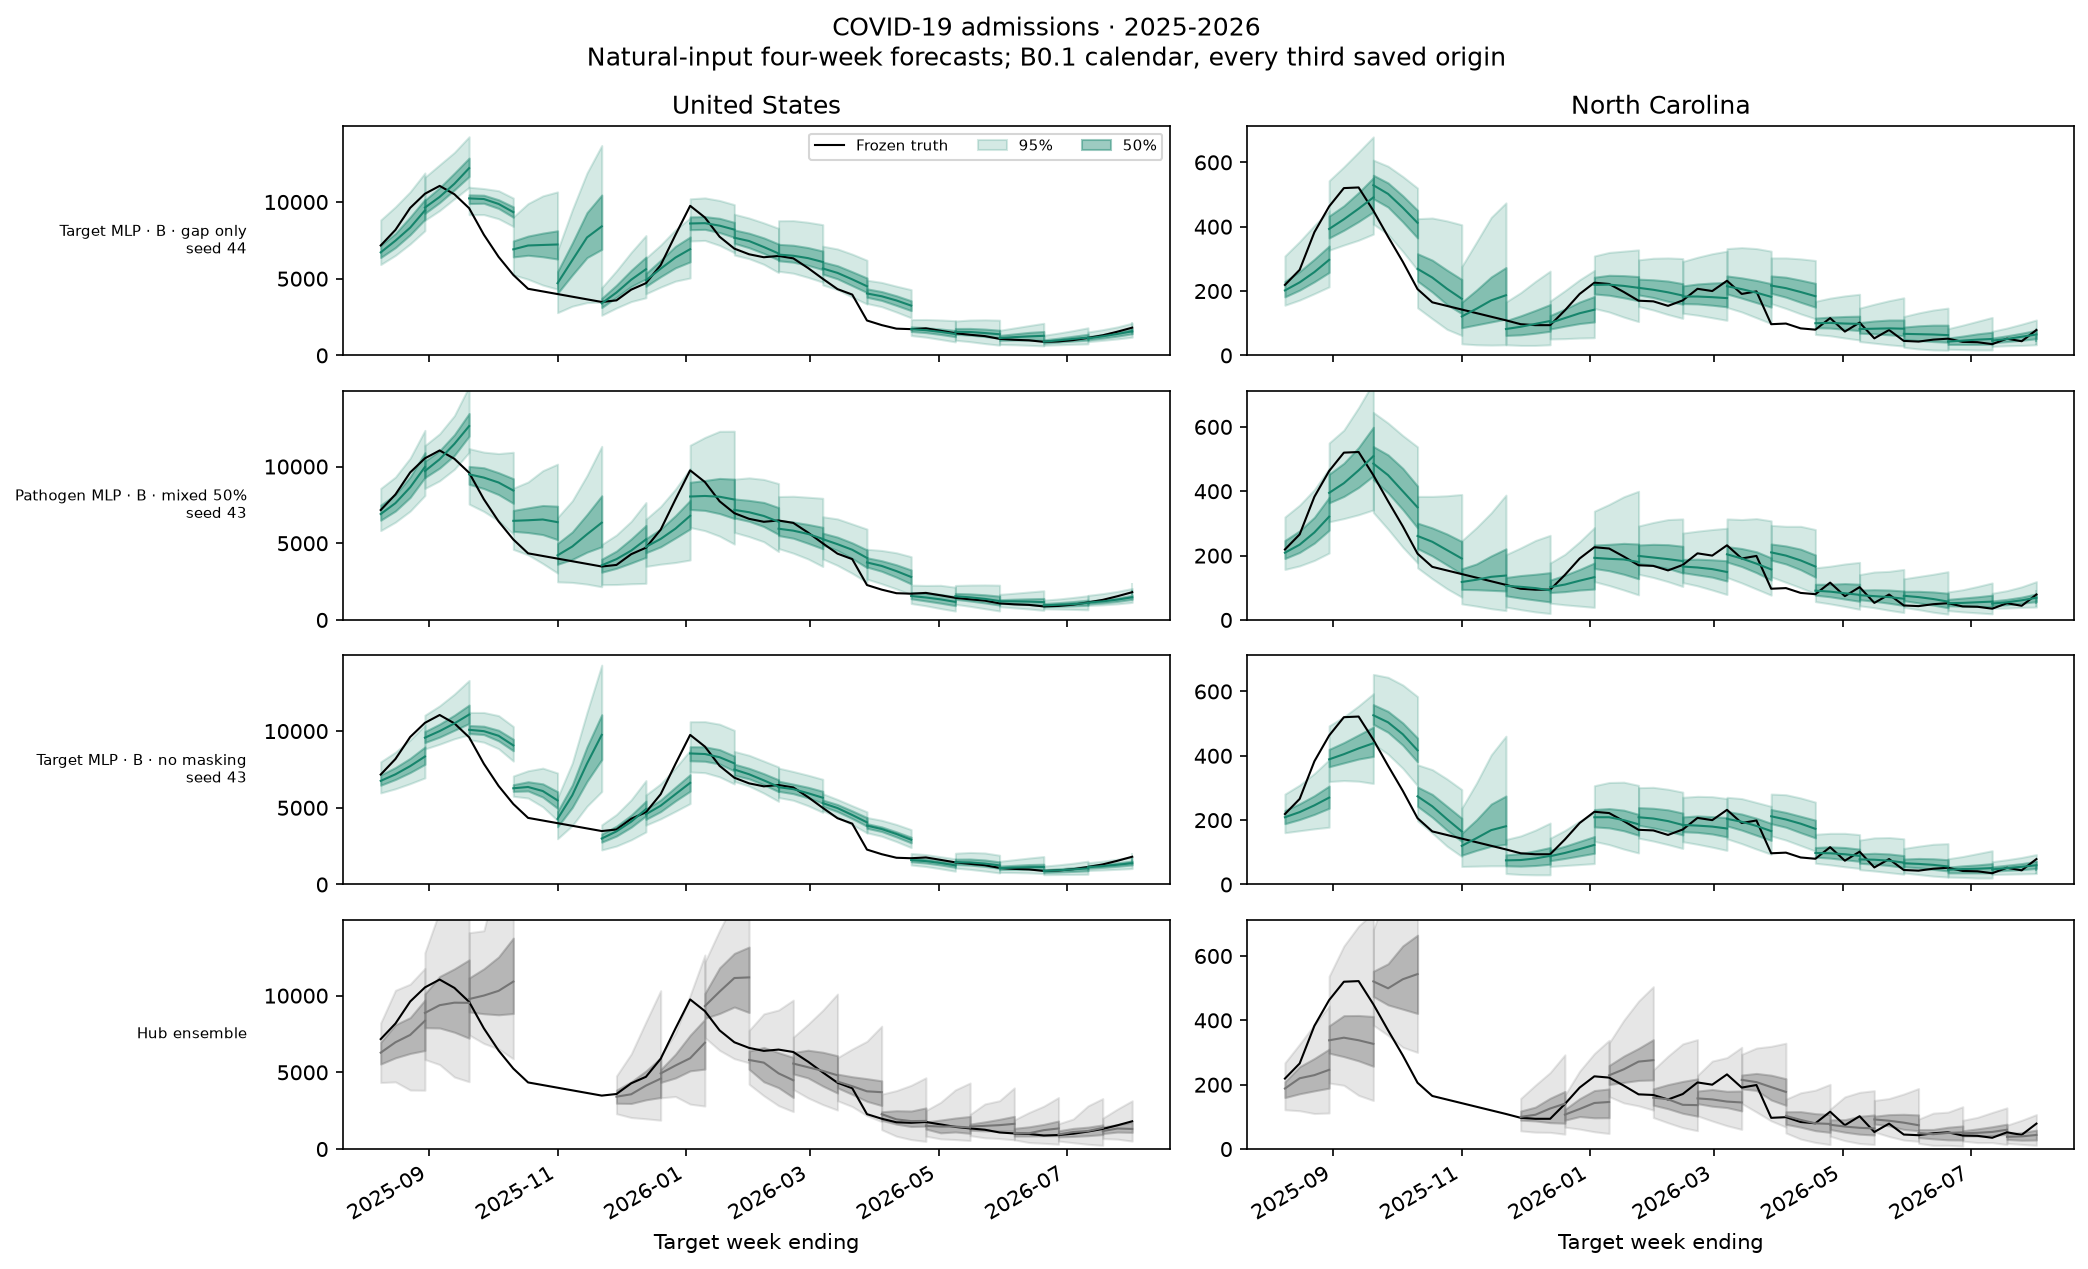
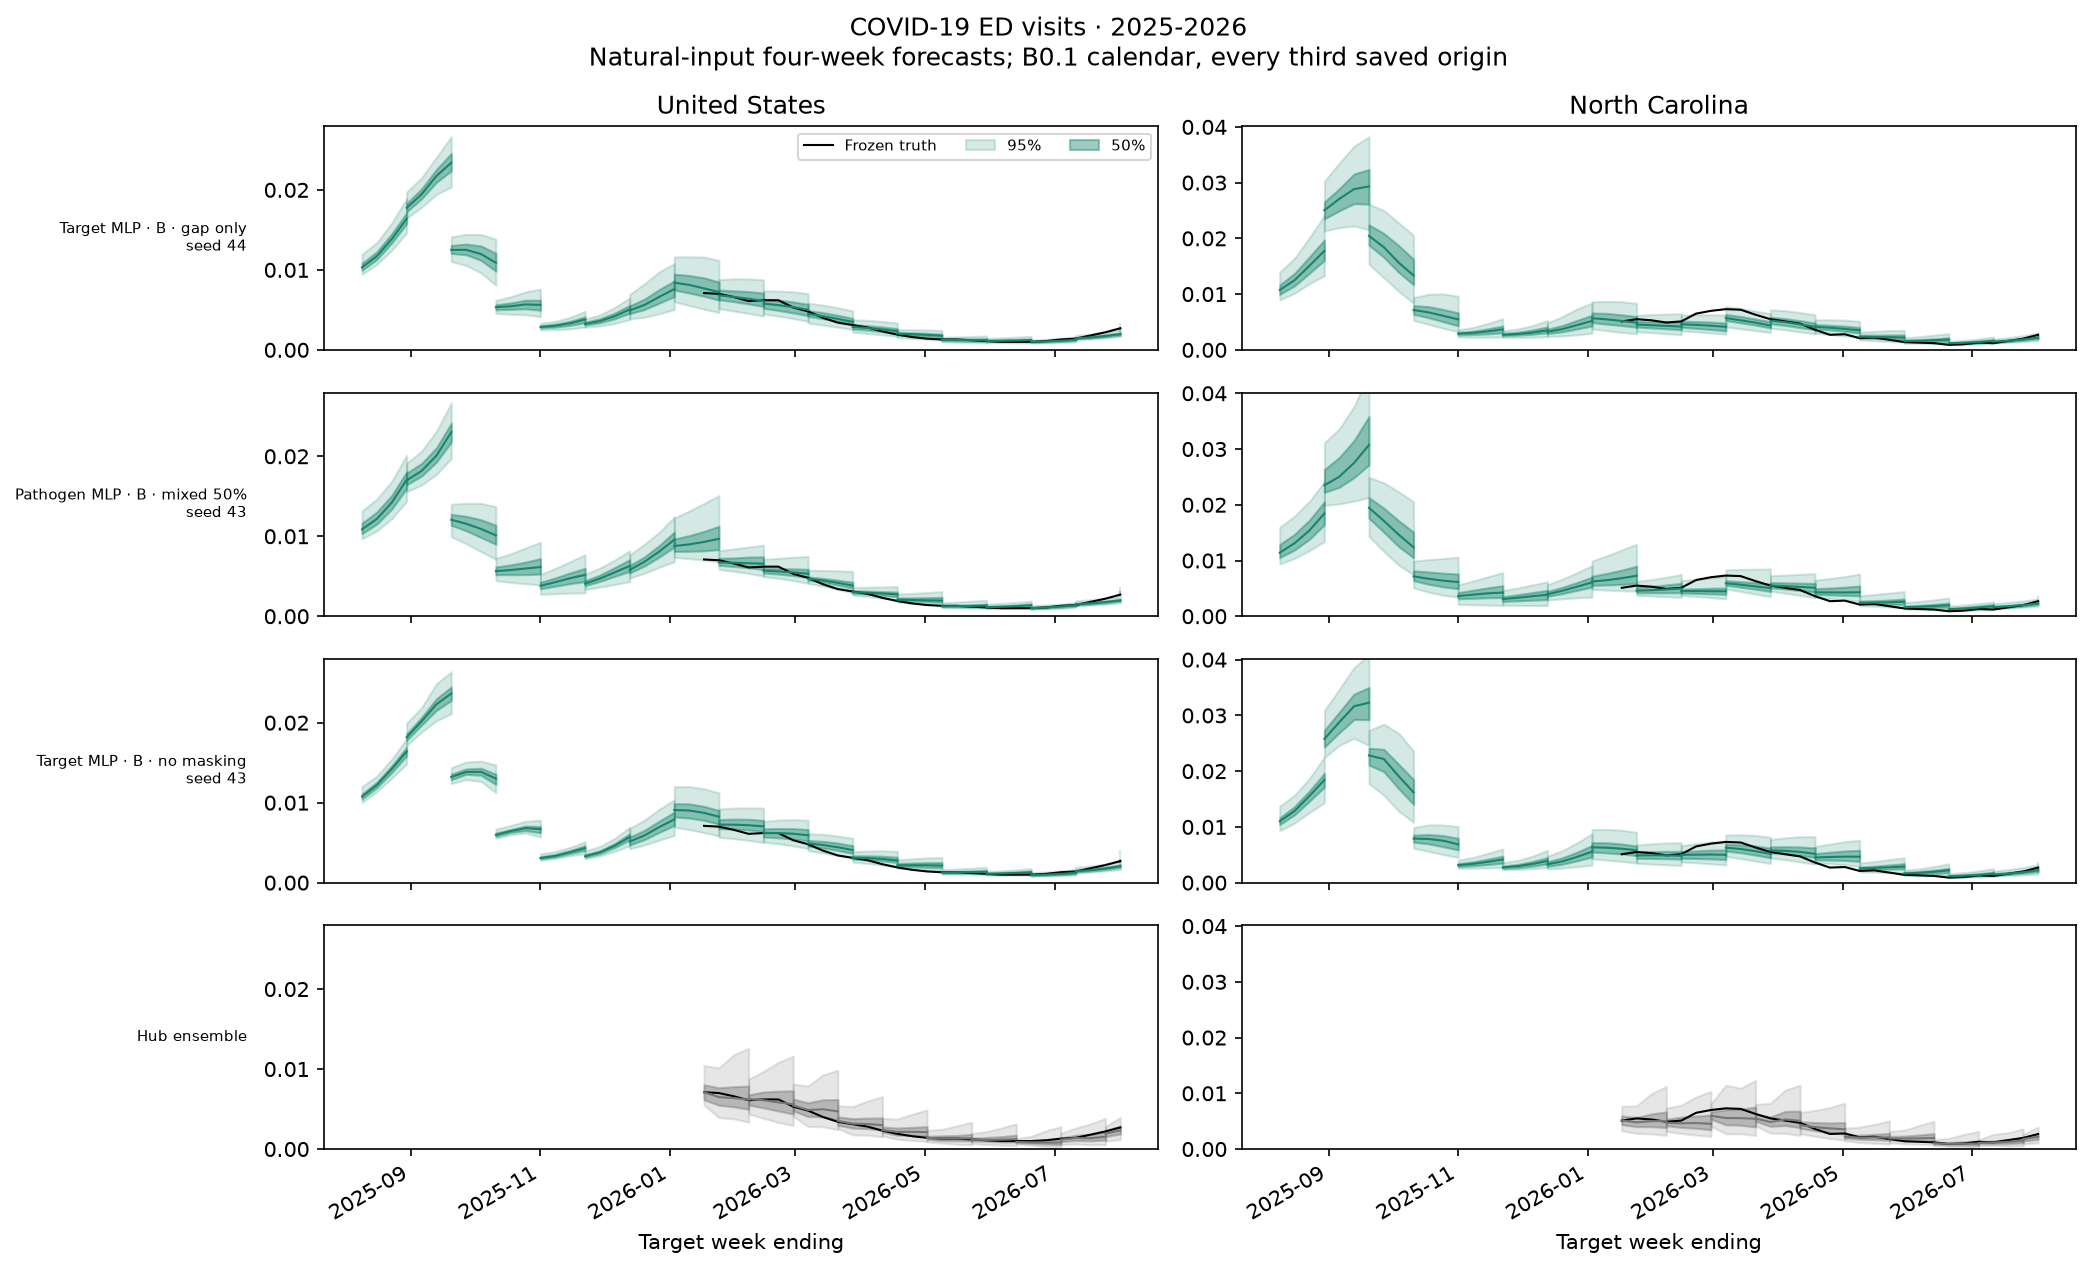
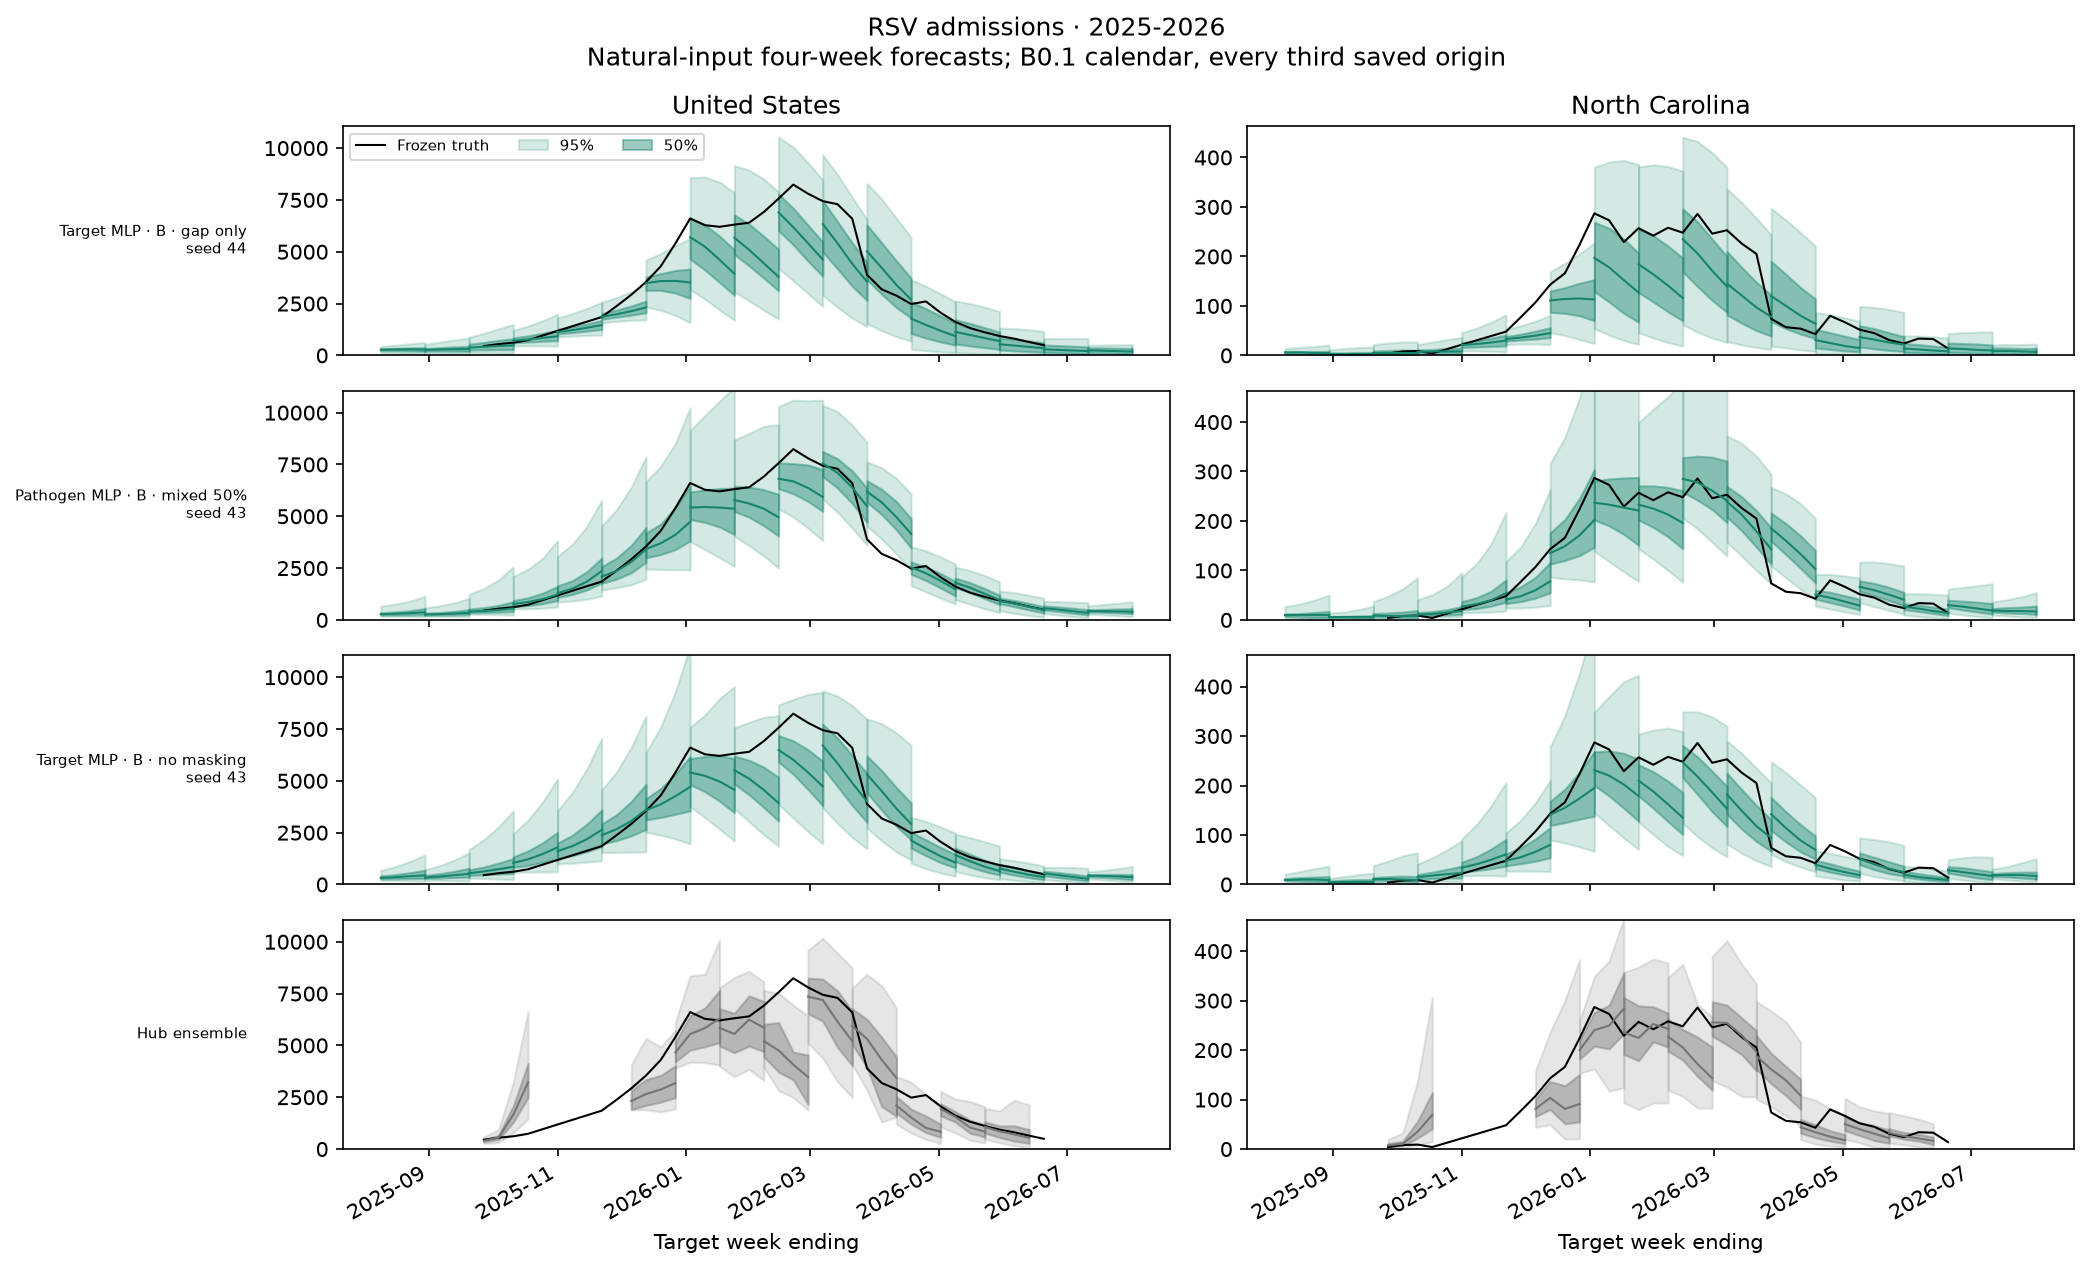
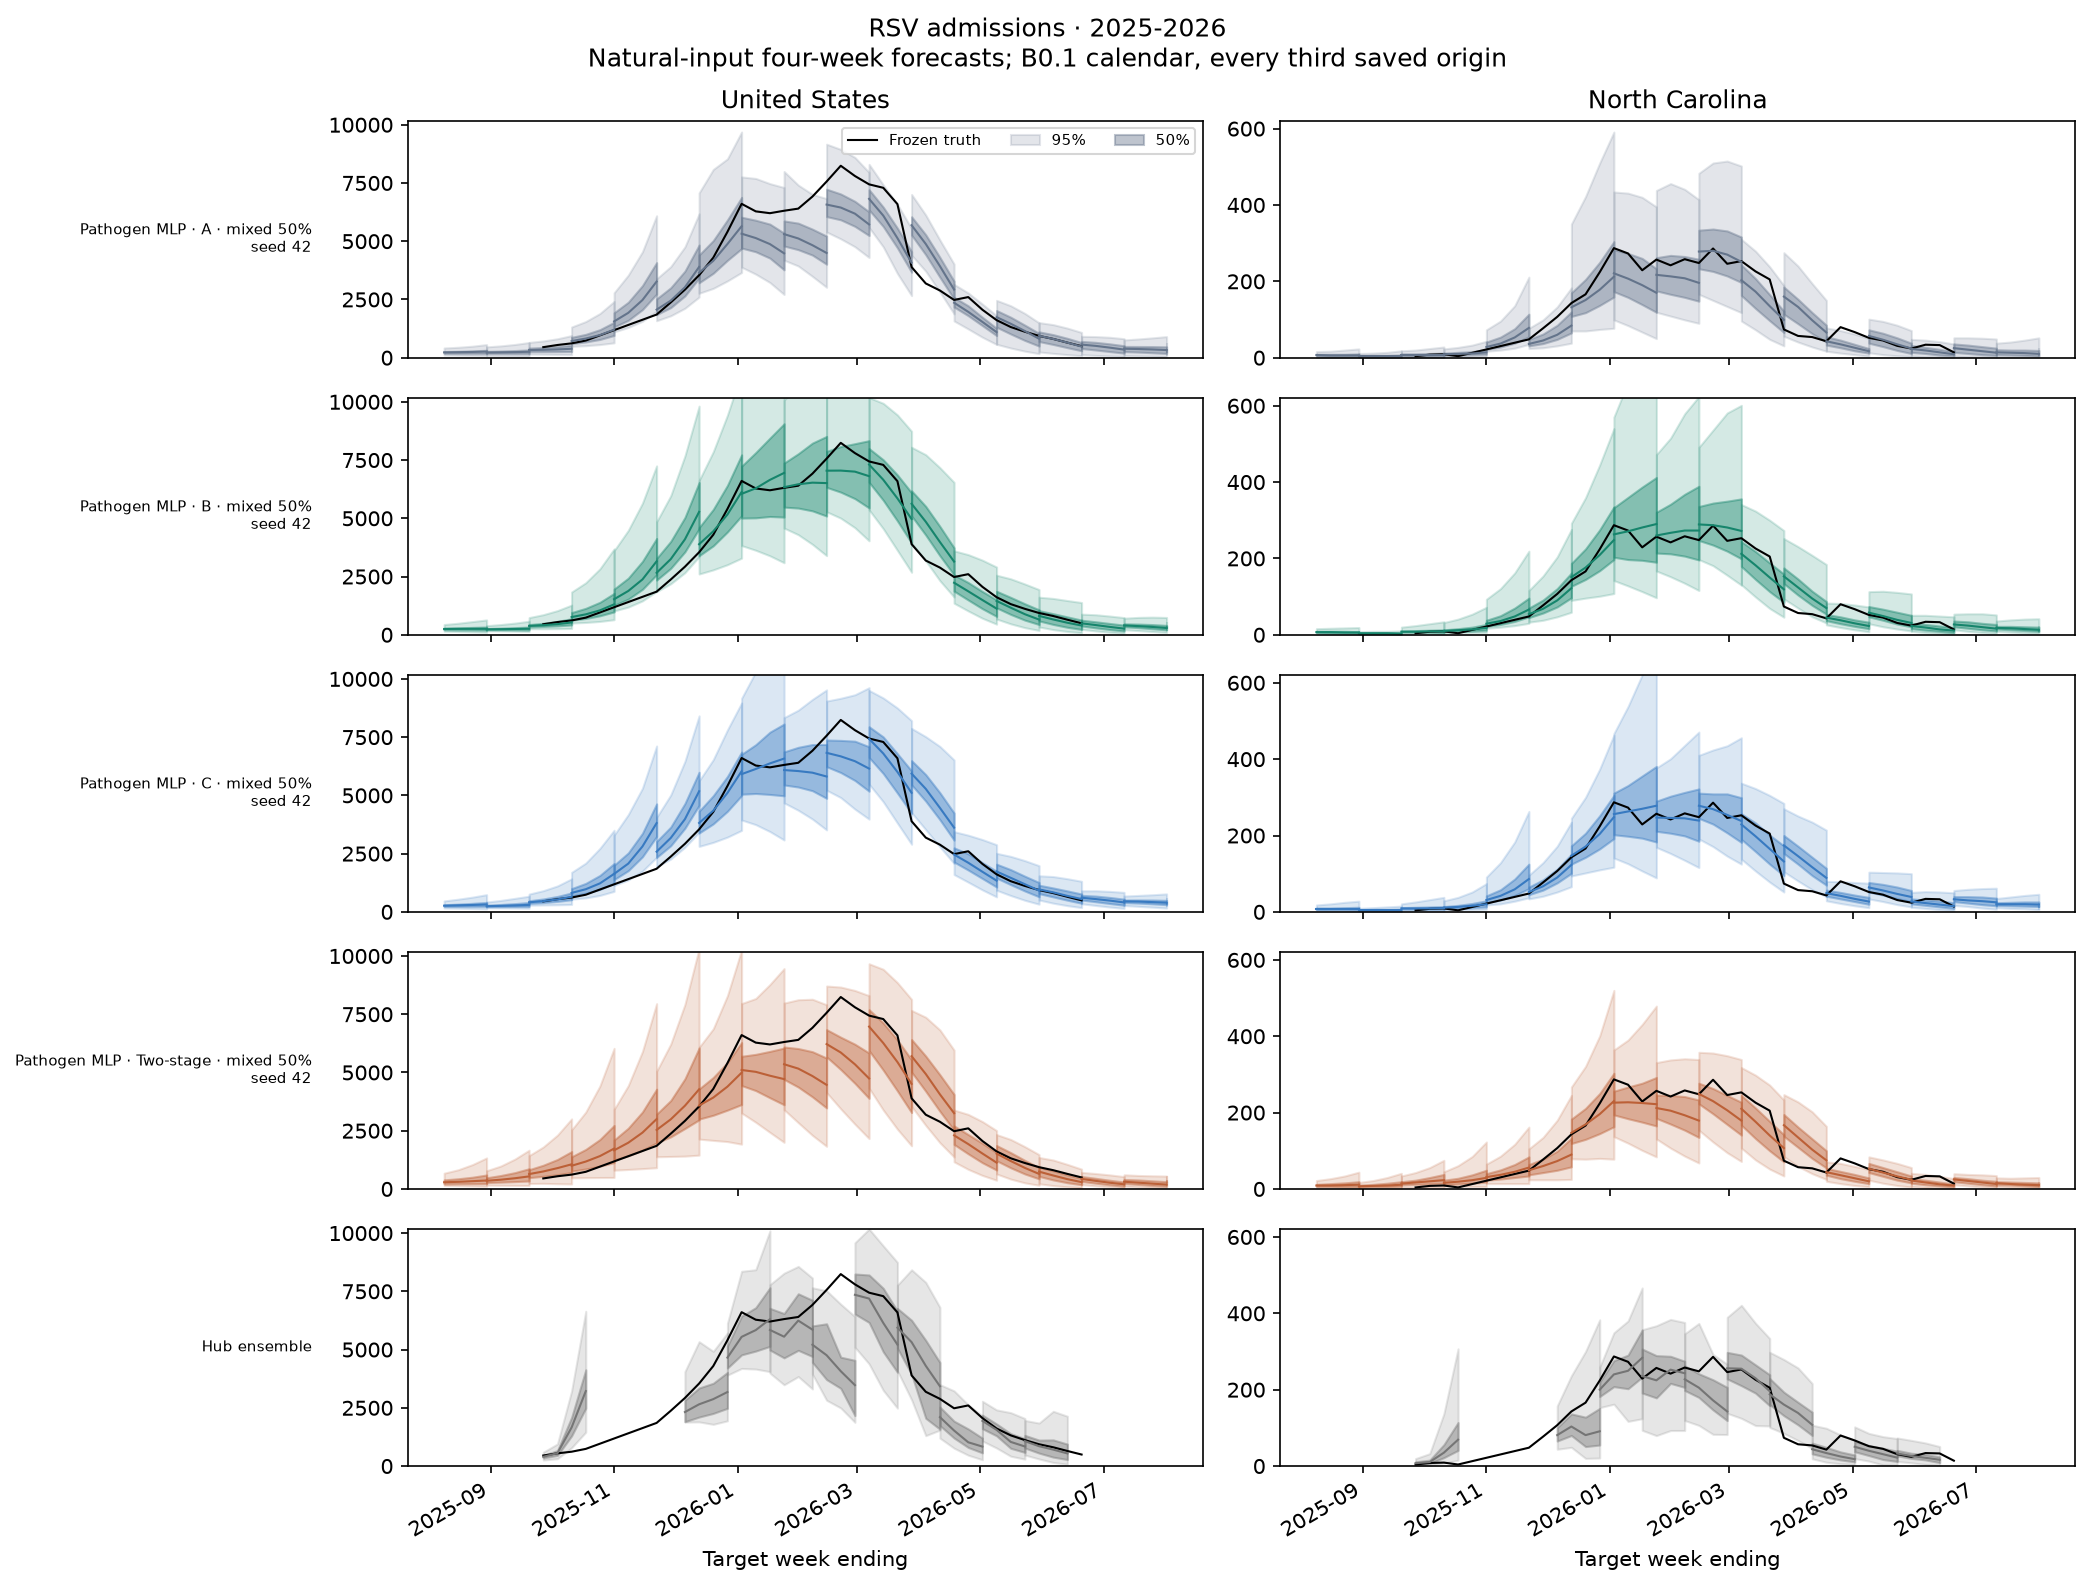
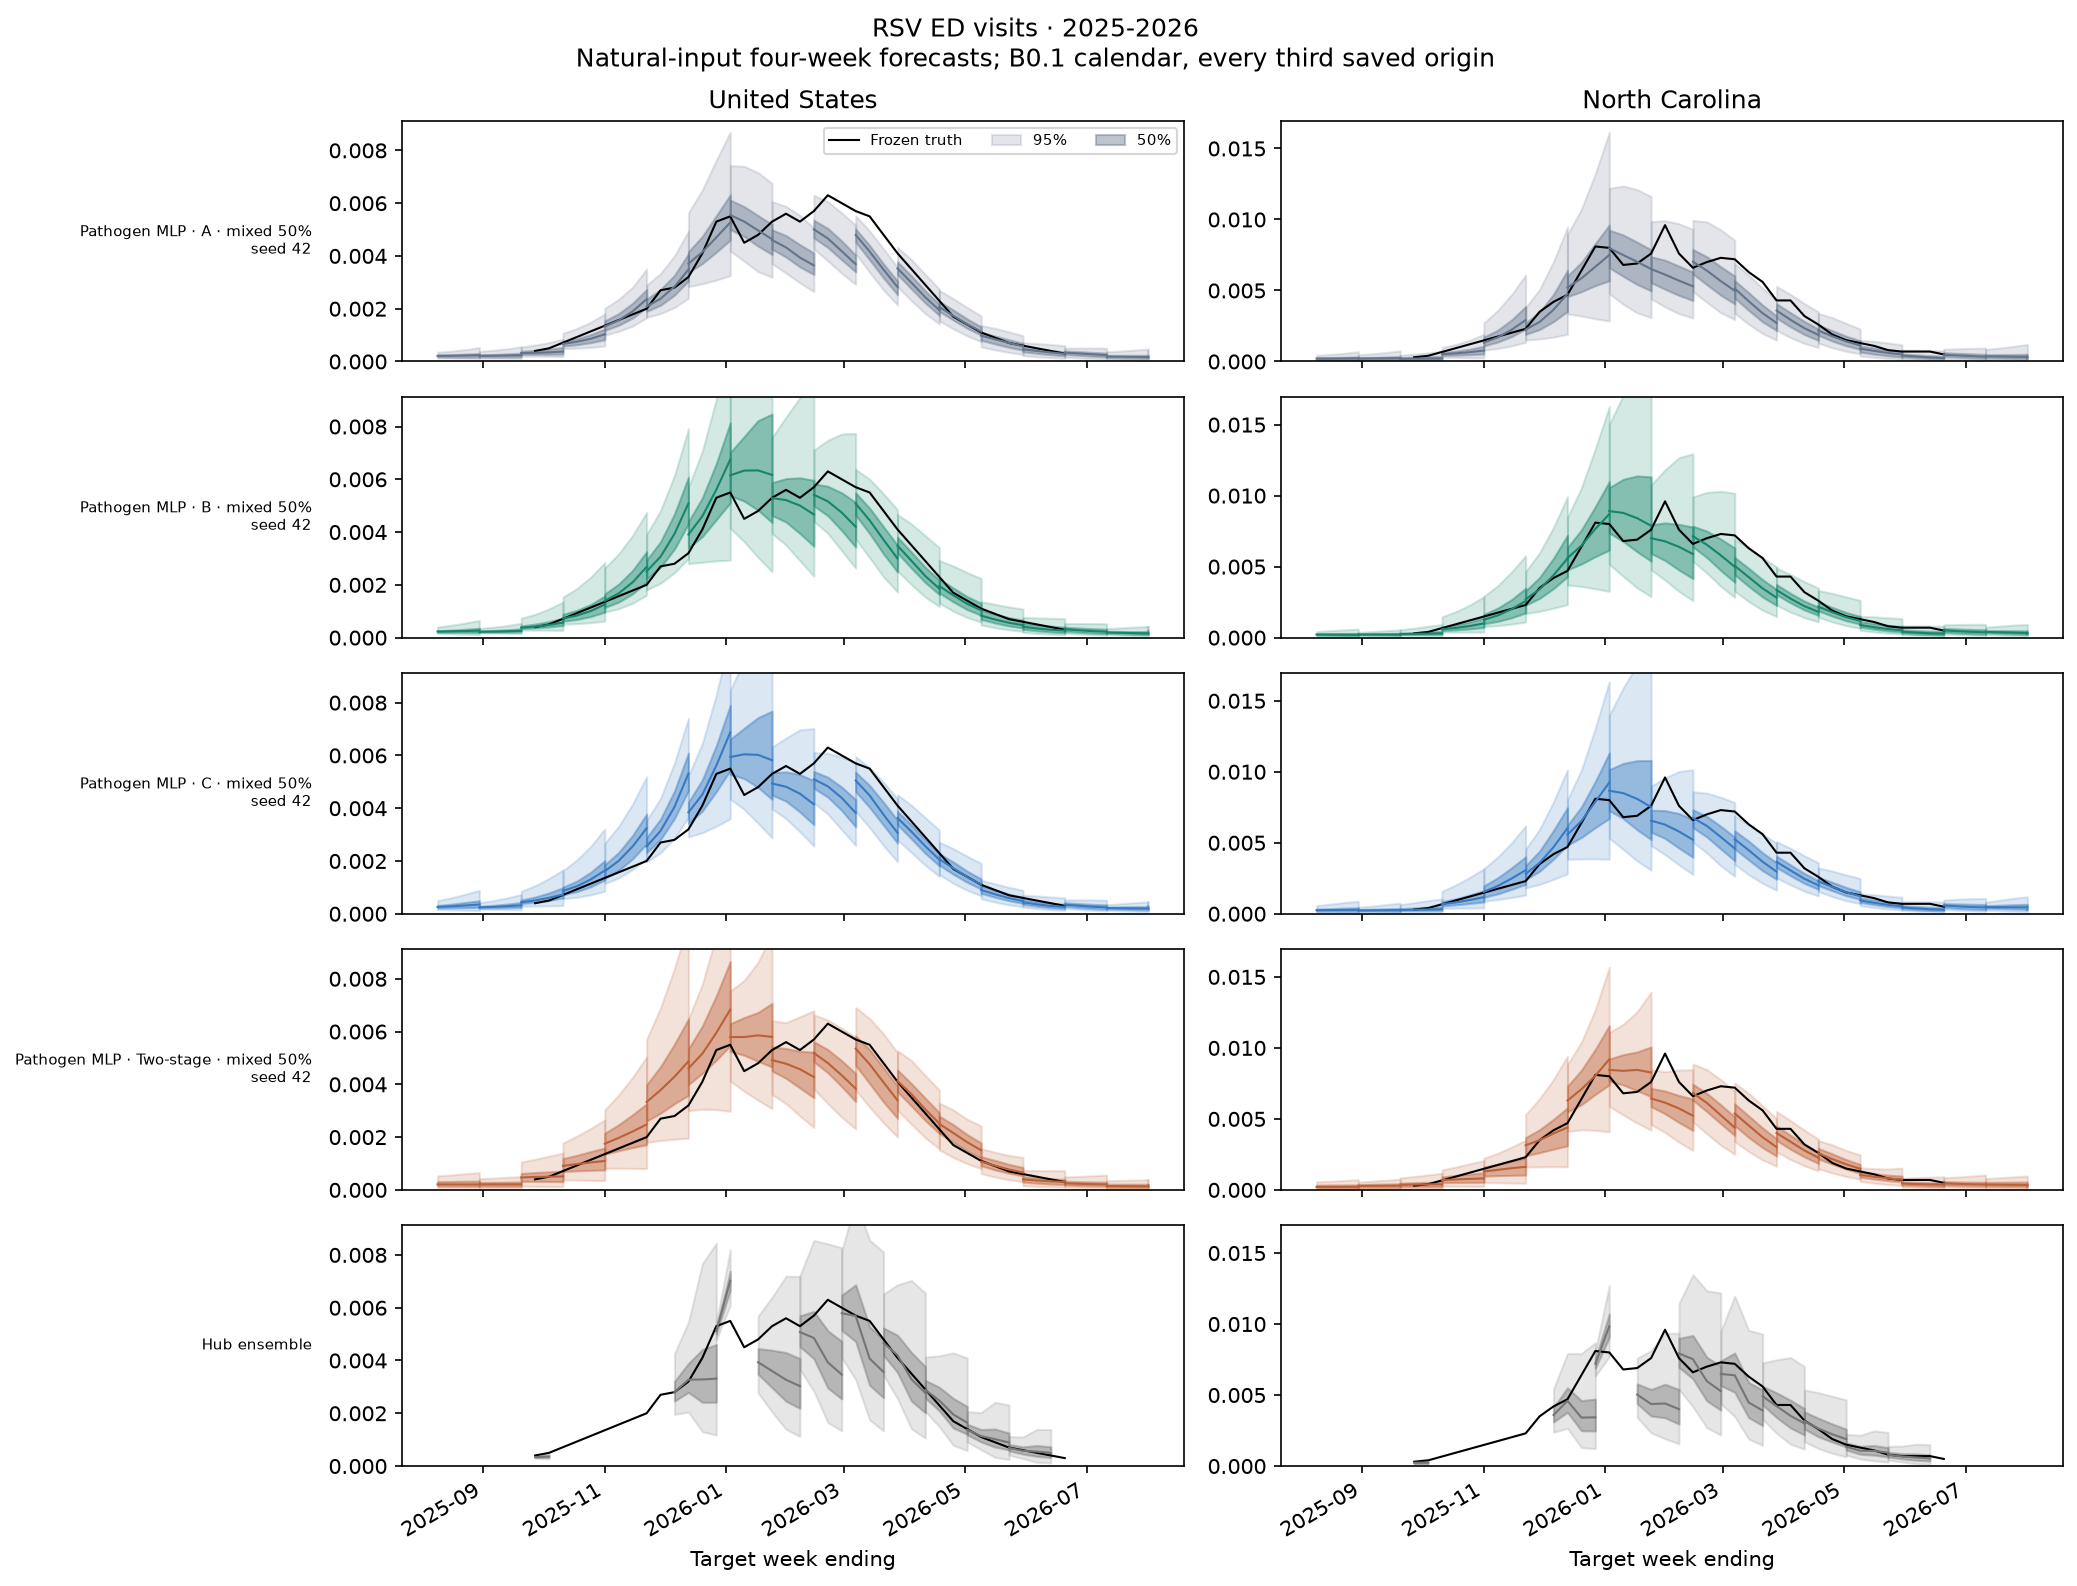
- Fan examples use US and North Carolina and a stated seed selection rule. No result is inferred from visual inspection of the plots.
- Completed attempts are resolved newest-complete first from manager records; saved score tables must have identical frozen support. Models are not refitted or rescored to create this page.
- Standalone nowcast ranking is omitted: the existing cross-formulation scorer rejects mismatched nowcast cell support. Forecast skill does not establish nowcast accuracy; those scores need a separate common-support comparison against persistence, not the Hub ensemble.
- B0.1 is context, not a controlled comparison: input histories and evaluation draw budgets differ. This page does not attribute the B0/B1 score gap to one change.
300-epoch results and comparison
48/48 runs complete, generated 2026-09-17T22:20-04:00. This is a dated snapshot. The follow-up contains 16 configurations (four architectures × four formulations), all at mixed 50% masking, with seeds 42/43/44. Caps are maxima with patience 30, not fixed epoch counts. The original screen below also includes masking variants that were not repeated here, including its gap-only winner.
Ranking at cap 300
4/16 available configuration means beat the ensemble. Lower relative WIS is better; 1 is ensemble parity. Each seed is a complete three-season run. Incomplete configurations retain their seed counts; missing runs are not imputed.
| Configuration | Seeds / 3 | WIS ratio | Seed SD | States/DC | US |
|---|---|---|---|---|---|
| Pathogen MLP · B · mixed 50% | 3 | 0.941 | 0.059 | 0.953 | 0.890 |
| Pathogen MLP · C · mixed 50% | 3 | 0.945 | 0.051 | 0.959 | 0.889 |
| Joint MLP · C · mixed 50% | 3 | 0.983 | 0.071 | 0.988 | 0.964 |
| Joint MLP · B · mixed 50% | 3 | 0.991 | 0.054 | 0.997 | 0.966 |
| Target MLP · C · mixed 50% | 3 | 1.003 | 0.023 | 1.013 | 0.961 |
| Target convolution · C · mixed 50% | 3 | 1.010 | 0.085 | 1.026 | 0.944 |
| Target MLP · B · mixed 50% | 3 | 1.029 | 0.071 | 1.036 | 0.997 |
| Target convolution · B · mixed 50% | 3 | 1.032 | 0.030 | 1.045 | 0.982 |
| Target MLP · A · mixed 50% | 3 | 1.038 | 0.029 | 1.038 | 1.037 |
| Target convolution · A · mixed 50% | 3 | 1.070 | 0.042 | 1.079 | 1.032 |
| Joint MLP · A · mixed 50% | 3 | 1.086 | 0.241 | 1.086 | 1.086 |
| Pathogen MLP · A · mixed 50% | 3 | 1.126 | 0.138 | 1.118 | 1.157 |
| Joint MLP · Two-stage · mixed 50% | 3 | 1.194 | 0.097 | 1.178 | 1.256 |
| Target MLP · Two-stage · mixed 50% | 3 | 1.203 | 0.056 | 1.198 | 1.225 |
| Target convolution · Two-stage · mixed 50% | 3 | 1.215 | 0.043 | 1.218 | 1.203 |
| Pathogen MLP · Two-stage · mixed 50% | 3 | 1.292 | 0.272 | 1.293 | 1.292 |
Ranking CSV · Per-seed scores.
What changed from the first screen
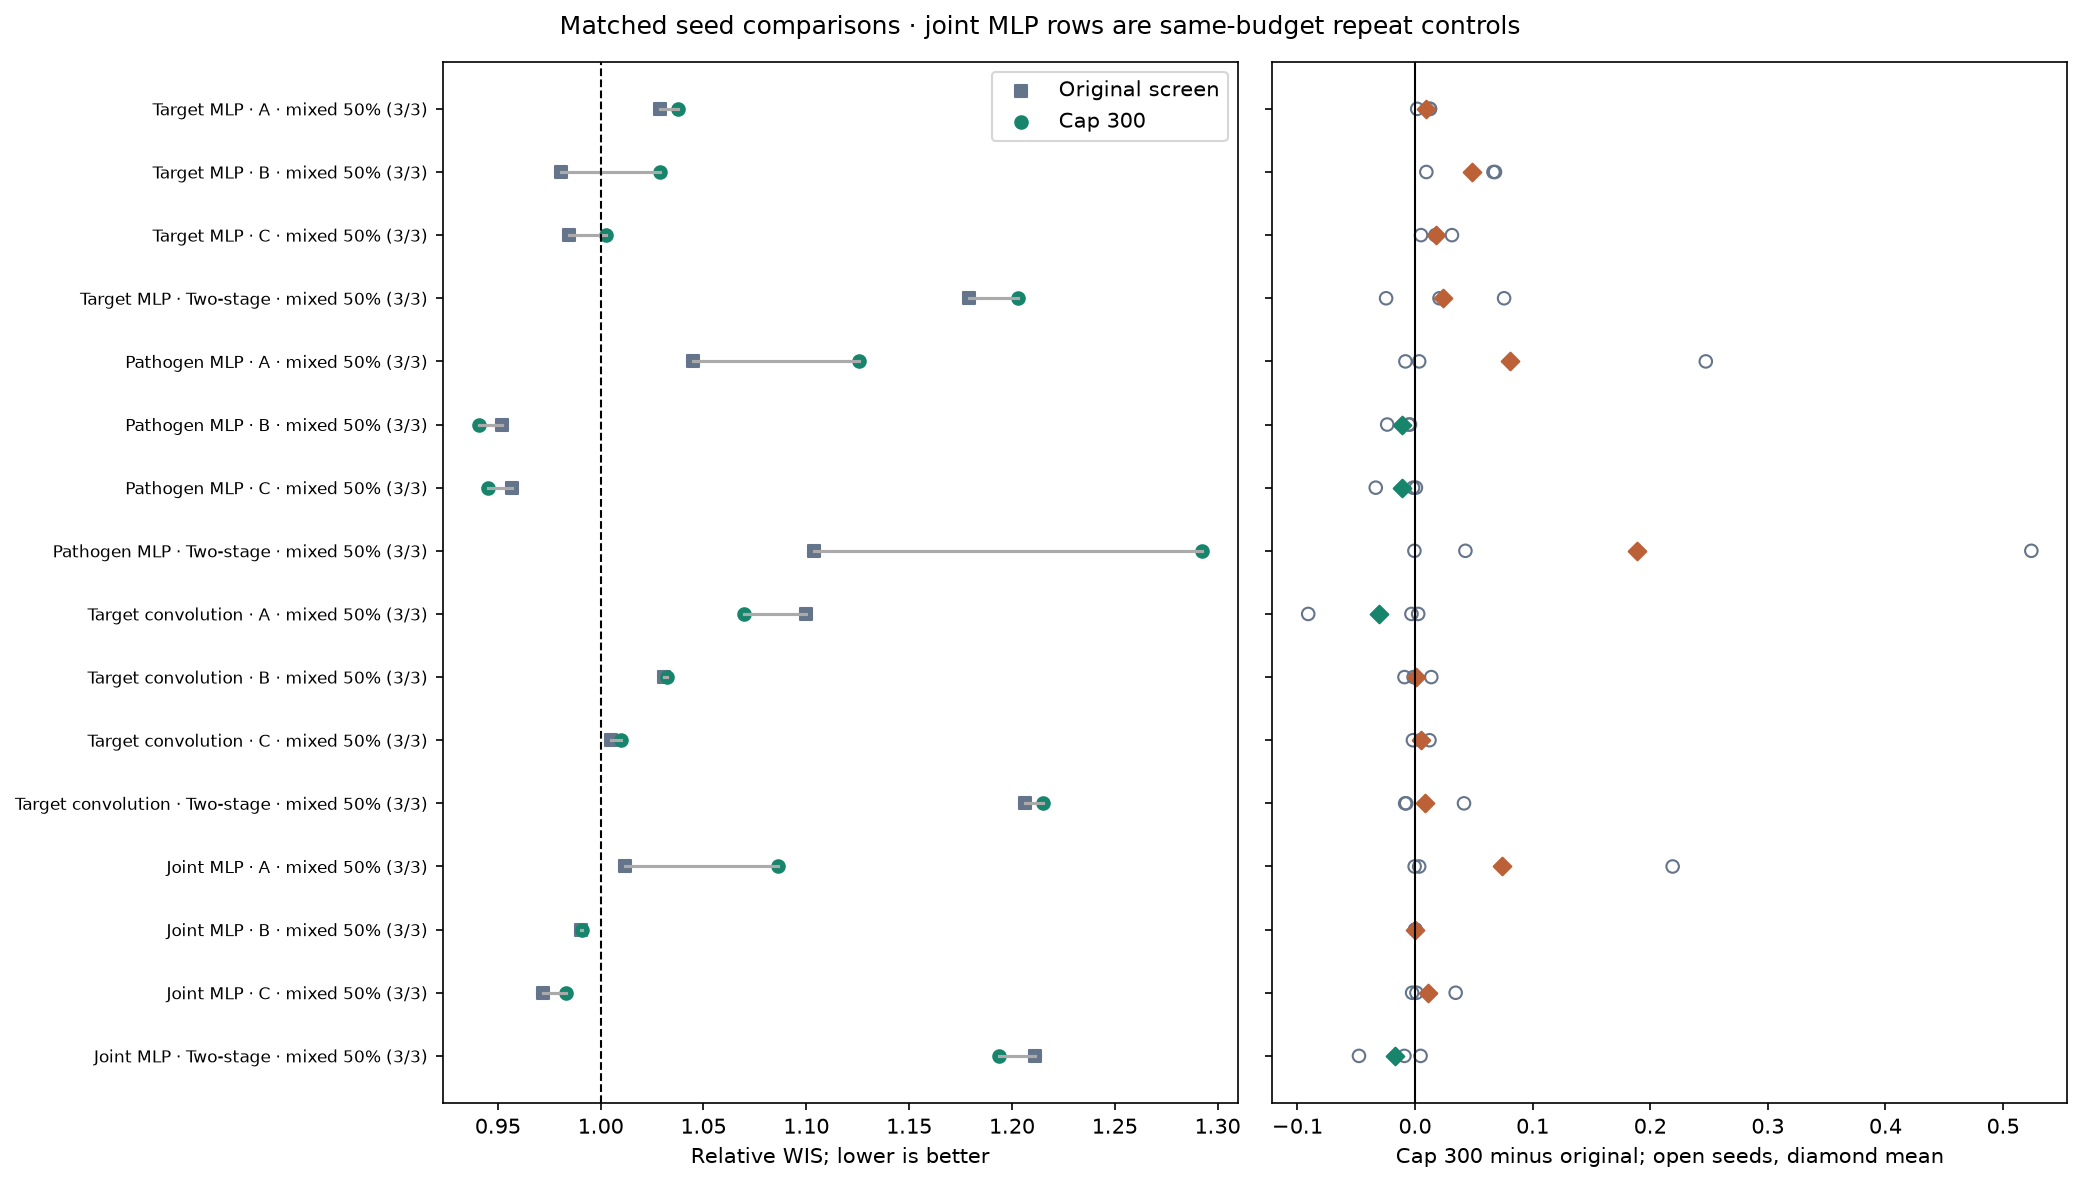
Every row below uses the same architecture, formulation, masking, and completed seed on both sides. Input hashes and scored target/season/location/horizon support match. The target MLP, pathogen MLP, and target convolution change cap 100 → 300. Joint MLP was already capped at 300: its rows are repeat controls. Negative changes favor the follow-up; seed SD is descriptive, not a confidence interval.
| Configuration | Paired seeds | Original screen | Cap 300 | Δ WIS | Seed Δ SD | Seeds improved |
|---|---|---|---|---|---|---|
| Target MLP · A · mixed 50% | 3 | 1.029 | 1.038 | 0.009 | 0.006 | 0 |
| Target MLP · B · mixed 50% | 3 | 0.980 | 1.029 | 0.048 | 0.033 | 0 |
| Target MLP · C · mixed 50% | 3 | 0.985 | 1.003 | 0.018 | 0.013 | 0 |
| Target MLP · Two-stage · mixed 50% | 3 | 1.179 | 1.203 | 0.024 | 0.050 | 1 |
| Pathogen MLP · A · mixed 50% | 3 | 1.045 | 1.126 | 0.081 | 0.144 | 1 |
| Pathogen MLP · B · mixed 50% | 3 | 0.952 | 0.941 | -0.011 | 0.011 | 3 |
| Pathogen MLP · C · mixed 50% | 3 | 0.957 | 0.945 | -0.011 | 0.019 | 2 |
| Pathogen MLP · Two-stage · mixed 50% | 3 | 1.104 | 1.292 | 0.189 | 0.291 | 1 |
| Target convolution · A · mixed 50% | 3 | 1.100 | 1.070 | -0.030 | 0.052 | 2 |
| Target convolution · B · mixed 50% | 3 | 1.031 | 1.032 | 0.001 | 0.012 | 2 |
| Target convolution · C · mixed 50% | 3 | 1.005 | 1.010 | 0.005 | 0.007 | 1 |
| Target convolution · Two-stage · mixed 50% | 3 | 1.206 | 1.215 | 0.009 | 0.029 | 2 |
| Joint MLP · A · mixed 50% | 3 | 1.012 | 1.086 | 0.074 | 0.126 | 1 |
| Joint MLP · B · mixed 50% | 3 | 0.990 | 0.991 | 0.000 | 0.000 | 0 |
| Joint MLP · C · mixed 50% | 3 | 0.972 | 0.983 | 0.011 | 0.020 | 1 |
| Joint MLP · Two-stage · mixed 50% | 3 | 1.211 | 1.194 | -0.017 | 0.027 | 2 |
Pathogen B and C remain the strongest candidates in this follow-up. B changes from 0.952 to 0.941, improving in 3/3 seeds; C changes from 0.957 to 0.945, improving in 2/3. Their small gap does not establish a reliable preference between flags alone and auxiliary nowcasting.
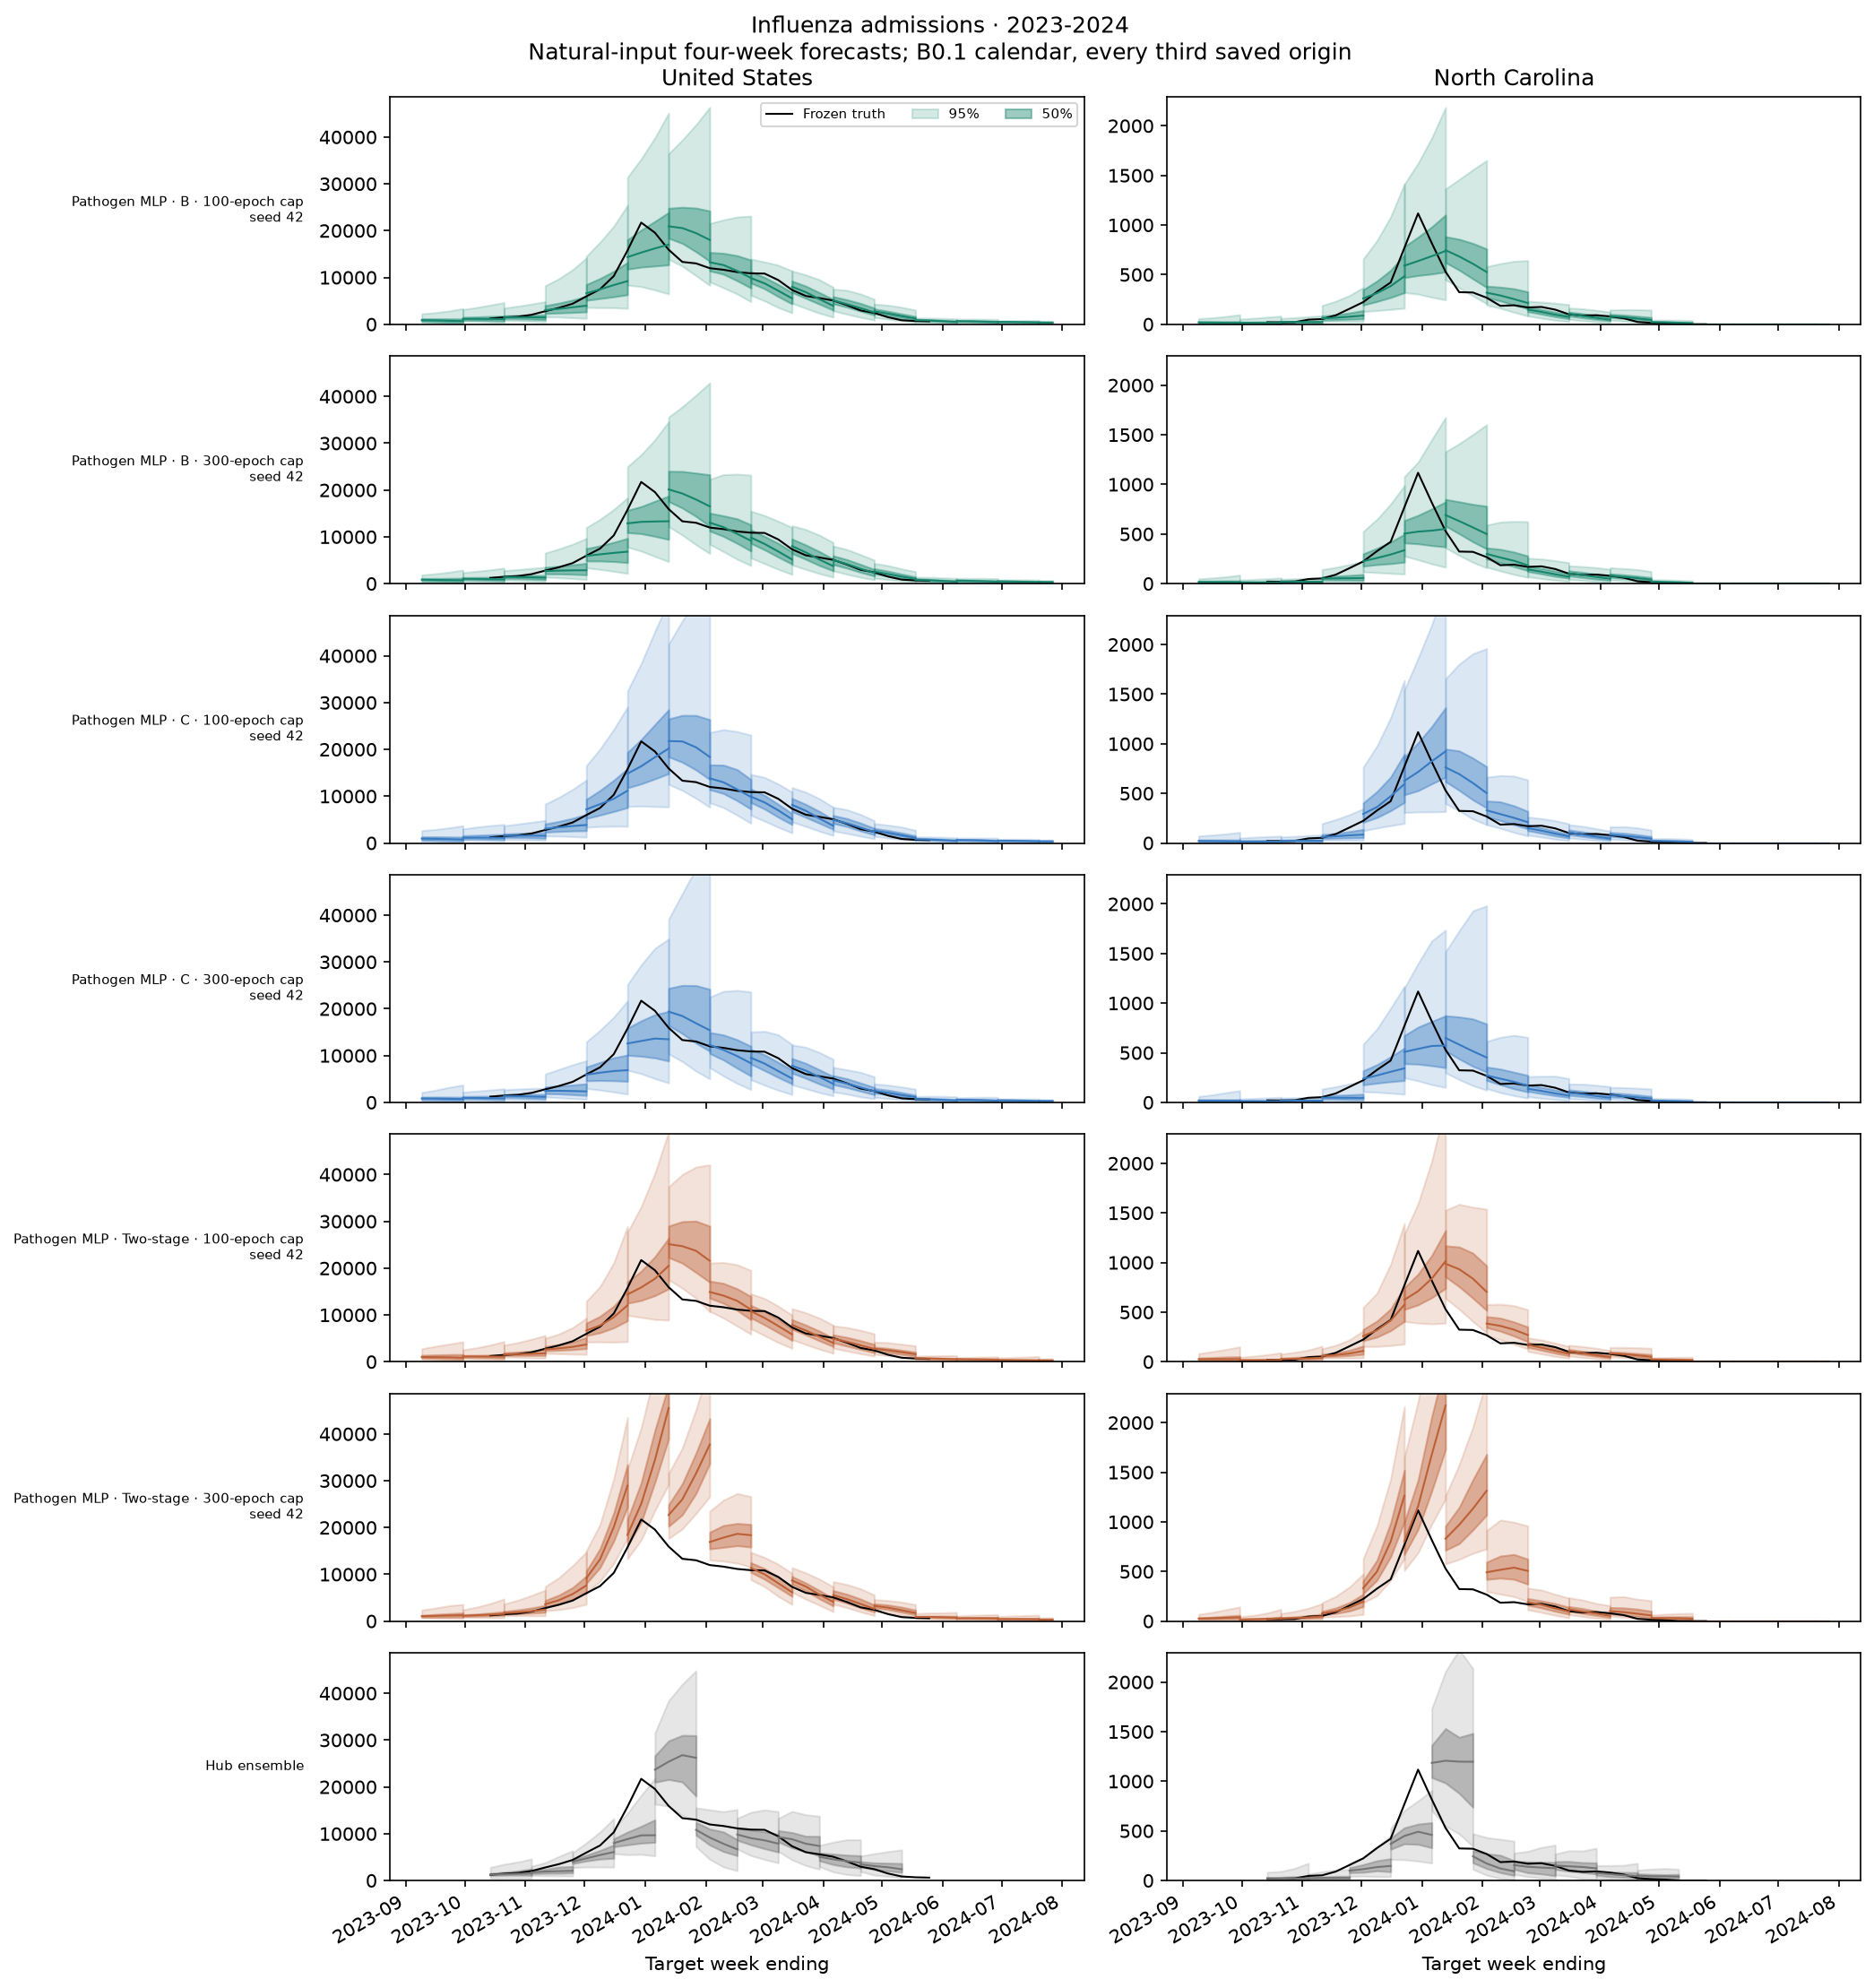
Longer training does not rescue the current two-stage formulation. Its follow-up configuration means remain above ensemble parity in every architecture. Pathogen two-stage changes from 1.104 to 1.292; the paired seed table shows a large deterioration for seed 42. This weakens the explanation that the initial poor results were simply due to the 100-epoch cap. It does not identify which part of the formulation fails.
More training is not a universal gain. Use the paired rows, not the best score from each differently sized suite, to judge a recipe. Target B changes from 0.980 to 1.029, and target C from 0.985 to 1.003; neither improves in any of the three matched seeds. The original gap-only leader is not included in this budget contrast. Repeat variability also matters: joint-direct seed 44 changes from 1.144 to 1.363 despite retaining cap 300. The cause is not established here; the saved fitting code is unchanged between source snapshots, whose changes add suite routing.
Calibration remains a limitation. The cap-300 leader's weighted 50% and 95% coverage are 43.3% and 84.6%. These use the same geography/target/season weights as the ranking.
Where performance changes
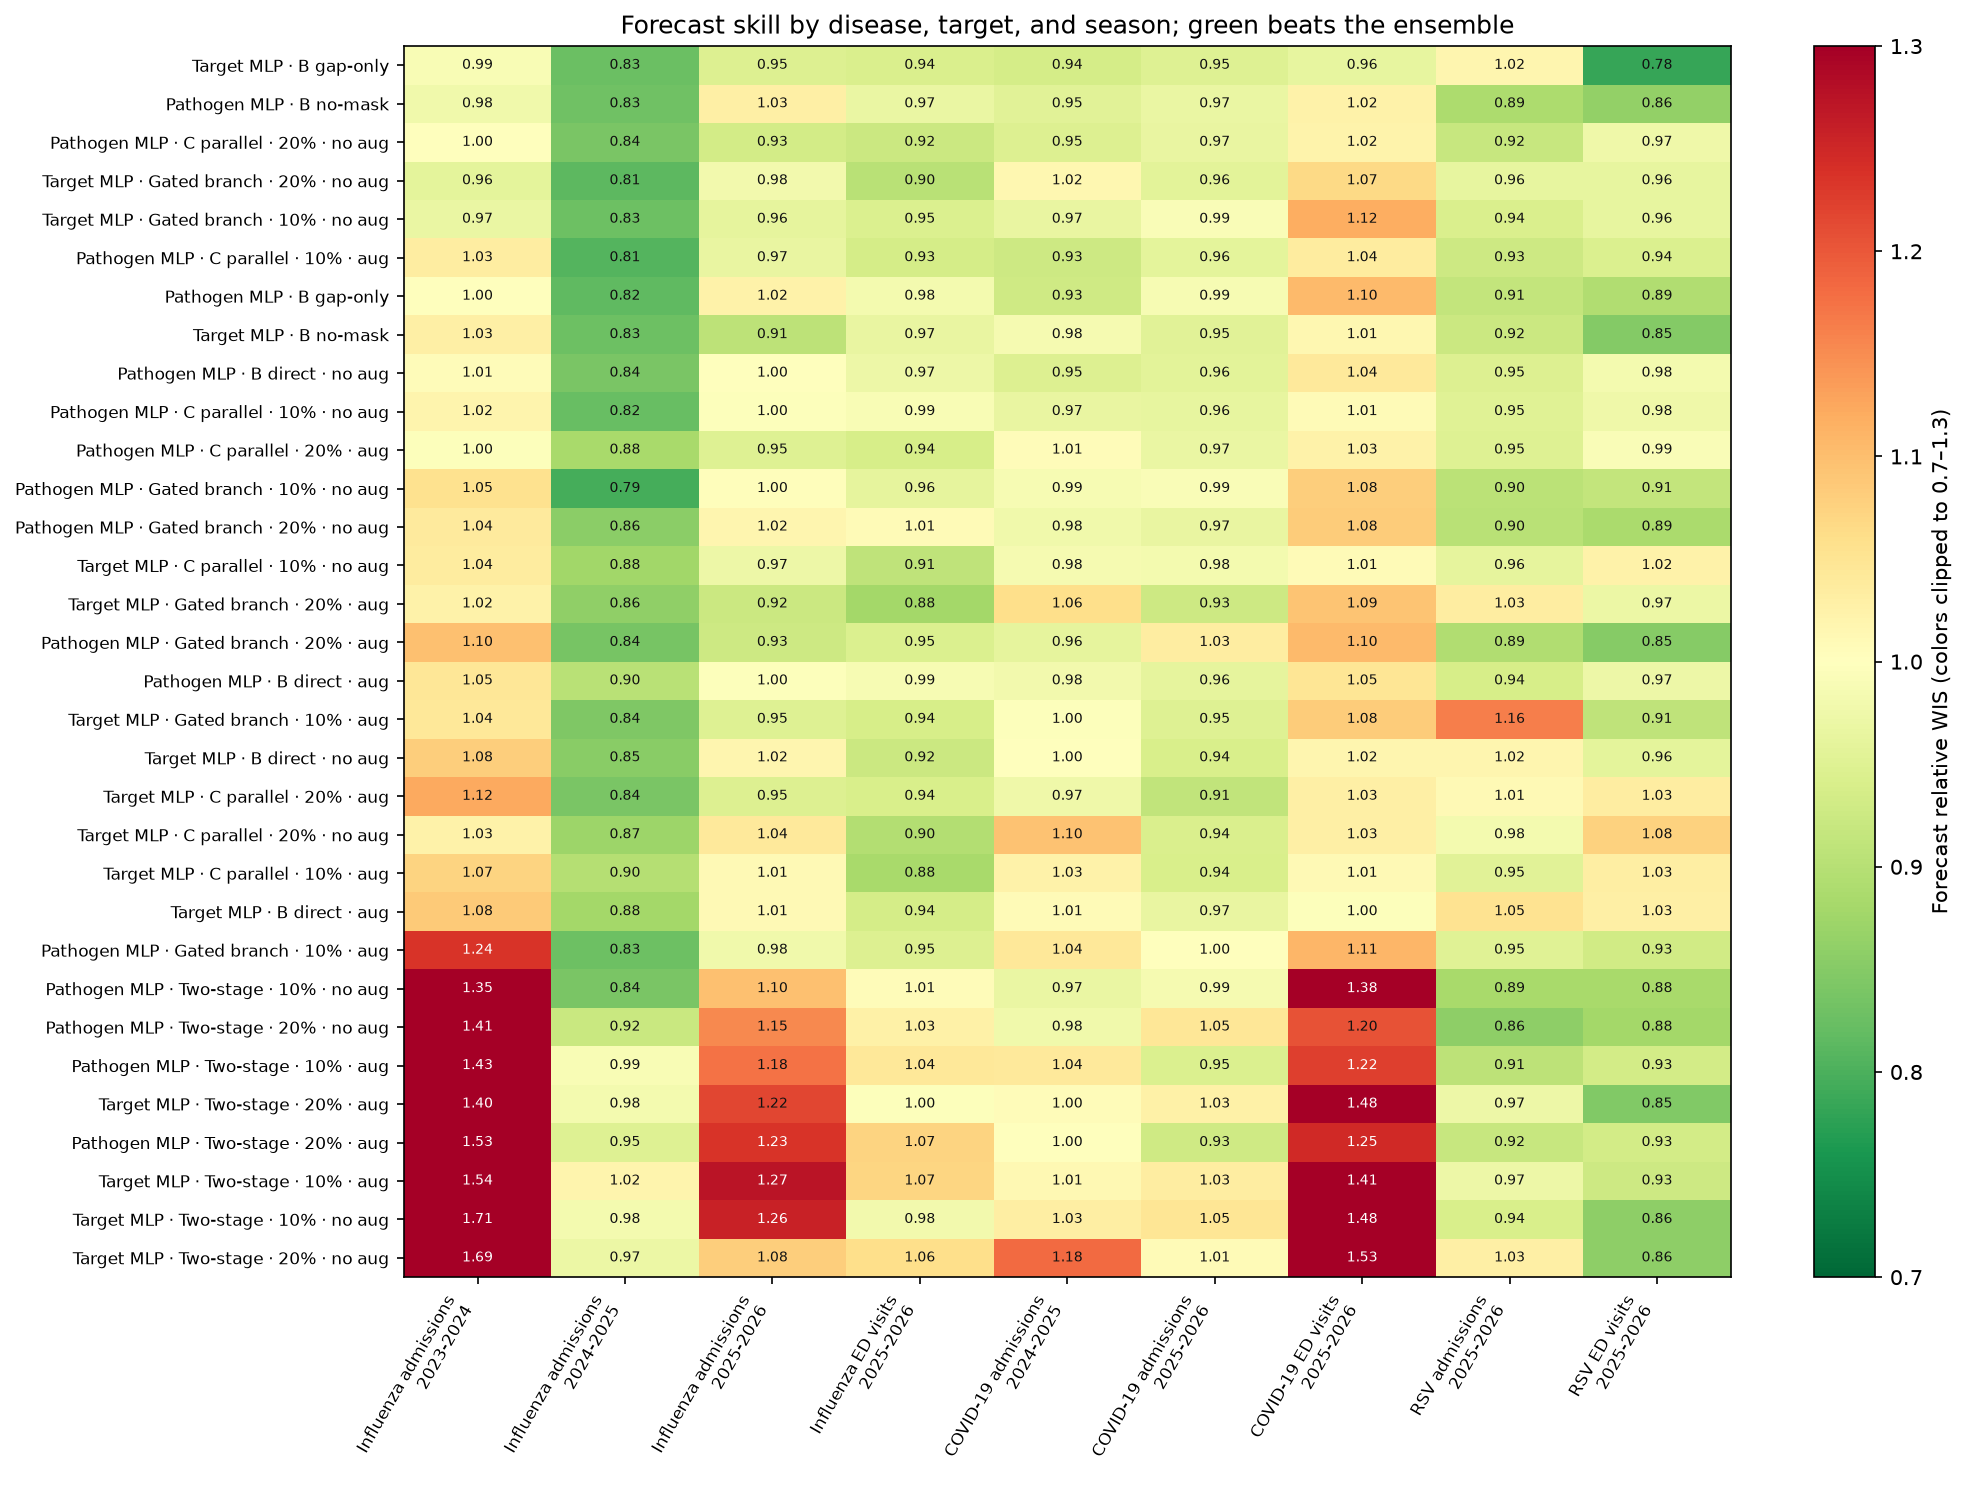
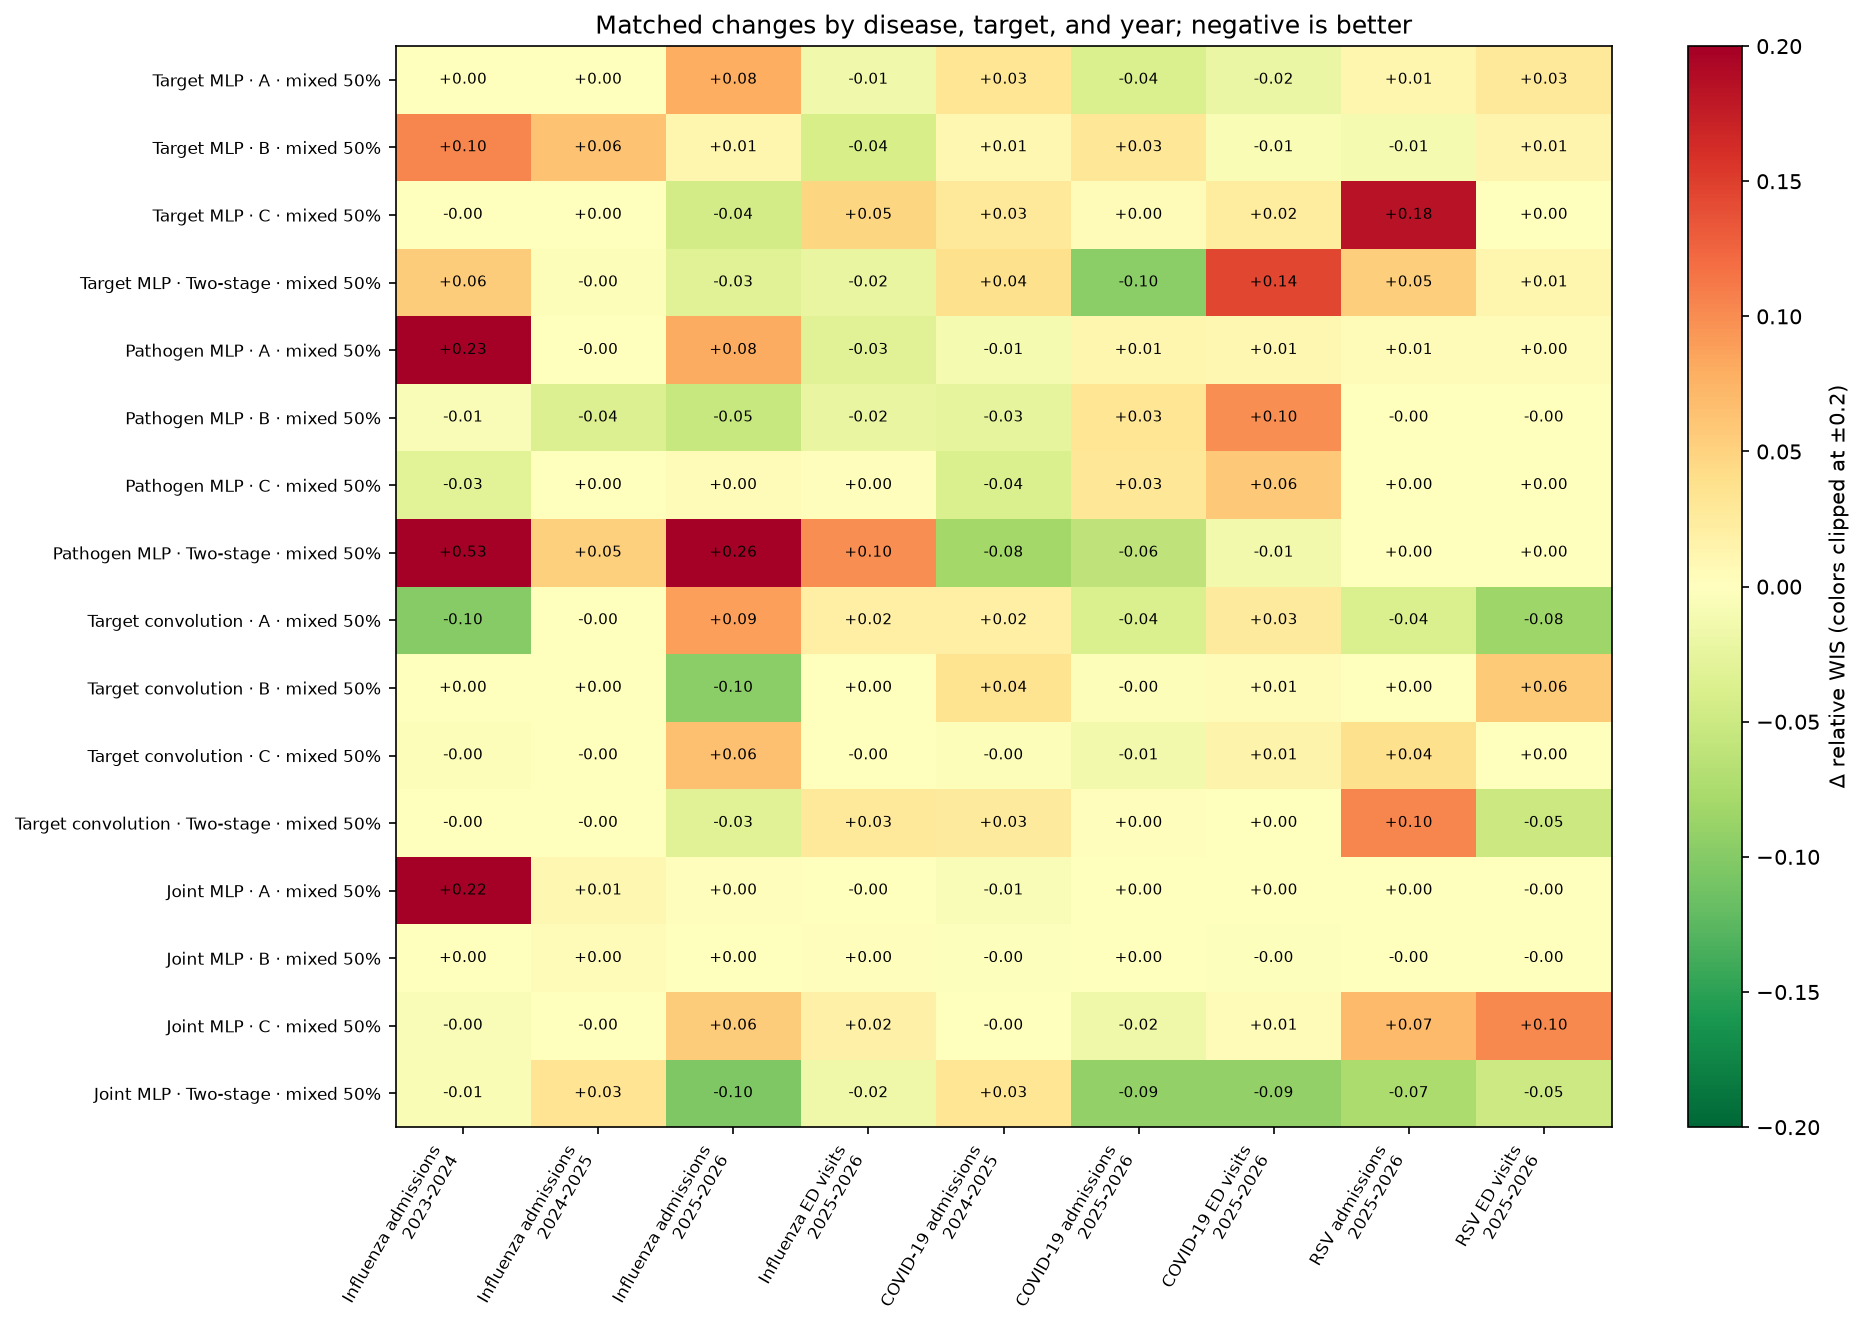
Disease → target → chronological season, matching the fan order. Values are paired seed-mean changes, not changes between averages with different seeds. Joint rows remain repeat controls. Color saturation does not truncate the printed values.
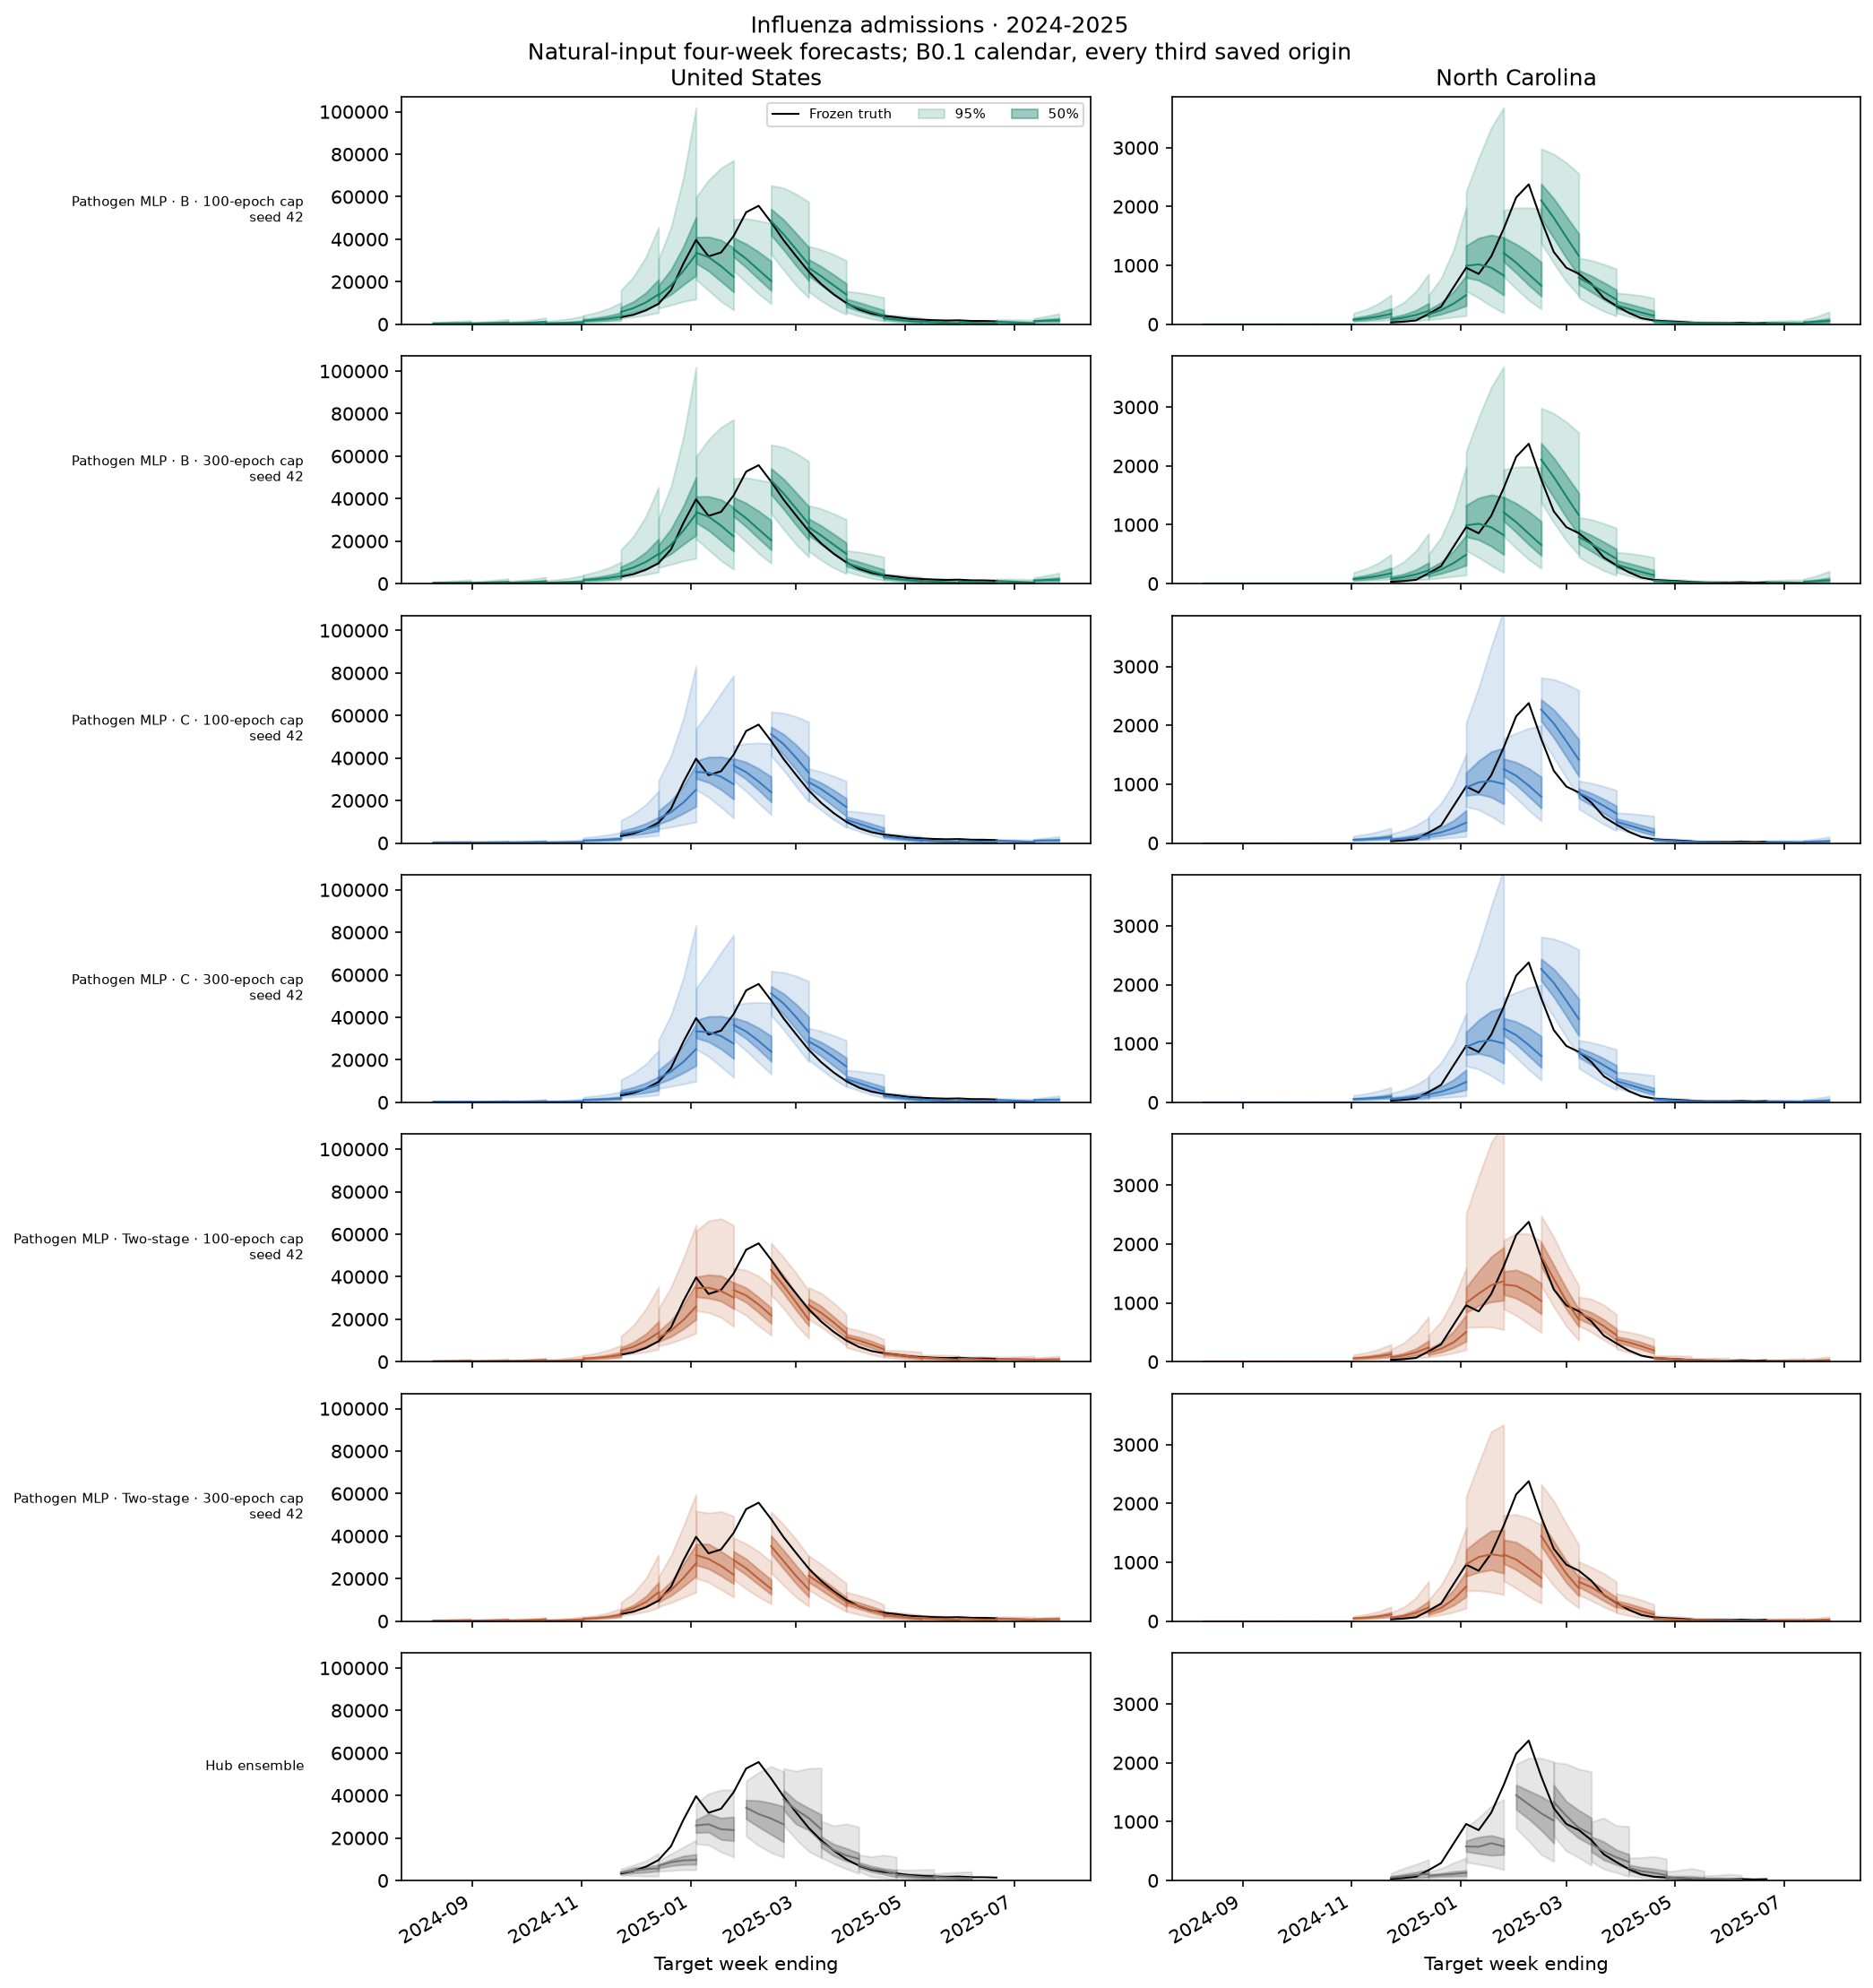
Matched 100-vs-300 fan plots
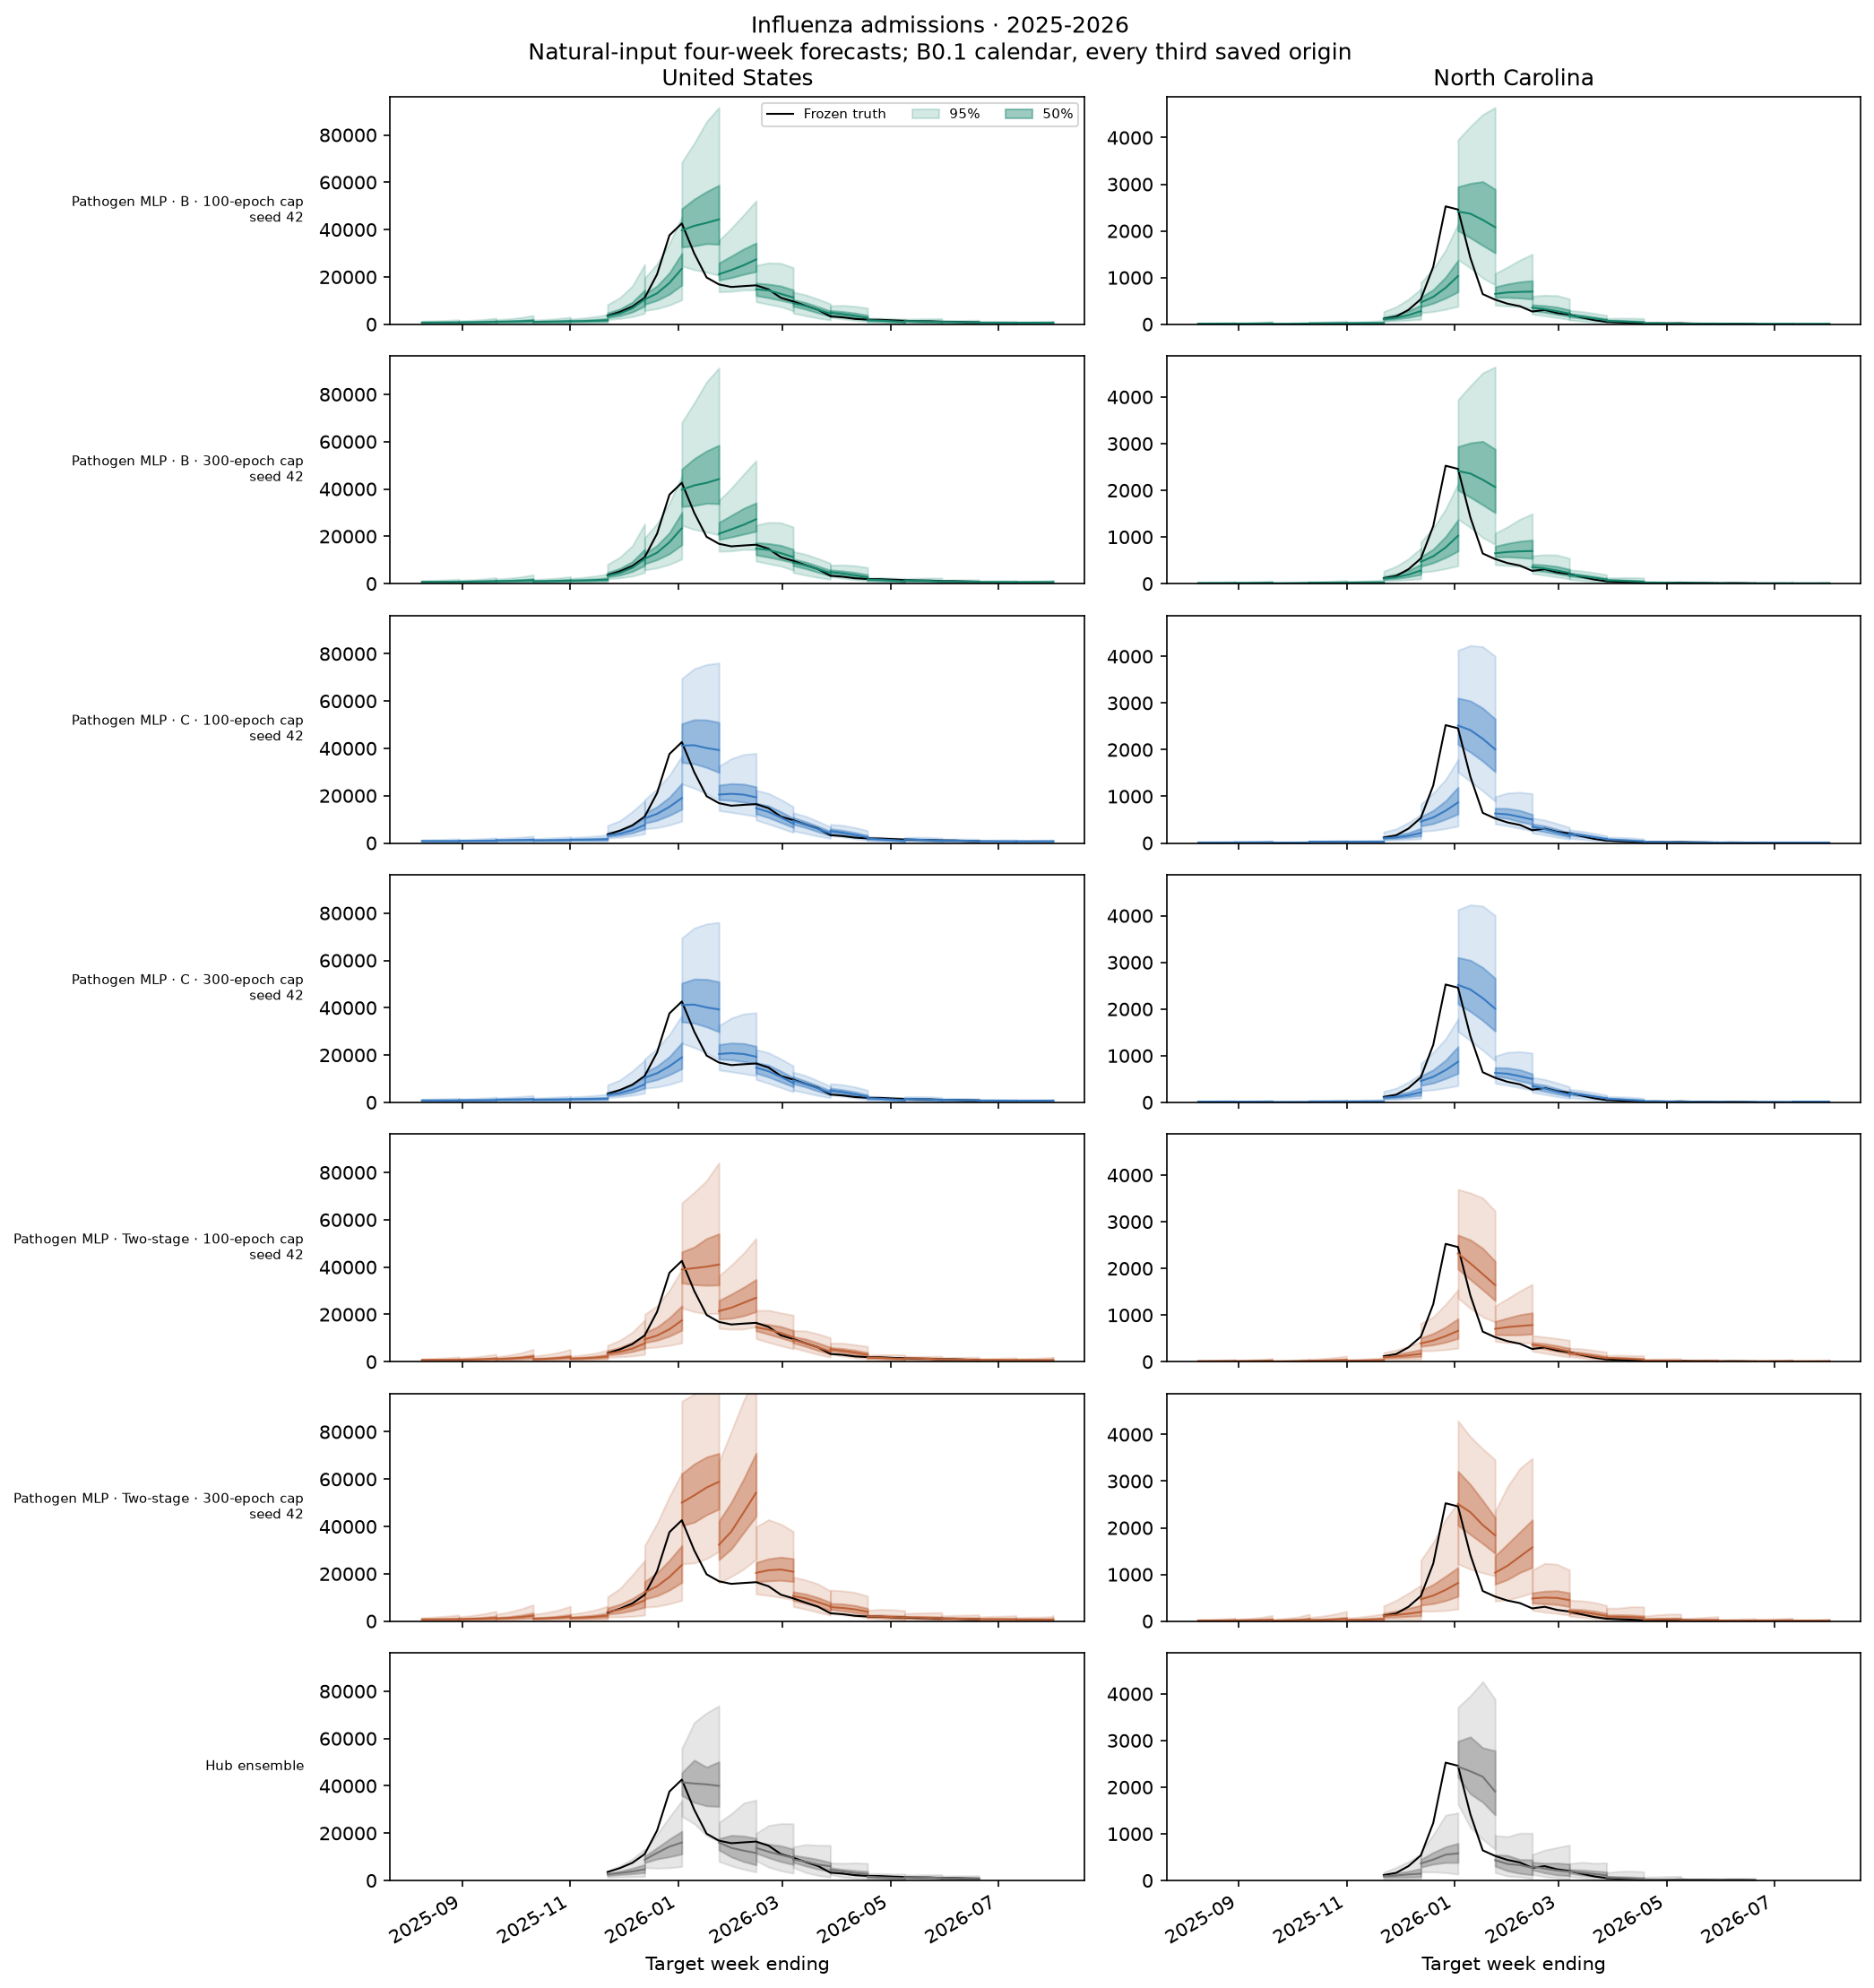
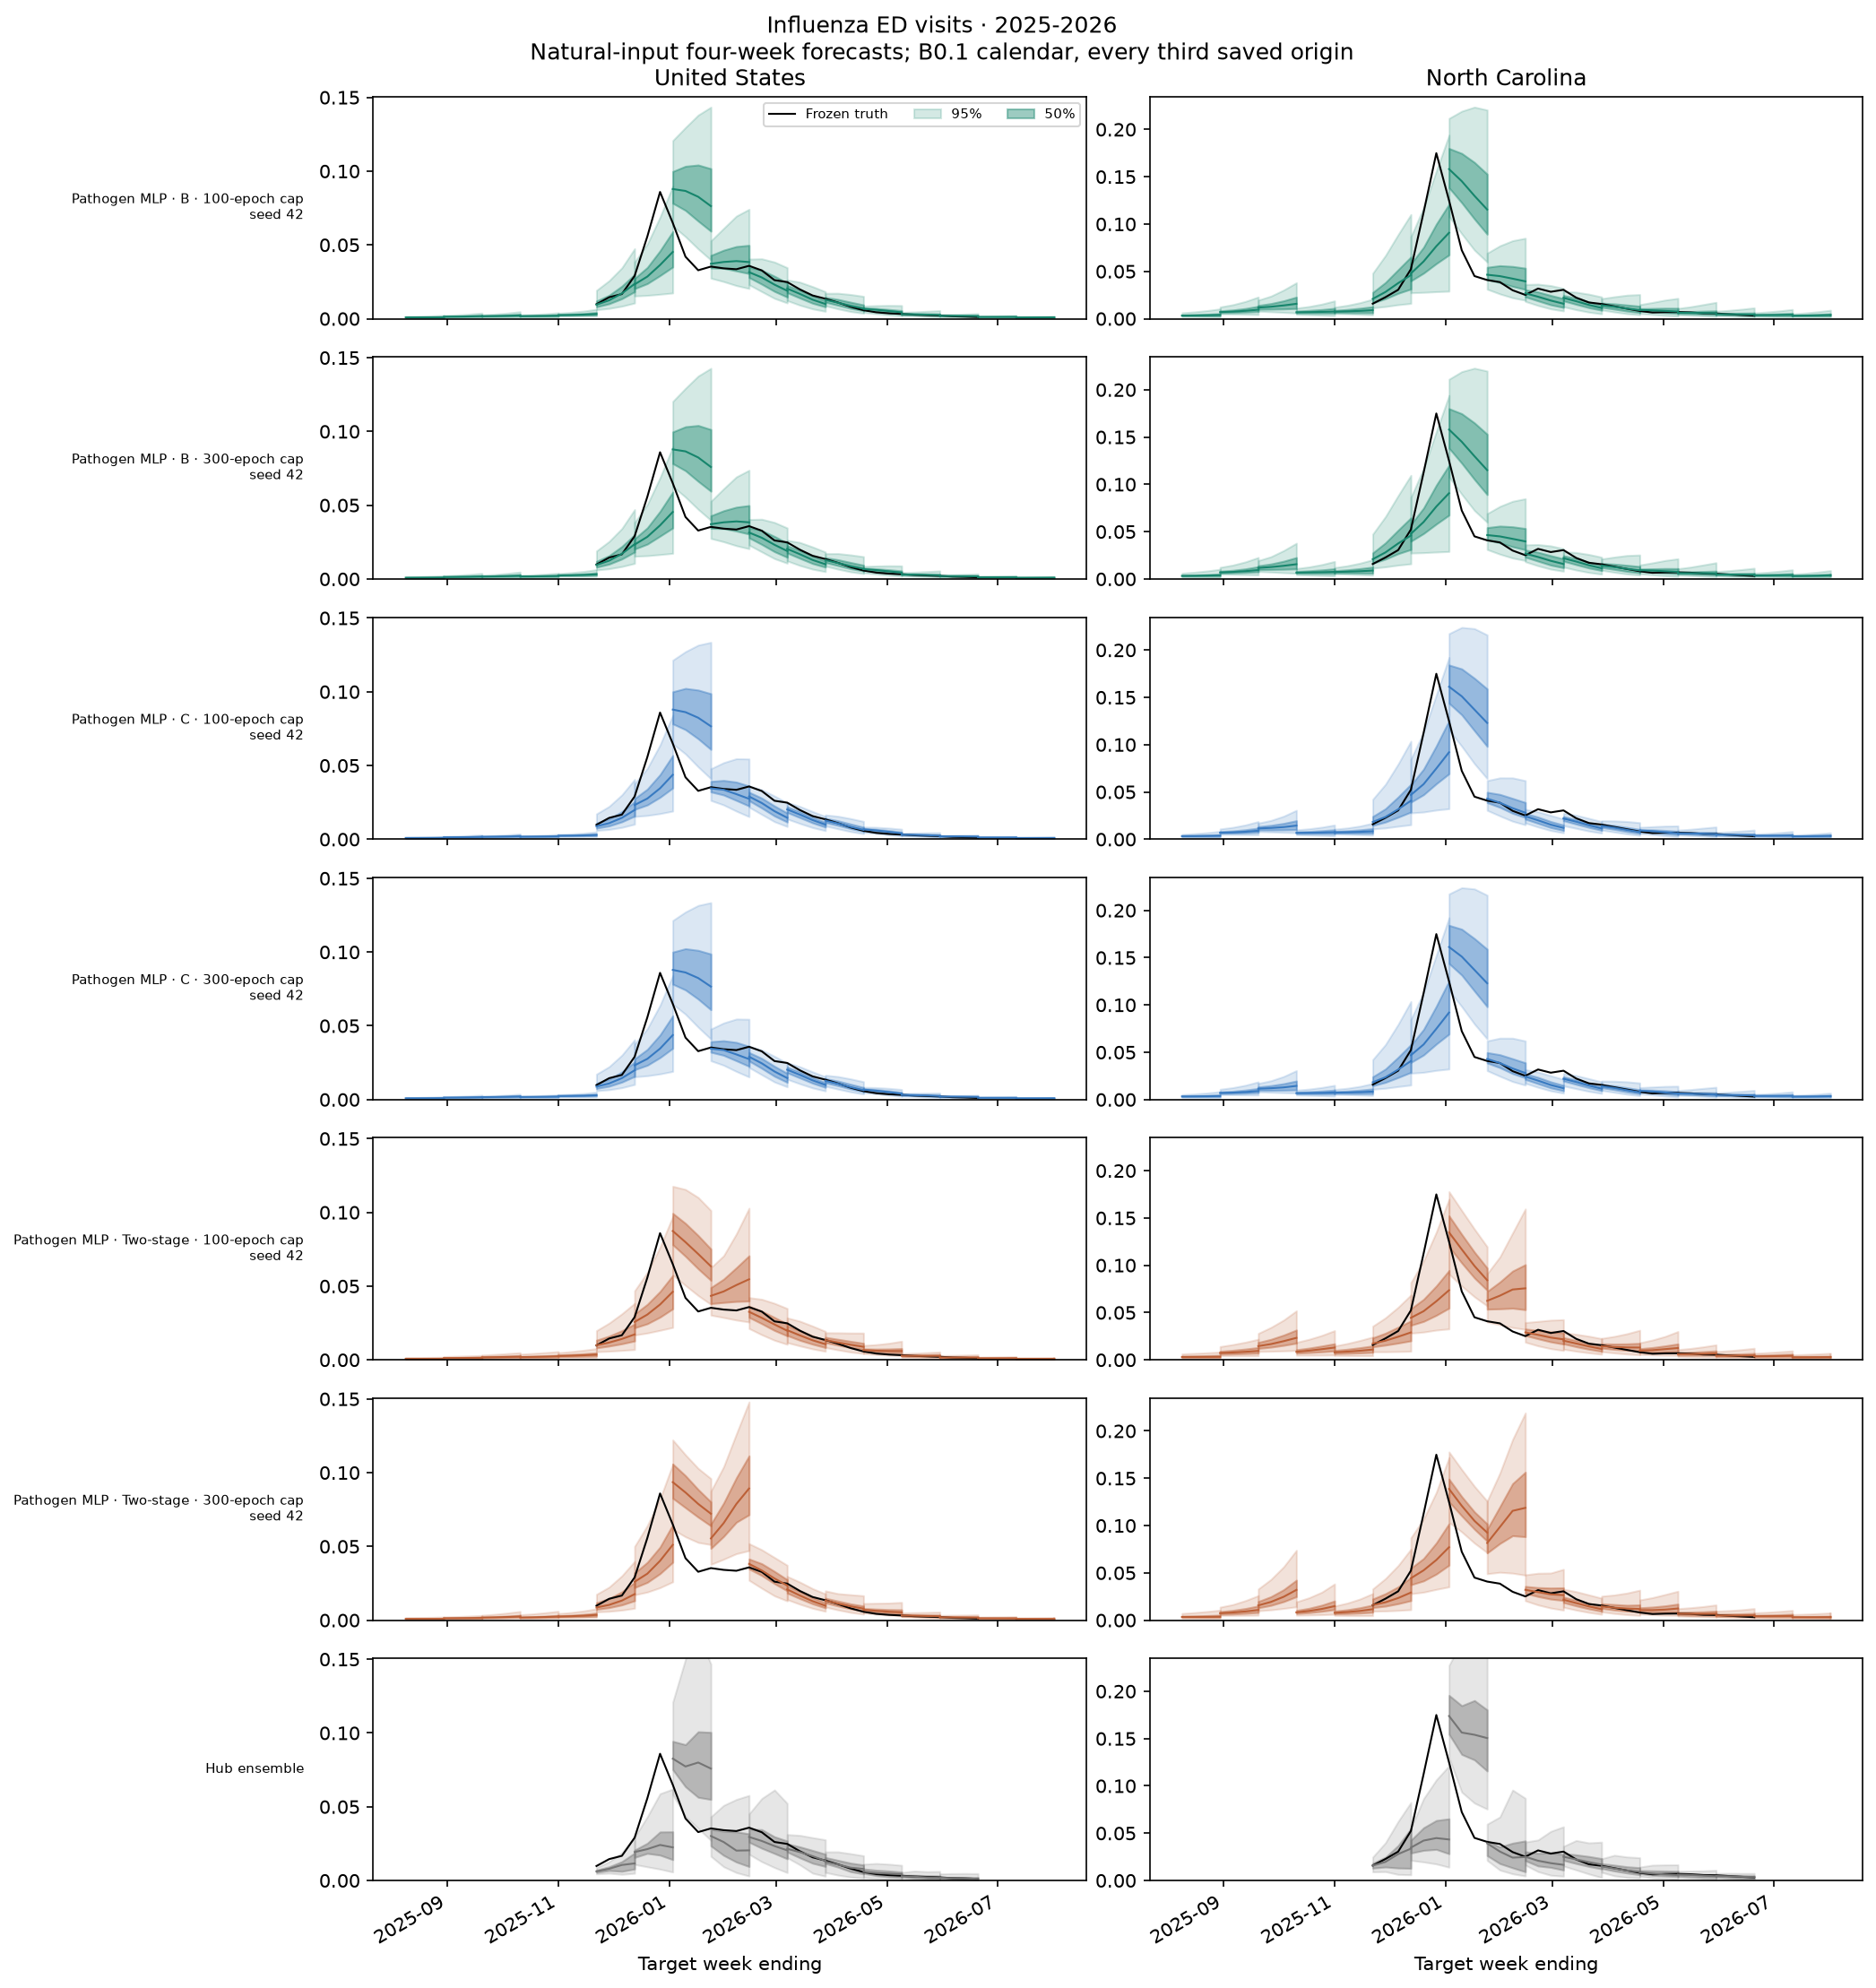
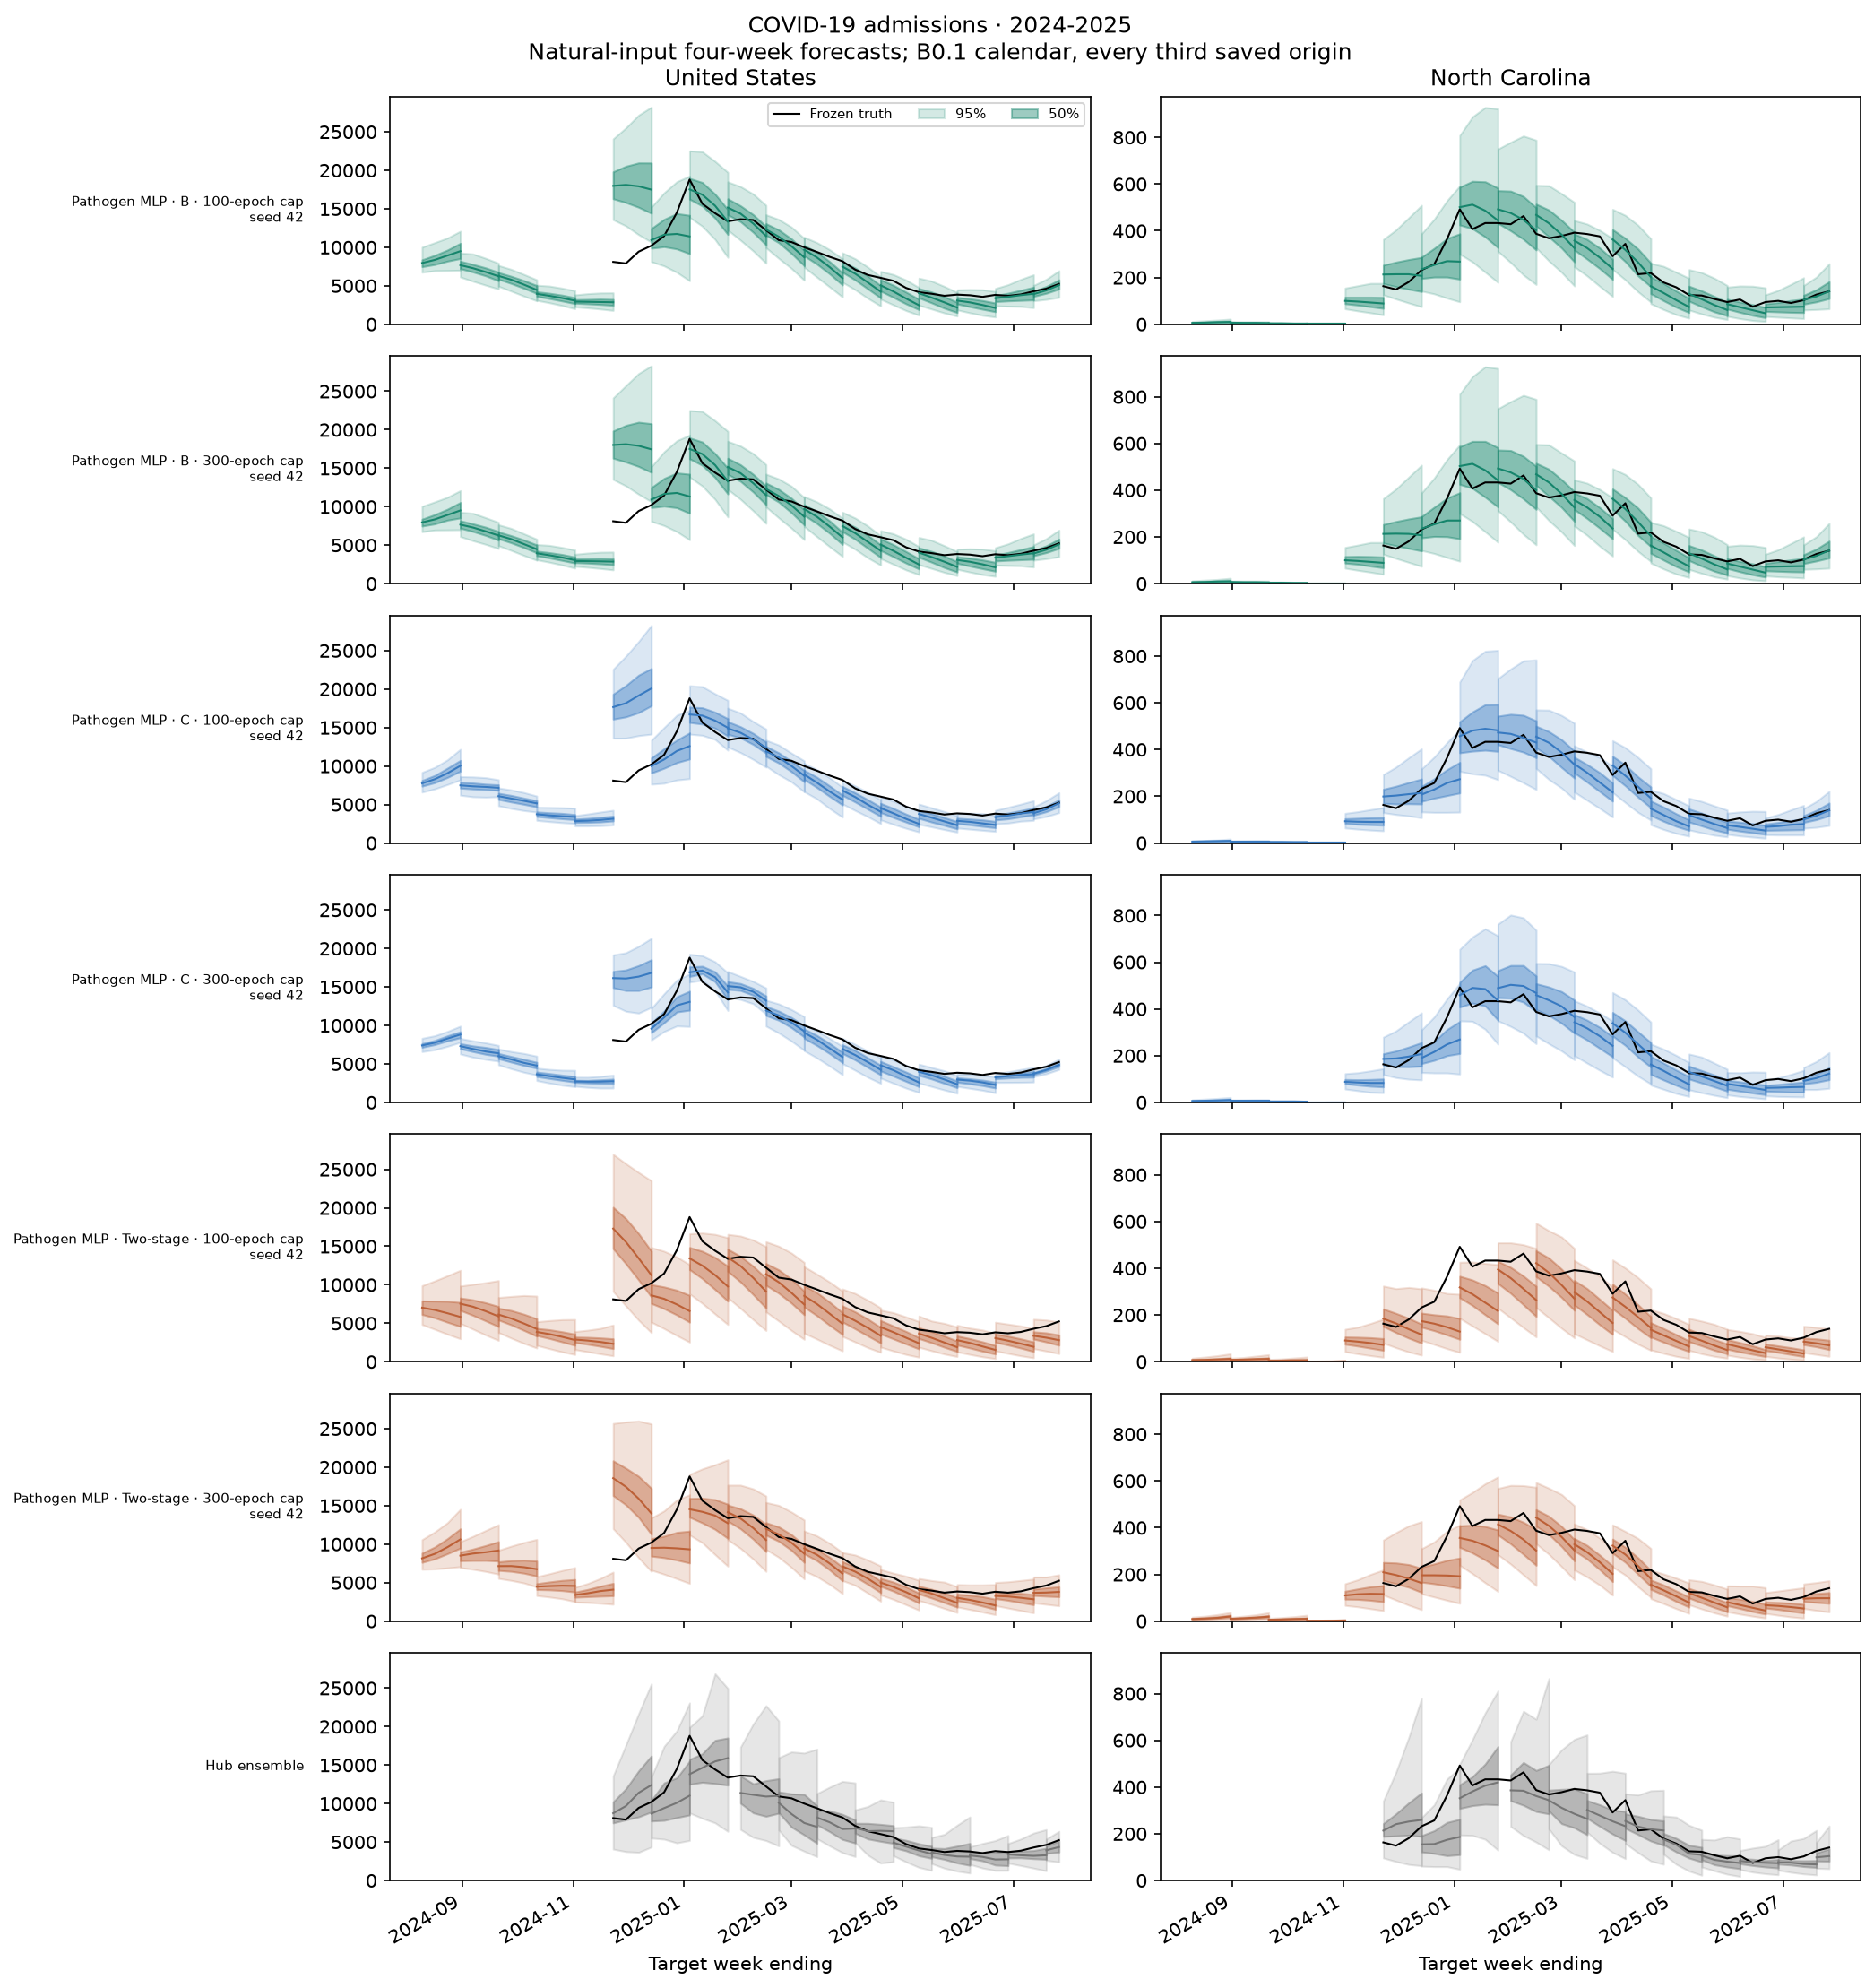
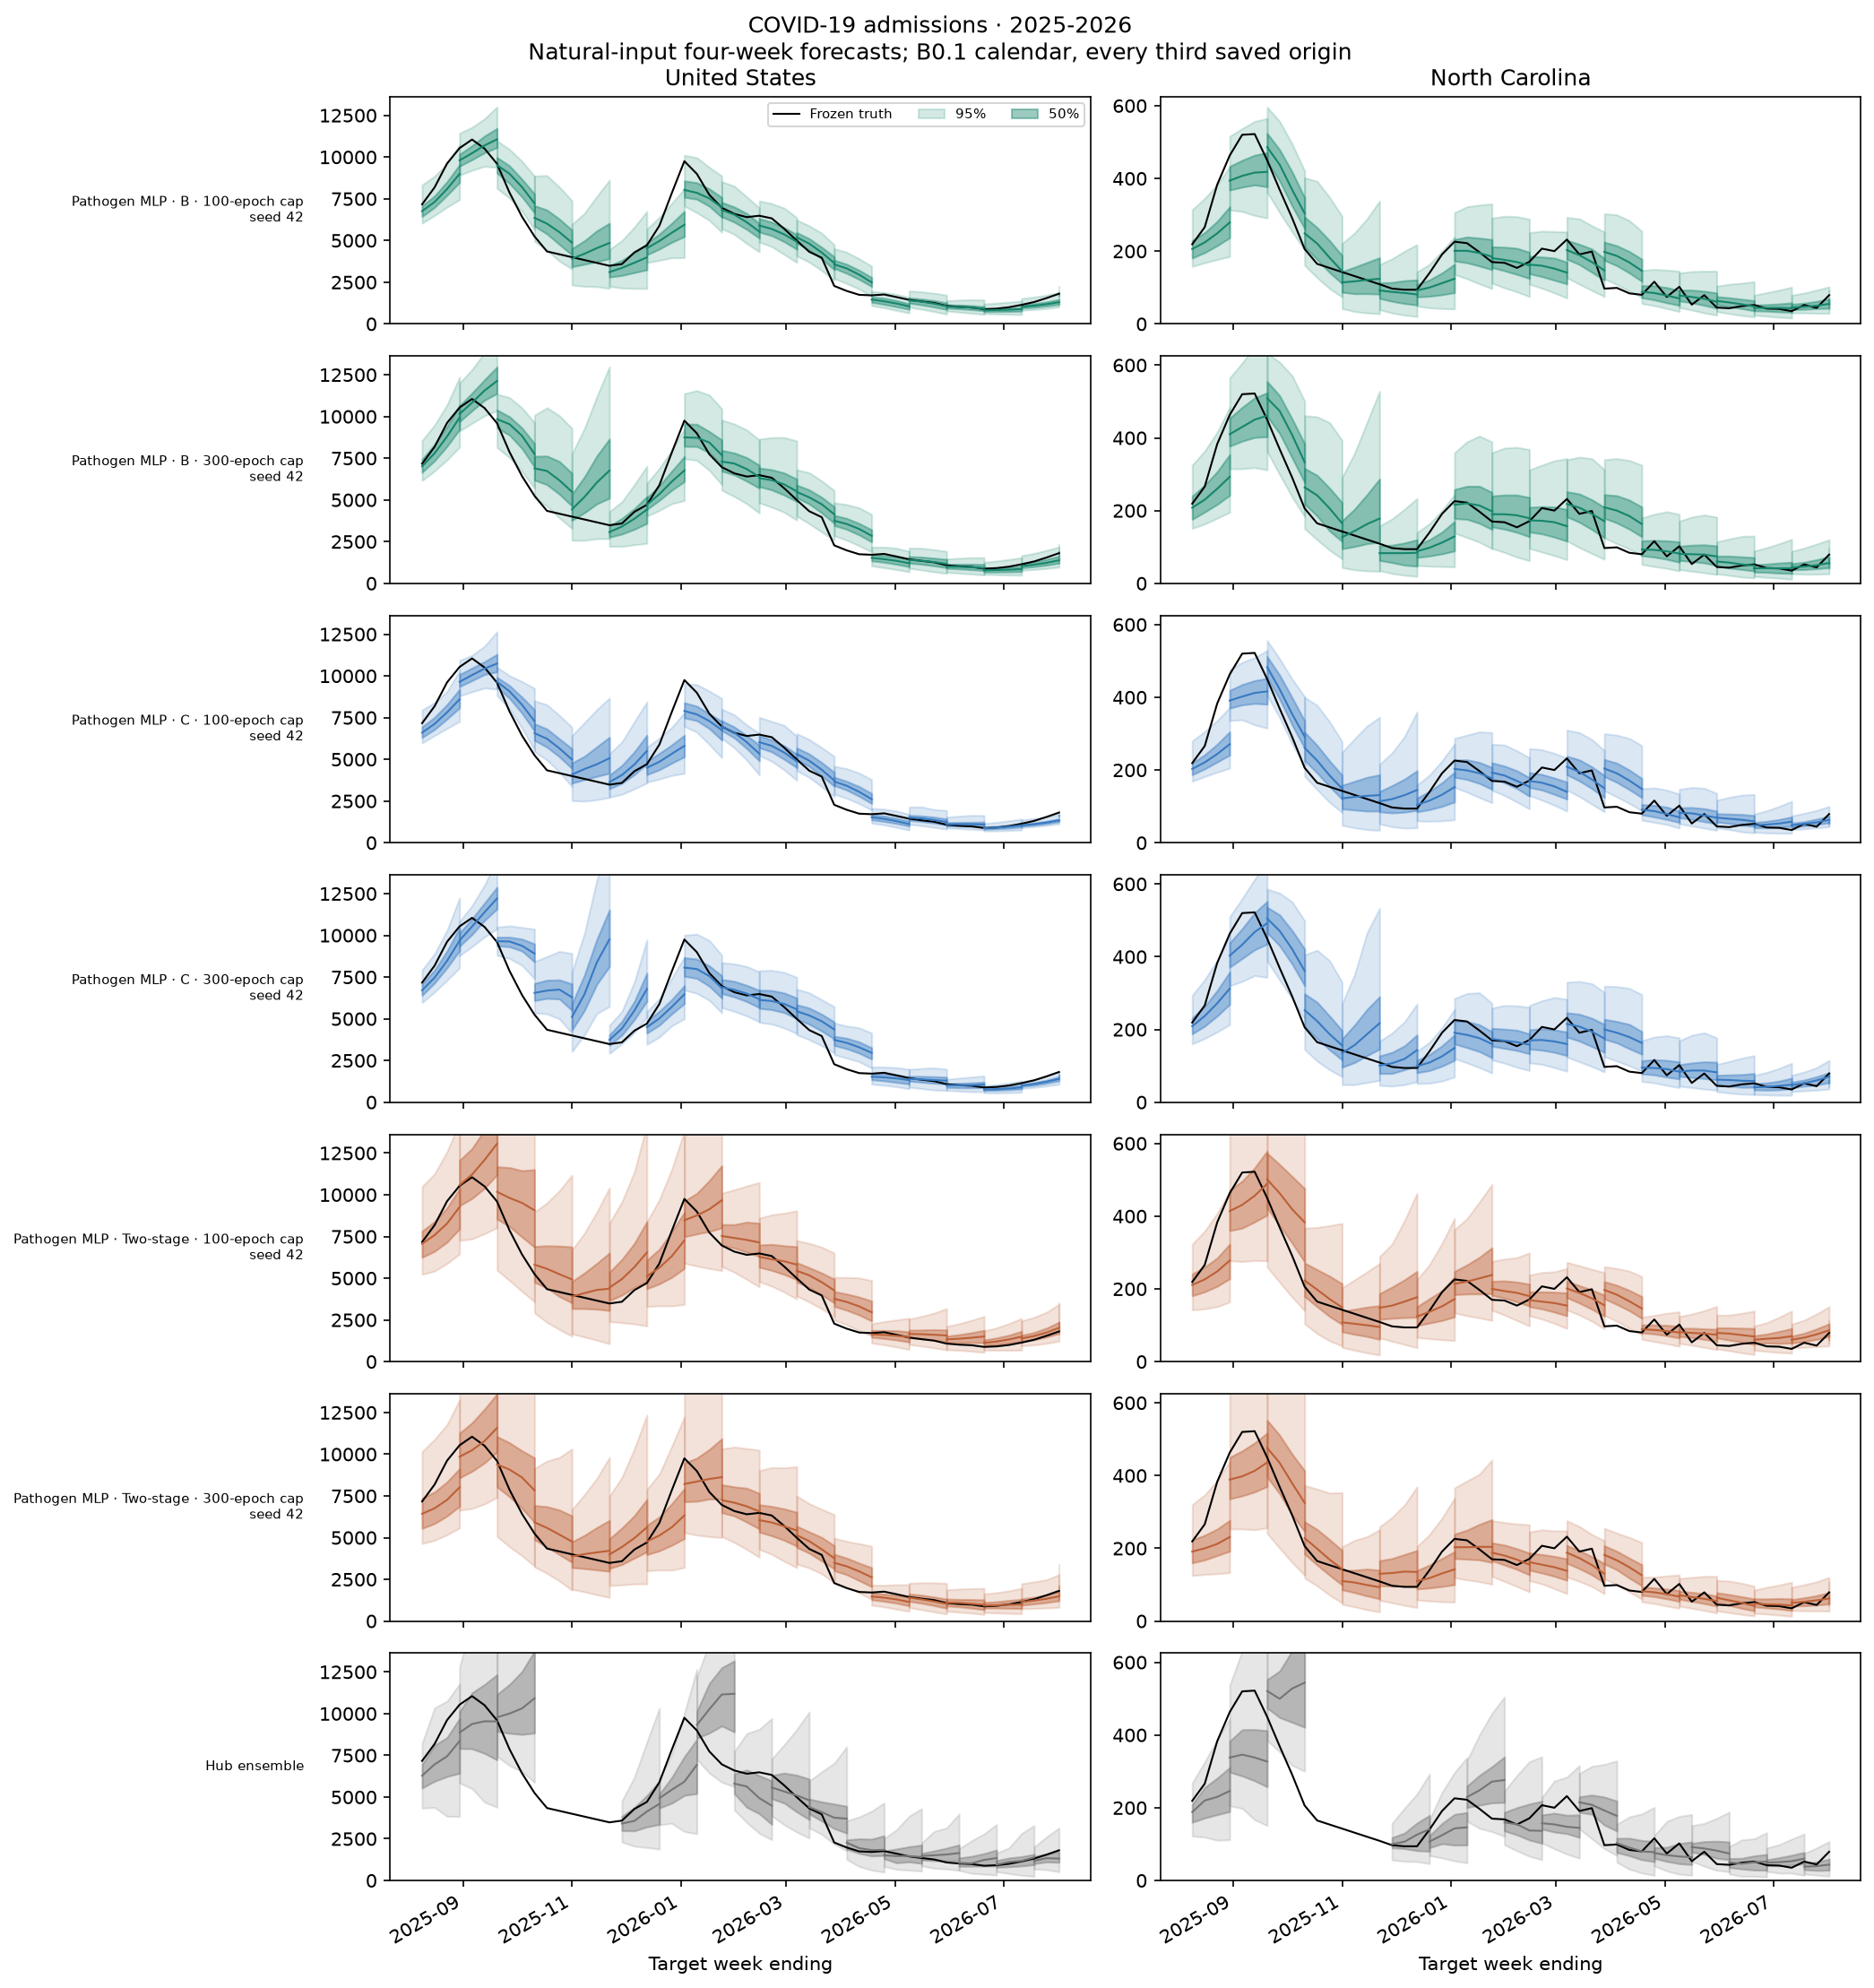
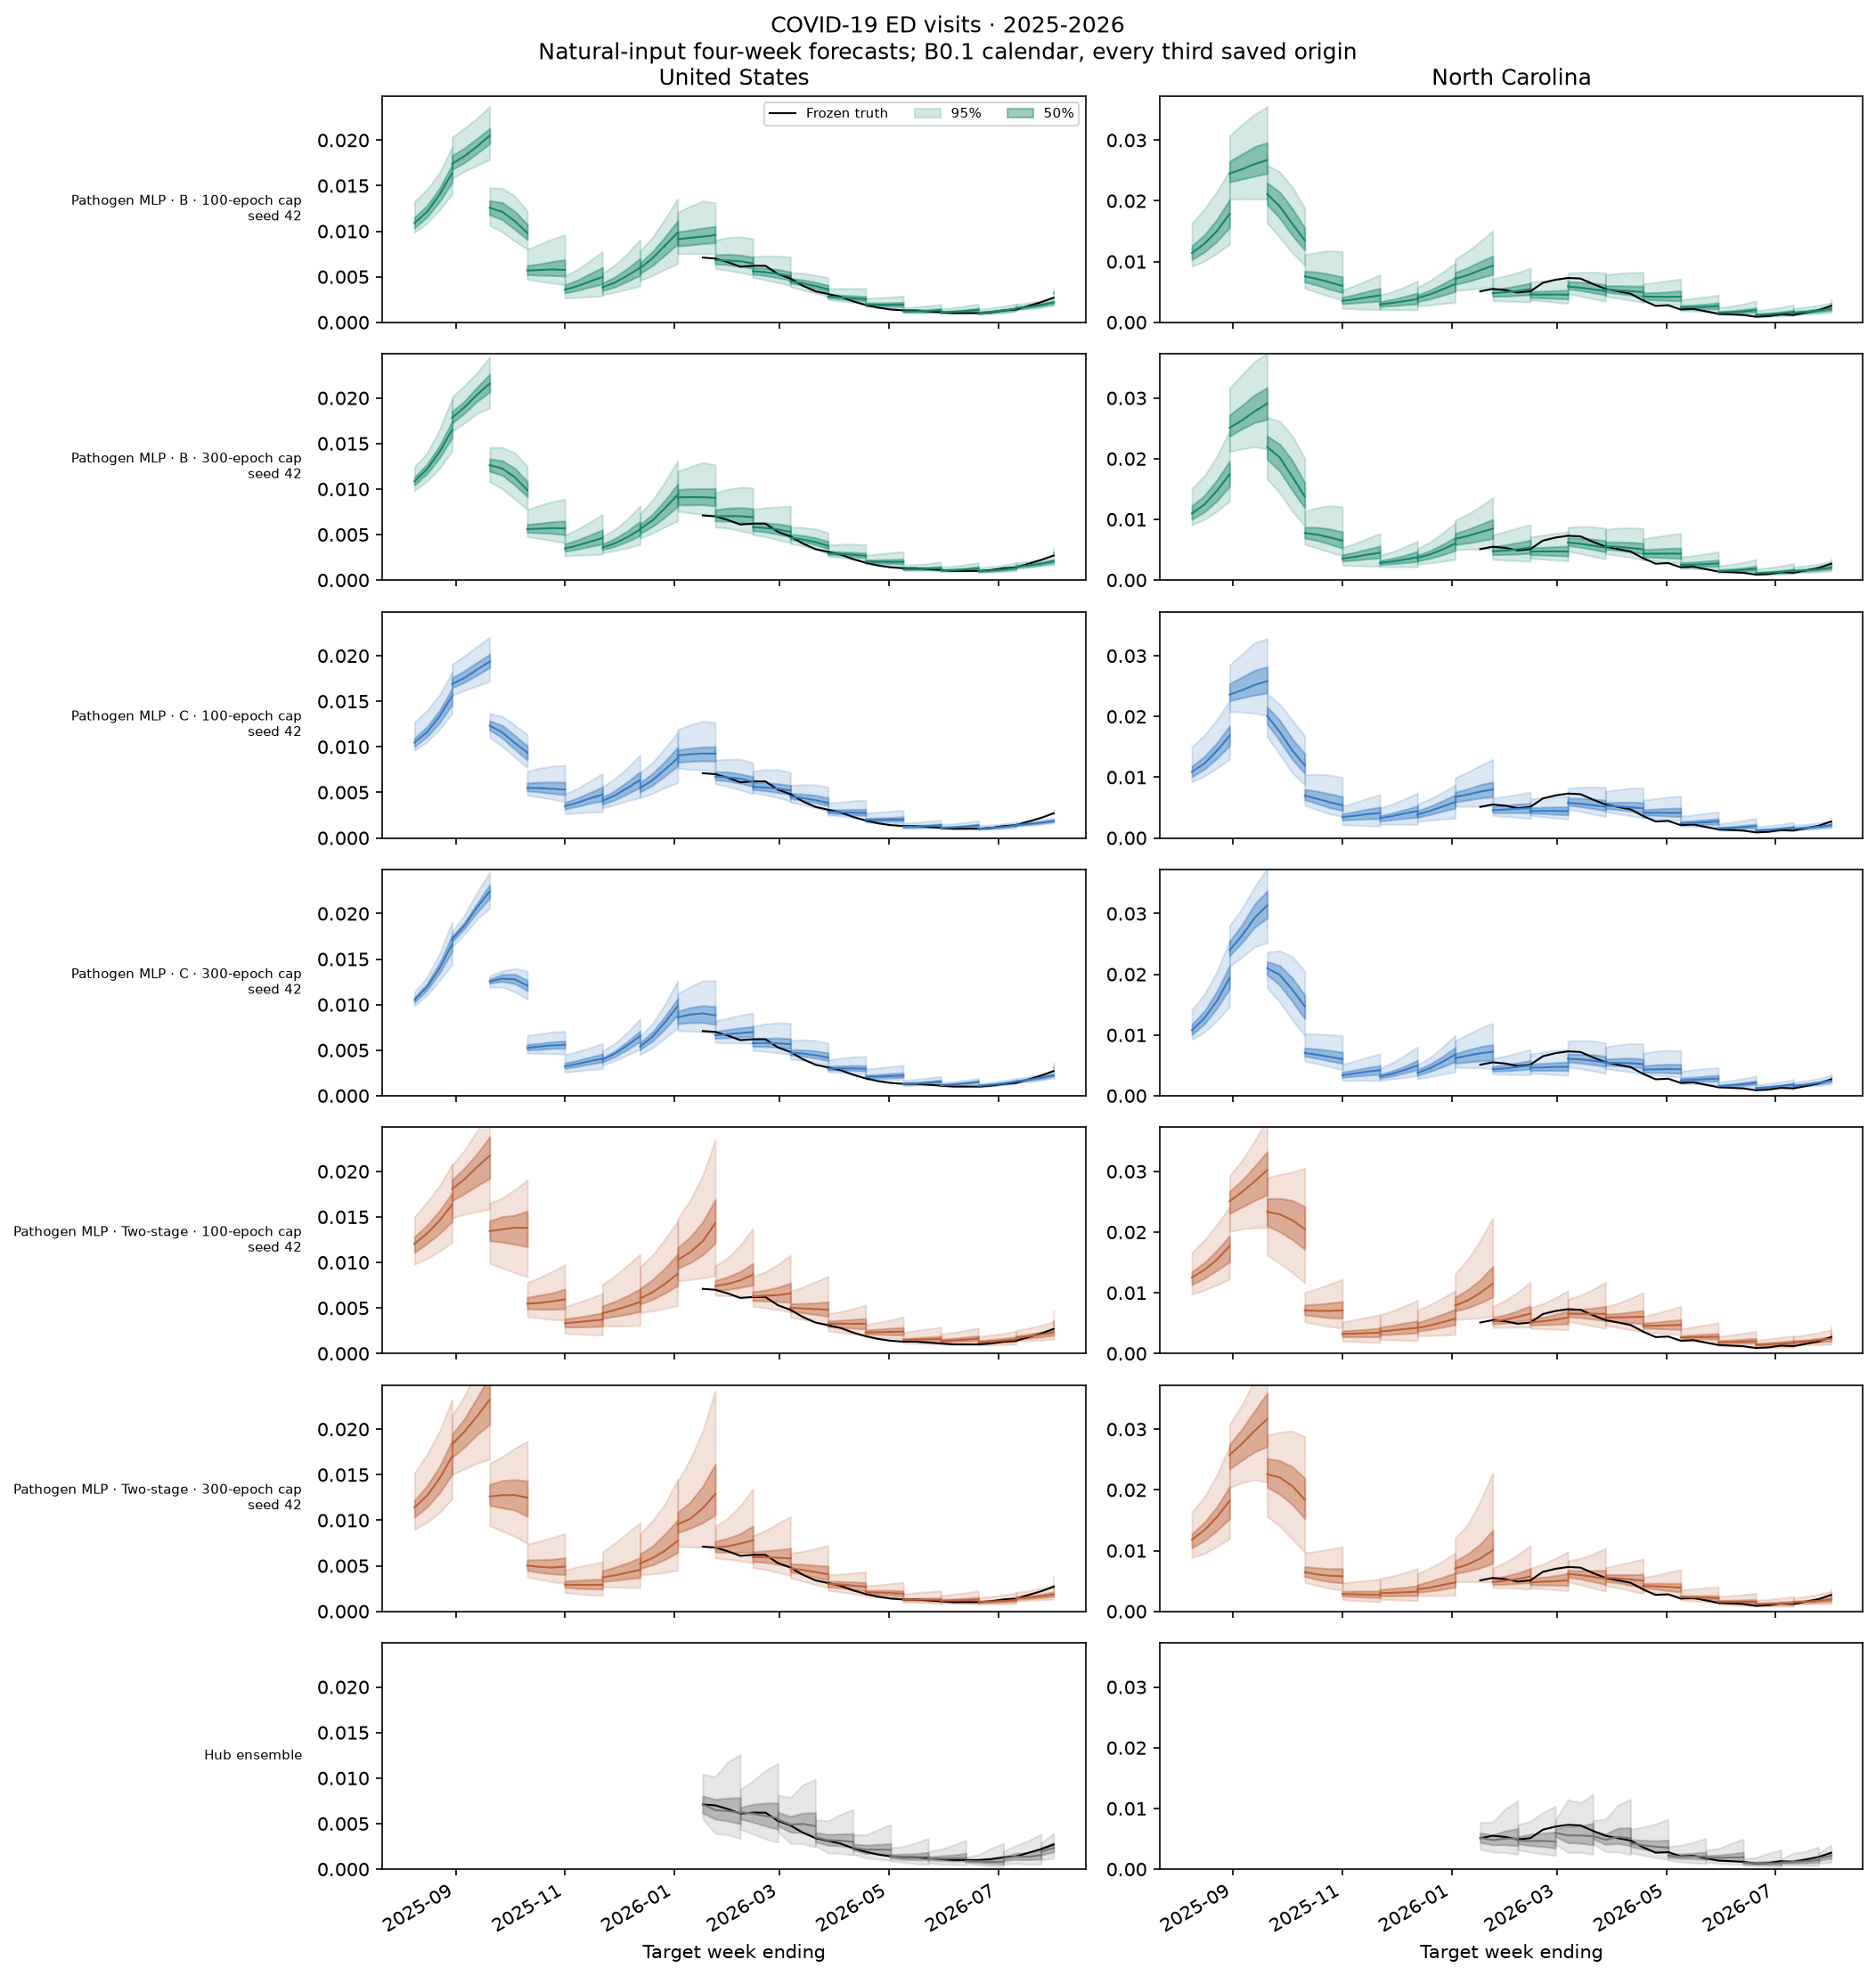
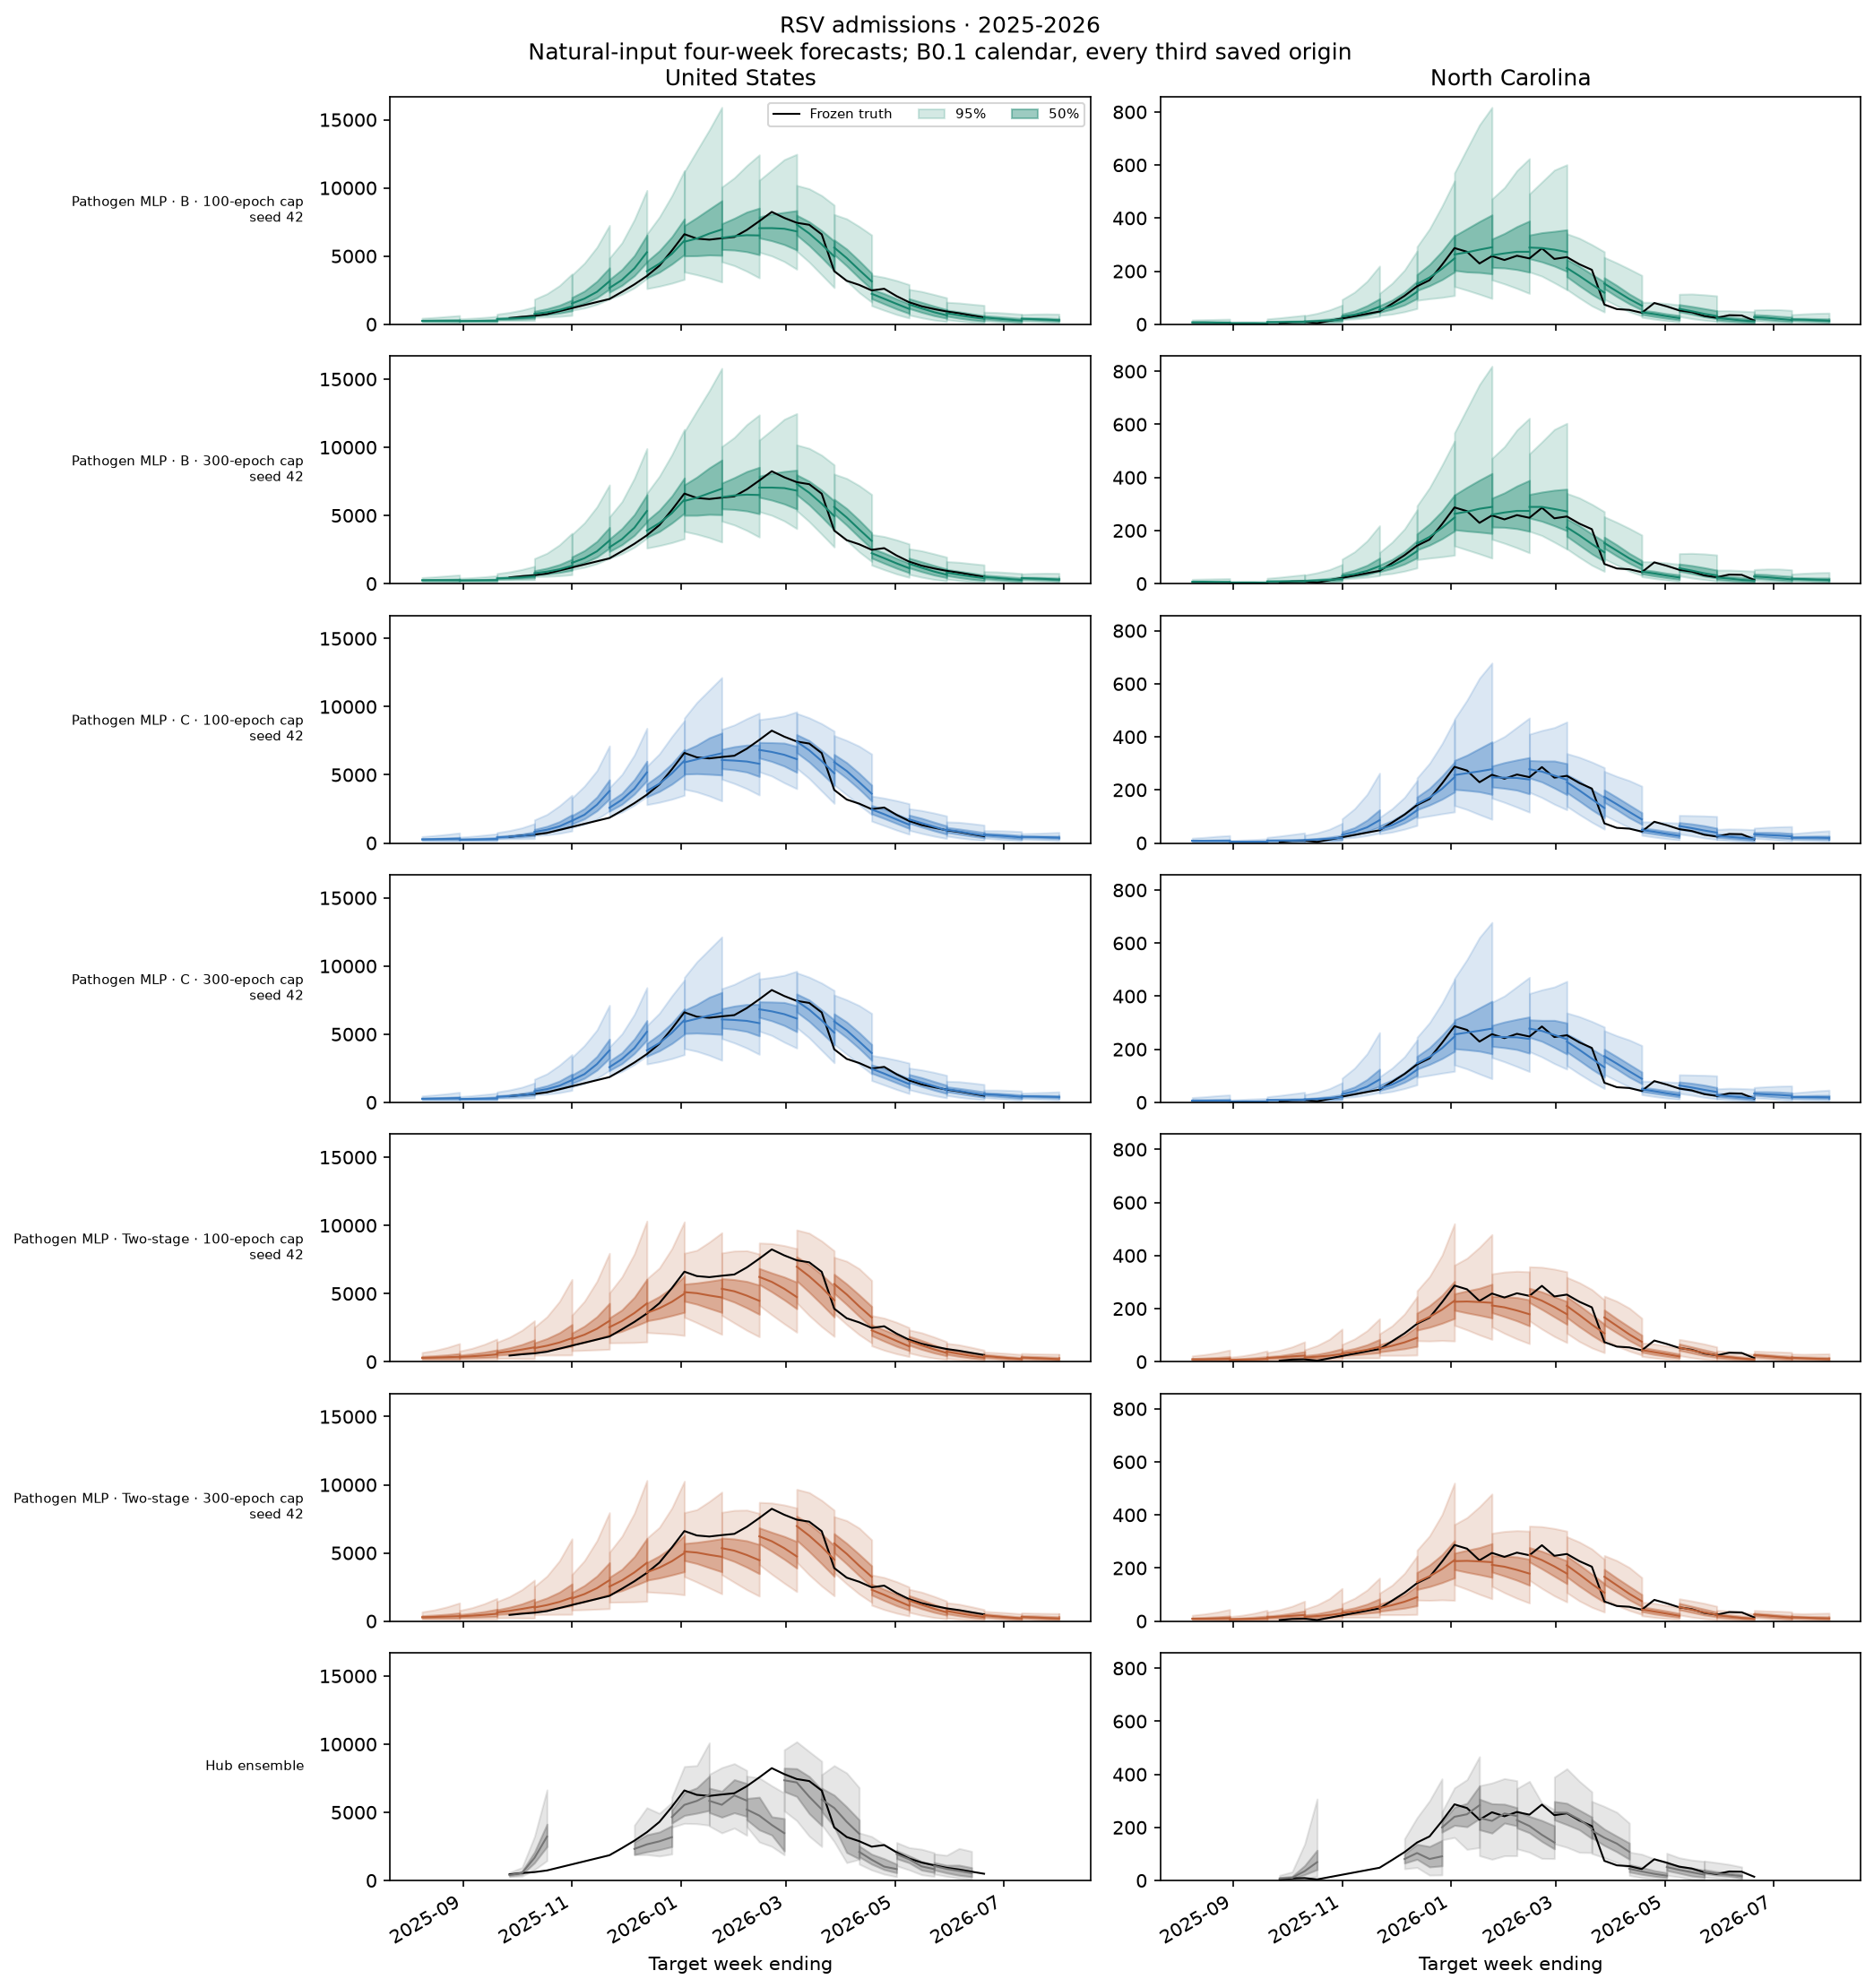
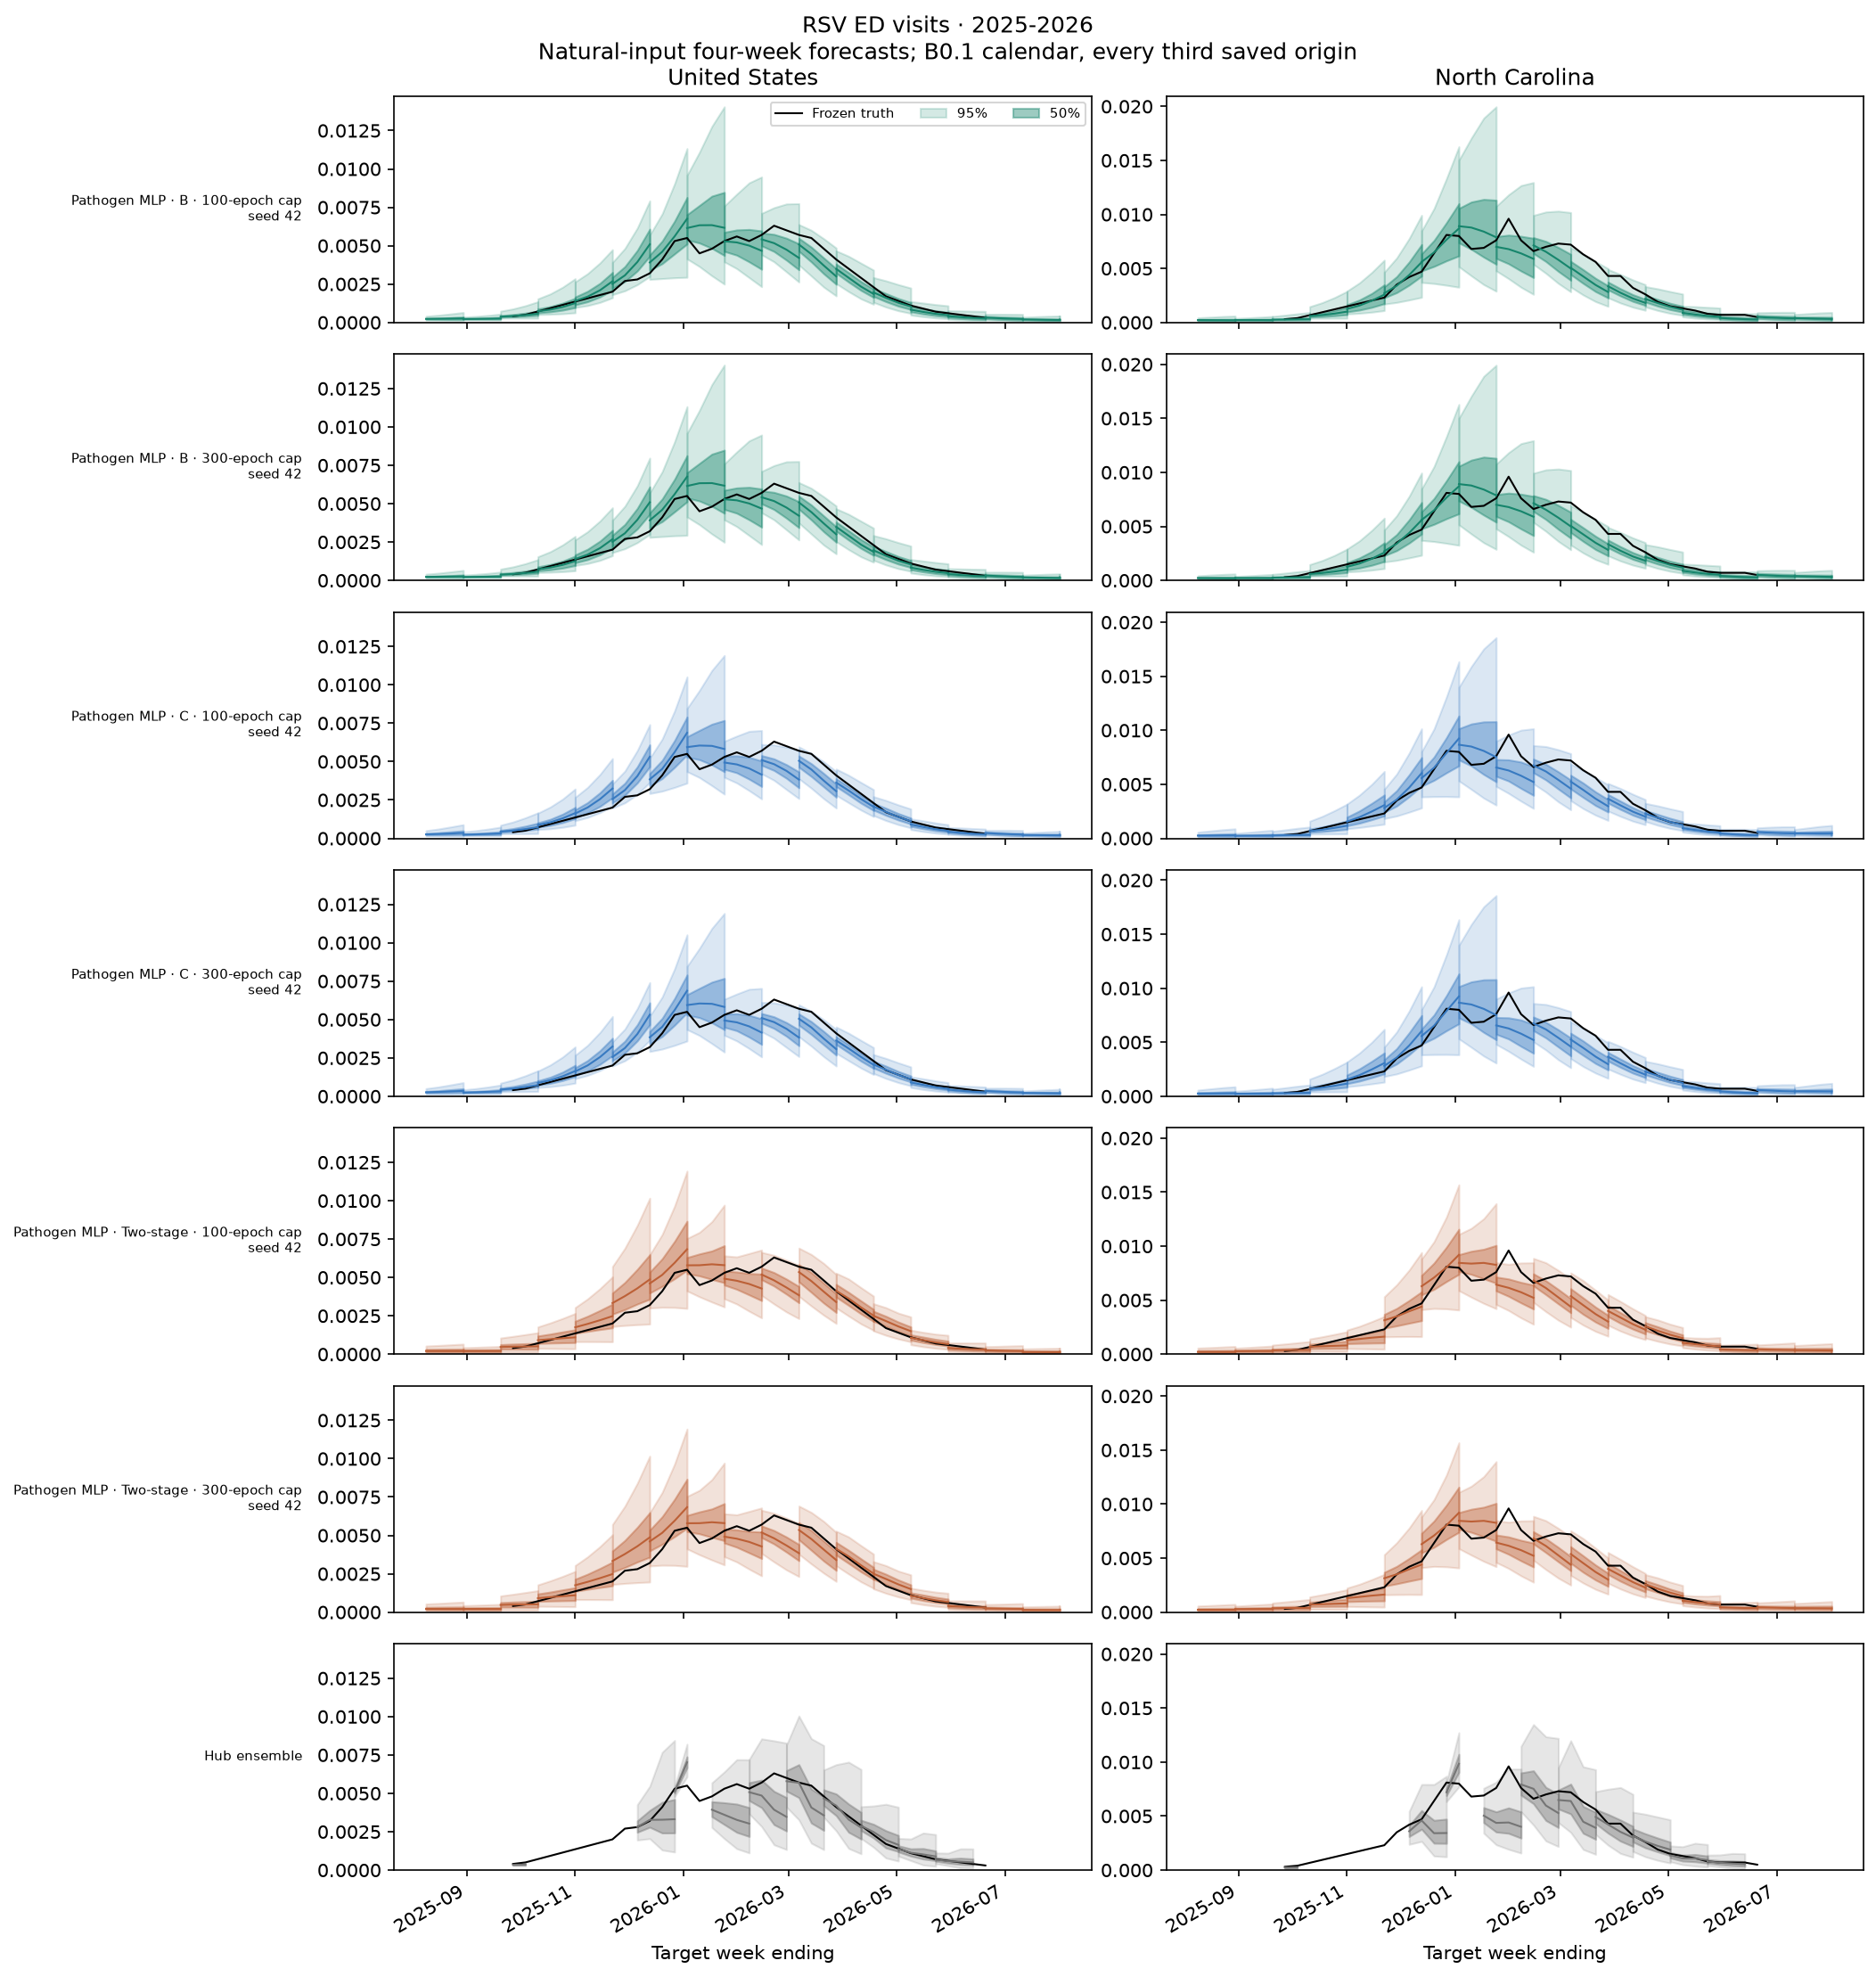
Pathogen MLP B, C, and two-stage at both caps, followed by the Hub ensemble. Every model uses seed 42, the same fixed seed as the original formulation fans. It is illustrative, not an average: pathogen two-stage seed 42 is also the largest observed deterioration, so judge the overall result using all three seeds above. Dates match B0.1's full saved-season calendar; truth and ensemble retain their frozen availability. Missing values are not filled in. Display dates extend beyond scoring support.
Scope, provenance, and reproduction
This remains retrospective development CV on seasons used for model development, not prospective evidence. Three seeds do not resolve small differences. Changing the cap permits longer training and can change checkpoint selection; it does not mean every component trained for 300 epochs. Forecast skill is not a standalone nowcast score.
Matched seed data · Target/season comparisons · Coverage · Snapshot · Run status.
No training or scoring jobs are launched. The revision experiment follows below.
Revision experiment: separating forecasting, nowcasting and reconstruction
160/160 runs complete, generated 2026-09-18T09:18-04:00. This is a dated snapshot of
experiment B1-revisions-20260917 (32 configurations × seeds 42–46). Every run uses
cap 300, patience 30, and selects epochs on future loss only with natural inputs,
so recent accuracy is not an explicit selection criterion. Evaluation uses 1,024 draws.
The three questions are scored on three different supports and are never combined into one number.
1. Best everyday forecast
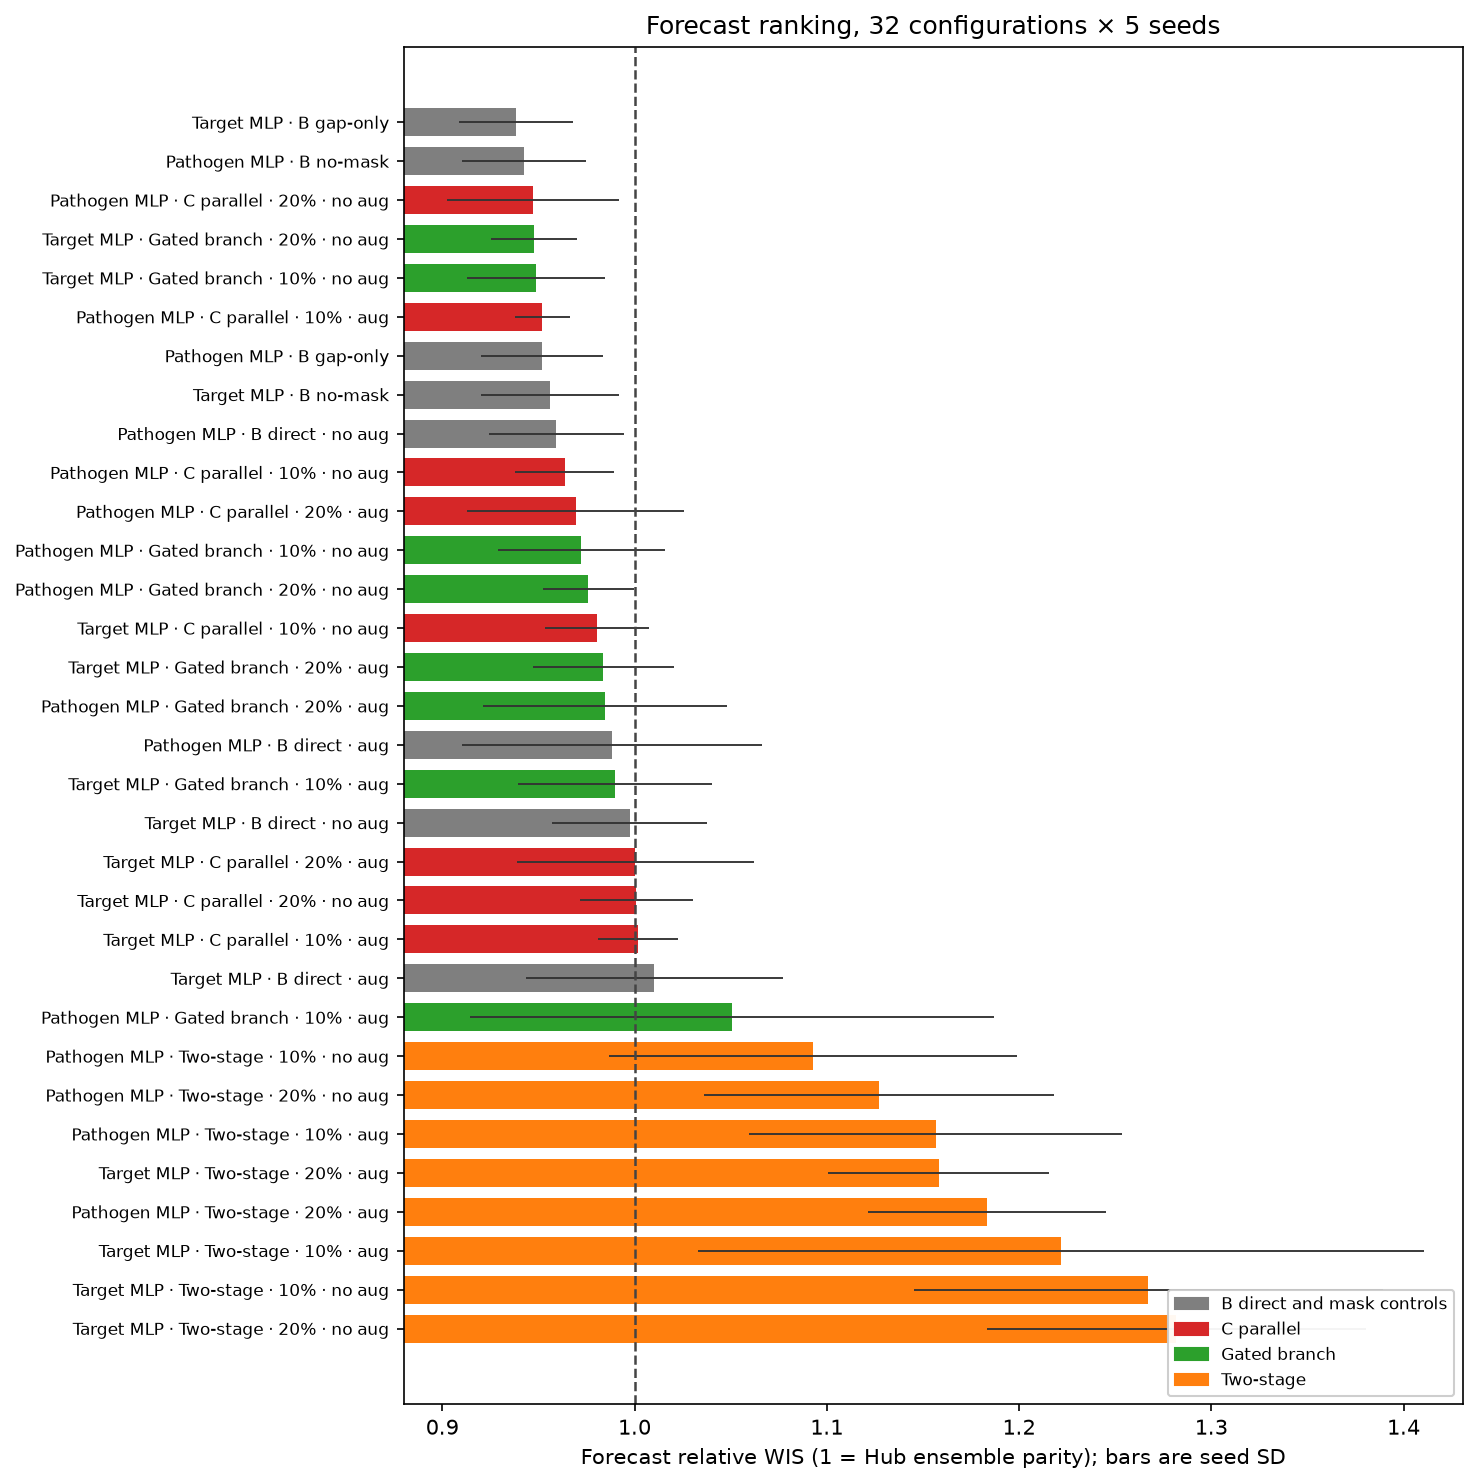
19/32 configuration means beat the Hub ensemble. Lower relative WIS is better; 1 is parity. Seed SD is descriptive, not a confidence interval.
| Configuration | Seeds | WIS ratio | Seed SD |
|---|---|---|---|
| Target MLP · B gap-only | 5 | 0.938 | 0.030 |
| Pathogen MLP · B no-mask | 5 | 0.943 | 0.032 |
| Pathogen MLP · C parallel · 20% · no aug | 5 | 0.947 | 0.045 |
| Target MLP · Gated branch · 20% · no aug | 5 | 0.948 | 0.022 |
| Target MLP · Gated branch · 10% · no aug | 5 | 0.949 | 0.036 |
| Pathogen MLP · C parallel · 10% · aug | 5 | 0.952 | 0.014 |
| Pathogen MLP · B gap-only | 5 | 0.952 | 0.032 |
| Target MLP · B no-mask | 5 | 0.956 | 0.036 |
| Pathogen MLP · B direct · no aug | 5 | 0.959 | 0.035 |
| Pathogen MLP · C parallel · 10% · no aug | 5 | 0.964 | 0.026 |
| Pathogen MLP · C parallel · 20% · aug | 5 | 0.969 | 0.057 |
| Pathogen MLP · Gated branch · 10% · no aug | 5 | 0.972 | 0.044 |
| Pathogen MLP · Gated branch · 20% · no aug | 5 | 0.976 | 0.024 |
| Target MLP · C parallel · 10% · no aug | 5 | 0.981 | 0.027 |
| Target MLP · Gated branch · 20% · aug | 5 | 0.984 | 0.037 |
| Pathogen MLP · Gated branch · 20% · aug | 5 | 0.985 | 0.063 |
| Pathogen MLP · B direct · aug | 5 | 0.988 | 0.078 |
| Target MLP · Gated branch · 10% · aug | 5 | 0.990 | 0.051 |
| Target MLP · B direct · no aug | 5 | 0.997 | 0.040 |
| Target MLP · C parallel · 20% · aug | 5 | 1.000 | 0.062 |
| Target MLP · C parallel · 20% · no aug | 5 | 1.001 | 0.029 |
| Target MLP · C parallel · 10% · aug | 5 | 1.002 | 0.021 |
| Target MLP · B direct · aug | 5 | 1.010 | 0.067 |
| Pathogen MLP · Gated branch · 10% · aug | 5 | 1.051 | 0.136 |
| Pathogen MLP · Two-stage · 10% · no aug | 5 | 1.093 | 0.106 |
| Pathogen MLP · Two-stage · 20% · no aug | 5 | 1.127 | 0.091 |
| Pathogen MLP · Two-stage · 10% · aug | 5 | 1.157 | 0.097 |
| Target MLP · Two-stage · 20% · aug | 5 | 1.158 | 0.057 |
| Pathogen MLP · Two-stage · 20% · aug | 5 | 1.183 | 0.062 |
| Target MLP · Two-stage · 10% · aug | 5 | 1.222 | 0.189 |
| Target MLP · Two-stage · 10% · no aug | 5 | 1.267 | 0.122 |
| Target MLP · Two-stage · 20% · no aug | 5 | 1.282 | 0.099 |
Forecast run scores · Ranking CSV.
The leader is Target MLP · B gap-only at 0.938. The two best configuration means are B gap-only and B no-mask controls. That does not mean all recent-head models worsen forecasting: compare matched backbone, augmentation and seeds, rather than each model against the winner selected from a different recipe.
| Backbone | Augmentation | Recent weight | B forecast | Gated forecast | Delta | Seed delta SD | Improved | Pairs |
|---|---|---|---|---|---|---|---|---|
| pathogen | 0.000 | 0.100 | 0.959 | 0.972 | 0.013 | 0.030 | 1 | 5 |
| pathogen | 0.000 | 0.200 | 0.959 | 0.976 | 0.017 | 0.048 | 1 | 5 |
| pathogen | 0.500 | 0.100 | 0.988 | 1.051 | 0.062 | 0.082 | 1 | 5 |
| pathogen | 0.500 | 0.200 | 0.988 | 0.985 | -0.004 | 0.037 | 3 | 5 |
| target | 0.000 | 0.100 | 0.997 | 0.949 | -0.049 | 0.053 | 4 | 5 |
| target | 0.000 | 0.200 | 0.997 | 0.948 | -0.050 | 0.040 | 5 | 5 |
| target | 0.500 | 0.100 | 1.010 | 0.990 | -0.021 | 0.065 | 3 | 5 |
| target | 0.500 | 0.200 | 1.010 | 0.984 | -0.026 | 0.071 | 3 | 5 |
Without augmentation, target gated-20% improves on matched B from 0.997 to 0.948 (delta -0.050; all five seeds improve). Target gated-10% improves in four of five. Pathogen gated variants without augmentation worsen on average and improve in only one of five seeds each. The branch is promising on the target backbone, not a universally free addition. The target gap-only control still has the best mean at 0.938; we did not cross gated nowcasting with gap-only masking.
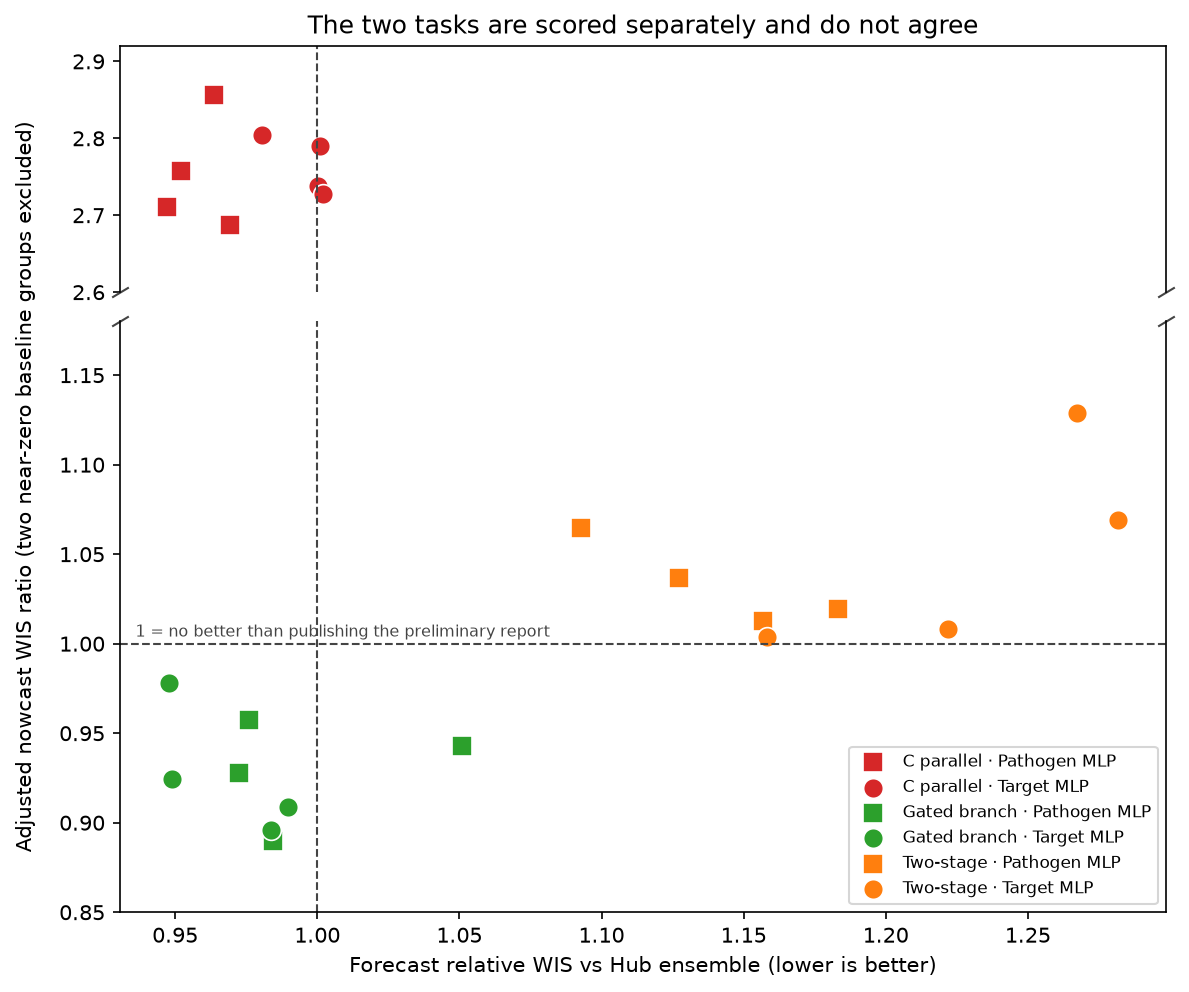
Two-stage remains worse than Hub in every configuration mean (1.093–1.282). C's weak nowcast outputs do not prevent competitive forecast performance: an auxiliary objective can help the shared representation without yielding the best recent-head checkpoint, because selection uses future loss only.
Where the forecast skill sits
Skill is not uniform, and the column structure matters more than the row order. Influenza admissions 2024-2025 is where nearly every configuration wins (0.79–1.02), and RSV ED visits 2025-2026 is the other consistent gain. COVID-19 ED visits 2025-2026 is the weak column: most configurations sit above parity there. The two-stage penalty is not spread evenly either — it concentrates in influenza admissions 2023-2024 and COVID-19 ED visits, where it reaches 1.4–1.7, while two-stage remains competitive on RSV. Disease → target → chronological season, matching the fan order.
2. Does nowcasting improve the report?
Scored against each target week's own genuine preliminary report, excluding supplied finals and cells without that report. Values below 1 mean the model improves on simply publishing the preliminary number.
| Configuration | Adjusted location ratio | Seed SD | Pooled sensitivity | Registered unfiltered |
|---|---|---|---|---|
| Pathogen MLP · Gated branch · 20% · aug | 0.890 | 0.031 | 0.618 | 1302.329 |
| Target MLP · Gated branch · 20% · aug | 0.896 | 0.050 | 0.629 | 1103.122 |
| Target MLP · Gated branch · 10% · aug | 0.909 | 0.063 | 0.643 | 1130.843 |
| Target MLP · Gated branch · 10% · no aug | 0.924 | 0.066 | 0.631 | 2093.271 |
| Pathogen MLP · Gated branch · 10% · no aug | 0.928 | 0.102 | 0.631 | 1403.606 |
| Pathogen MLP · Gated branch · 10% · aug | 0.943 | 0.079 | 0.646 | 1224.309 |
| Pathogen MLP · Gated branch · 20% · no aug | 0.957 | 0.040 | 0.639 | 1968.076 |
| Target MLP · Gated branch · 20% · no aug | 0.978 | 0.025 | 0.649 | 2269.560 |
| Target MLP · Two-stage · 20% · aug | 1.004 | 0.056 | 0.699 | 1555.523 |
| Target MLP · Two-stage · 10% · aug | 1.008 | 0.056 | 0.695 | 2002.376 |
| Pathogen MLP · Two-stage · 10% · aug | 1.013 | 0.078 | 0.696 | 1651.862 |
| Pathogen MLP · Two-stage · 20% · aug | 1.019 | 0.058 | 0.701 | 1522.900 |
| Pathogen MLP · Two-stage · 20% · no aug | 1.037 | 0.060 | 0.691 | 1446.413 |
| Pathogen MLP · Two-stage · 10% · no aug | 1.064 | 0.051 | 0.710 | 1857.362 |
| Target MLP · Two-stage · 20% · no aug | 1.069 | 0.068 | 0.711 | 1904.148 |
| Target MLP · Two-stage · 10% · no aug | 1.129 | 0.136 | 0.737 | 2050.993 |
| Pathogen MLP · C parallel · 20% · aug | 2.687 | 0.108 | 1.480 | 18292.175 |
| Pathogen MLP · C parallel · 20% · no aug | 2.711 | 0.139 | 1.485 | 19166.067 |
| Target MLP · C parallel · 10% · aug | 2.728 | 0.060 | 1.509 | 18560.344 |
| Target MLP · C parallel · 20% · aug | 2.737 | 0.139 | 1.501 | 17134.153 |
| Pathogen MLP · C parallel · 10% · aug | 2.757 | 0.043 | 1.519 | 20909.445 |
| Target MLP · C parallel · 20% · no aug | 2.790 | 0.117 | 1.522 | 16862.246 |
| Target MLP · C parallel · 10% · no aug | 2.805 | 0.060 | 1.535 | 19606.933 |
| Pathogen MLP · C parallel · 10% · no aug | 2.857 | 0.121 | 1.569 | 20907.380 |
Gated is the strongest recent-head family under both displayed aggregations. The eight gated means are 0.890–0.978 under the location-relative metric after the two-group exclusion below. The best point estimate is about 11% lower WIS on that adjusted metric; it is not a universal 11% reduction in count error or a proven improvement in every target/season.
Two-stage is 1.004–1.129 under that metric, but 0.691–0.737 under pooled scoring. It therefore improves on reports under one aggregation while failing to improve under the other. C is worse under both (2.69–2.86 adjusted location-relative; 1.48–1.57 pooled). WIS ratios measure distributional score, not simply point error.
The family ordering gated < two-stage < C survives pooling; the exact configuration ordering does not. Pooling sums numerator and denominator within target/season before taking their ratio, thereby changing location importance and losing the prescribed states/DC 80% versus US 20% weighting. It is a sensitivity analysis, not a confirmation of the same estimand.
Reporting ages, accuracy and uncertainty
| Formulation | Age (days) | Scaled CRPS | Report error | Relative CRPS | 50% coverage | 95% coverage |
|---|---|---|---|---|---|---|
| C parallel | 11 | 0.045 | 0.018 | 2.534 | 0.456 | 0.863 |
| C parallel | 4 | 0.023 | 0.027 | 0.853 | 0.631 | 0.942 |
| Gated branch | 11 | 0.014 | 0.018 | 0.781 | 0.508 | 0.863 |
| Gated branch | 4 | 0.020 | 0.027 | 0.727 | 0.444 | 0.837 |
| Two-stage | 11 | 0.015 | 0.018 | 0.835 | 0.587 | 0.885 |
| Two-stage | 4 | 0.021 | 0.027 | 0.770 | 0.492 | 0.865 |
This additional full-support diagnostic divides each cell's CRPS and unchanged-report absolute error by its model's training-only target/location Q95 scale, then averages locations with states/DC 80% and US 20%, targets with admissions 1 and ED .5, and seasons equally, keeping ages separate. It retains the two near-zero-baseline groups: there is no division by their individual report errors. Relative CRPS is the ratio of the displayed aggregate scores. It is a different, explicitly labelled metric, not a replacement WIS ranking. Values shown are descriptive means across all eight configurations and five seeds in each family; they are not independent replicates or the performance of an ensemble. Target/season support can differ by reporting age.
The age split matters: C has relative scaled CRPS about 2.53 for the preceding 11-day-old week, but 0.85 for the newest four-day-old week. Calling C useless at every revision task is therefore incorrect. Gated improves both ages (about 0.78 and 0.73), and two-stage also improves on this alternative metric (0.83 and 0.77). C's anchoring both recent outputs to the latest observation is a concrete hypothesis for its older-week weakness, not a proven cause. Gated is not fully calibrated: natural 95% coverage is only about 86% and 84%, respectively, despite its competitive error scores. Newest-week 50% coverage is about 44%.
Near-zero report error makes the registered ratio unstable
The unfiltered registered scorer averages per-location ratios. Two target/season/location groups — ID (RSV ED visits, 2023-2024); VA (RSV ED visits, 2023-2024) — have report-versus-final errors near floating-point precision. Positive denominators near 1e-10 yield extremely large ratios. This is a fragile metric in the presence of a nearly perfect baseline, not evidence of a thousandfold error in predictions.
The adjusted columns exclude groups with total baseline WIS below 1e-6 in native units, an explicitly post-hoc threshold. This excludes 2 of 819 target/season/location groups, not two individual forecast observations. They still matter for absolute error: a model should not damage an accurate report. Only the adjusted nowcast ratio columns exclude them; the new scaled diagnostics retain them. Forecast rankings are unchanged. See small denominators and threshold sensitivity. Each group contains ten observations per run. Cutoffs from 1e-9 through 1e-5 remove the same two groups and give identical adjusted scores; this numerical sensitivity result does not turn the post-hoc choice into a predefined endpoint.
The prelaunch audit checked for exactly zero aggregate errors and found none. That statement was literally true but insufficient to check numerical stability; it did not rule out near-zero positive denominators. Neither deleting these groups nor changing to pooling should silently replace the predefined endpoint.
3. Can it reconstruct missing observations?
The per-cell diagnostics separate a genuine revision of a visible report from an artificially hidden observation, which is the reconstruction task.
| Formulation | Age (days) | Report condition | Scaled CRPS | 50% coverage | 95% coverage |
|---|---|---|---|---|---|
| C parallel | 11 | hidden | 0.051 | 0.443 | 0.864 |
| C parallel | 11 | visible | 0.042 | 0.460 | 0.862 |
| C parallel | 4 | hidden | 0.063 | 0.336 | 0.731 |
| C parallel | 4 | visible | 0.021 | 0.651 | 0.945 |
| Gated branch | 11 | hidden | 0.045 | 0.538 | 0.890 |
| Gated branch | 11 | visible | 0.014 | 0.517 | 0.856 |
| Gated branch | 4 | hidden | 0.055 | 0.480 | 0.864 |
| Gated branch | 4 | visible | 0.018 | 0.452 | 0.843 |
| Two-stage | 11 | hidden | 0.047 | 0.354 | 0.709 |
| Two-stage | 11 | visible | 0.014 | 0.591 | 0.882 |
| Two-stage | 4 | hidden | 0.063 | 0.297 | 0.640 |
| Two-stage | 4 | visible | 0.019 | 0.506 | 0.874 |
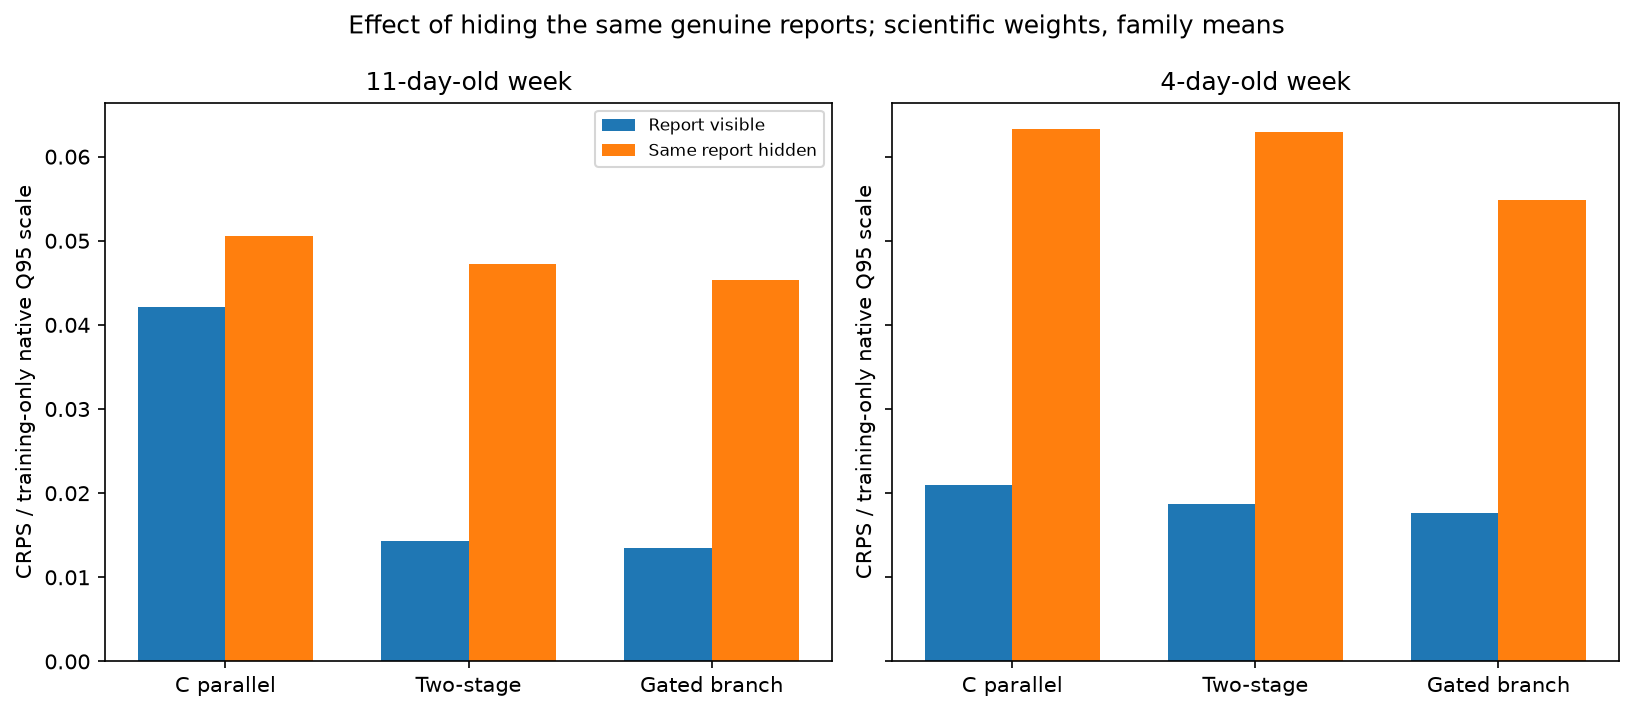
Hiding an observation worsens recent estimation, but the old 7-versus-18 CRPS comparison was not a valid scientific aggregate. It averaged admissions counts and ED proportions in native units with cell-count weights, and compared different sets of observations. The replacement table/figure pairs each genuinely preliminary report hidden by the recent stress with its own natural-input result, normalizes CRPS by the training-only Q95 scale, and applies the scientific weights. Supplied finals are not in this paired comparison. Both 50% and 95% coverage are shown by age; approximate overall 50% coverage alone does not establish calibration.
The table averages the eight configurations and five seeds within each family. It is descriptive of these fitted recipes; paired masking identifies the effect of this whole stress intervention, which can hide multiple channels/locations at once.
For gated, hiding the same report increases scaled CRPS from about 0.014 to 0.045 at 11 days, and 0.018 to 0.055 at four days. Reconstruction 95% coverage is about 89% and 86%, below nominal; two-stage is substantially lower, about 71% and 64%. The near-nominal gated 50% coverage is encouraging, but is not full calibration.
Full-channel outage is a separate, more severe condition (all reconstruction cells here, including hidden supplied finals; not the matched report-only subset):
| Formulation | Age (days) | Scaled CRPS | Predict-zero error | 50% coverage | 95% coverage |
|---|---|---|---|---|---|
| C parallel | 11 | 0.289 | 0.325 | 0.137 | 0.226 |
| C parallel | 4 | 0.286 | 0.321 | 0.137 | 0.219 |
| Gated branch | 11 | 0.285 | 0.325 | 0.145 | 0.239 |
| Gated branch | 4 | 0.281 | 0.321 | 0.150 | 0.243 |
| Two-stage | 11 | 0.248 | 0.325 | 0.168 | 0.322 |
| Two-stage | 4 | 0.242 | 0.321 | 0.181 | 0.338 |
Outage scores reveal a model failure mode, not a demonstrated scorer bug
The old native-unit aggregate places 16 C/gated configurations very close to 84.11 for seed 42. Similar aggregate scores do not prove identical predictions or a bypassed recent head. The frozen code does execute C's recent heads and the gated model's separate missing-value heads under outage. When focal history is absent, both use B's small 0.01 transformed anchor, and decoded admission nowcasts remain near zero. Across all audited C/gated runs, every exported outage admission median is zero after count rounding, while ED predictions differ. That is model behavior worth reporting, not a reason to discard the condition. Exact causal attribution to anchoring requires an ablation; the near-zero behavior is consistent with this design.
Count-dominated raw pooling can conceal differences in ED outputs. See outage by target for predicted medians and comparison to predicting zero, and scaled diagnostics for normalization and coverage. The old raw summary is retained only as an audit artifact, not as a ranking or evidence that the scorer substitutes a prior.
Factors: augmentation and objective weight
| Factor | Formulation | Task | Δ WIS | Seed Δ SD | Improved |
|---|---|---|---|---|---|
| Revision augmentation on | B direct | forecast | 0.021 | 0.054 | 4/10 |
| Revision augmentation on | C parallel | forecast | 0.008 | 0.031 | 8/20 |
| Revision augmentation on | C parallel | nowcast | -0.063 | 0.117 | 14/20 |
| Revision augmentation on | Two-stage | forecast | -0.012 | 0.137 | 13/20 |
| Revision augmentation on | Two-stage | nowcast | -0.064 | 0.110 | 15/20 |
| Revision augmentation on | Gated branch | forecast | 0.041 | 0.071 | 5/20 |
| Revision augmentation on | Gated branch | nowcast | -0.038 | 0.079 | 14/20 |
| Nowcast weight 10%→20% | C parallel | forecast | 0.005 | 0.046 | 12/20 |
| Nowcast weight 10%→20% | C parallel | nowcast | -0.055 | 0.119 | 13/20 |
| Nowcast weight 10%→20% | Two-stage | forecast | 0.003 | 0.123 | 10/20 |
| Nowcast weight 10%→20% | Two-stage | nowcast | -0.021 | 0.095 | 9/20 |
| Nowcast weight 10%→20% | Gated branch | forecast | -0.017 | 0.054 | 13/20 |
| Nowcast weight 10%→20% | Gated branch | nowcast | 0.004 | 0.070 | 8/20 |
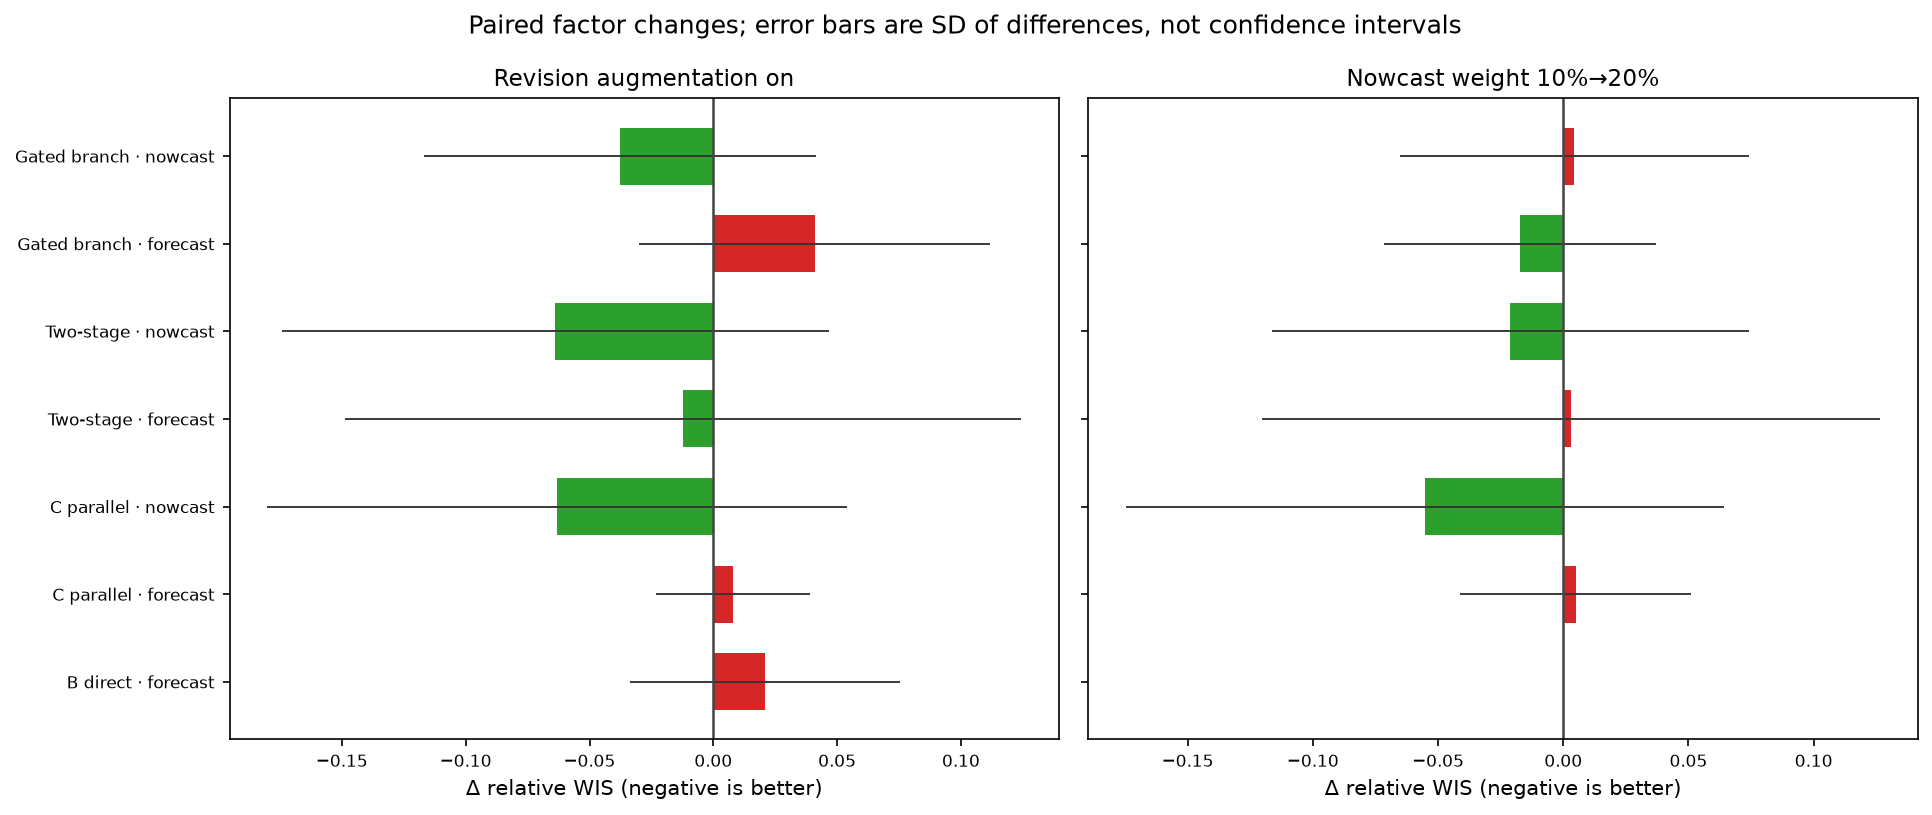
Augmentation produces a trade-off, not a uniform gain. On the adjusted nowcast metric it improves the mean in all three recent-head families. Its forecast effect depends on formulation: B +0.021, C +0.008, gated +0.041 (worse), two-stage -0.012 (better). For gated models only 5/20 matched forecast contrasts improve. Do not label the pooled +0.014 across families as a universal mild effect. The natural revision error is not interchangeable with reconstruction error.
The 10%→20% effect is formulation-dependent. C's adjusted nowcast mean improves by 0.055, two-stage by 0.021, while gated changes by +0.004. Forecast changes are small on average (gated -0.017, C +0.005, two-stage +0.003). The prior statement that neither task moves by more than 0.02 was incorrect. There is no universal winner between the weights, but the screen does not establish that weight is irrelevant.
Error bars show SD of paired differences, pooled over several related settings; they are not confidence intervals. Crossing zero is not a significance test. Five seeds measure fitting variability on the same seasons, not uncertainty over future epidemics. These tables provide effect sizes and direction counts, not a formal claim of superiority or equivalence.
Conclusions and next decisions
- For forecasting alone, retain target B gap-only and pathogen B no-mask as strong controls. Target gated without augmentation is a competitive joint-output candidate and improves matched mixed-mask B; it does not yet beat the best control.
- Forecasts and nowcasts need not come from the same fitted model. B forecasts plus gated recent estimates are a valid separate-output option; this does not establish a coherent joint trajectory distribution or a new combined score.
- For revision correction, gated is the most promising tested family. Its advantage over C/two-stage survives the two displayed aggregation choices, while the claim that only gated beats the report does not. The 11% headline is conditional on the post-hoc location-relative calculation; inspect age-specific scaled errors and coverage too.
- For reconstruction, use matched, scaled, age-specific diagnostics. Treat near-zero outage admissions as a real failure to address, rather than discarding the test.
- The next useful architecture control is a parallel recent head anchored to each week's own report, with a learned missing-history anchor. C currently anchors both recent outputs to the latest visible focal value, unlike the gated branch. This could explain part of its older-week weakness, but is not isolated by these runs. The experiment changes several architectural details, so it does not prove that the gate or forecast feedback alone causes the improvement.
- Try the gated branch with the successful gap-only mask and no revision augmentation; retain B with the same recipe. Do not select augmentation merely because it helps the revision endpoint while worsening the primary forecast endpoint.
- Natural forecast-only validation is now consistent across candidates, but there is no contemporaneous masked-validation control in this experiment. Its independent causal benefit is not identified by comparing with older screens.
- All results remain retrospective development CV with finalized older history and supplied-final fallbacks. None resolves untouched future-season performance or establishes the effect of seasonal reporting shifts.
The archived corrections aggregate saved scores; no models were retrained or repredicted.
Forecast fans
Fan plots
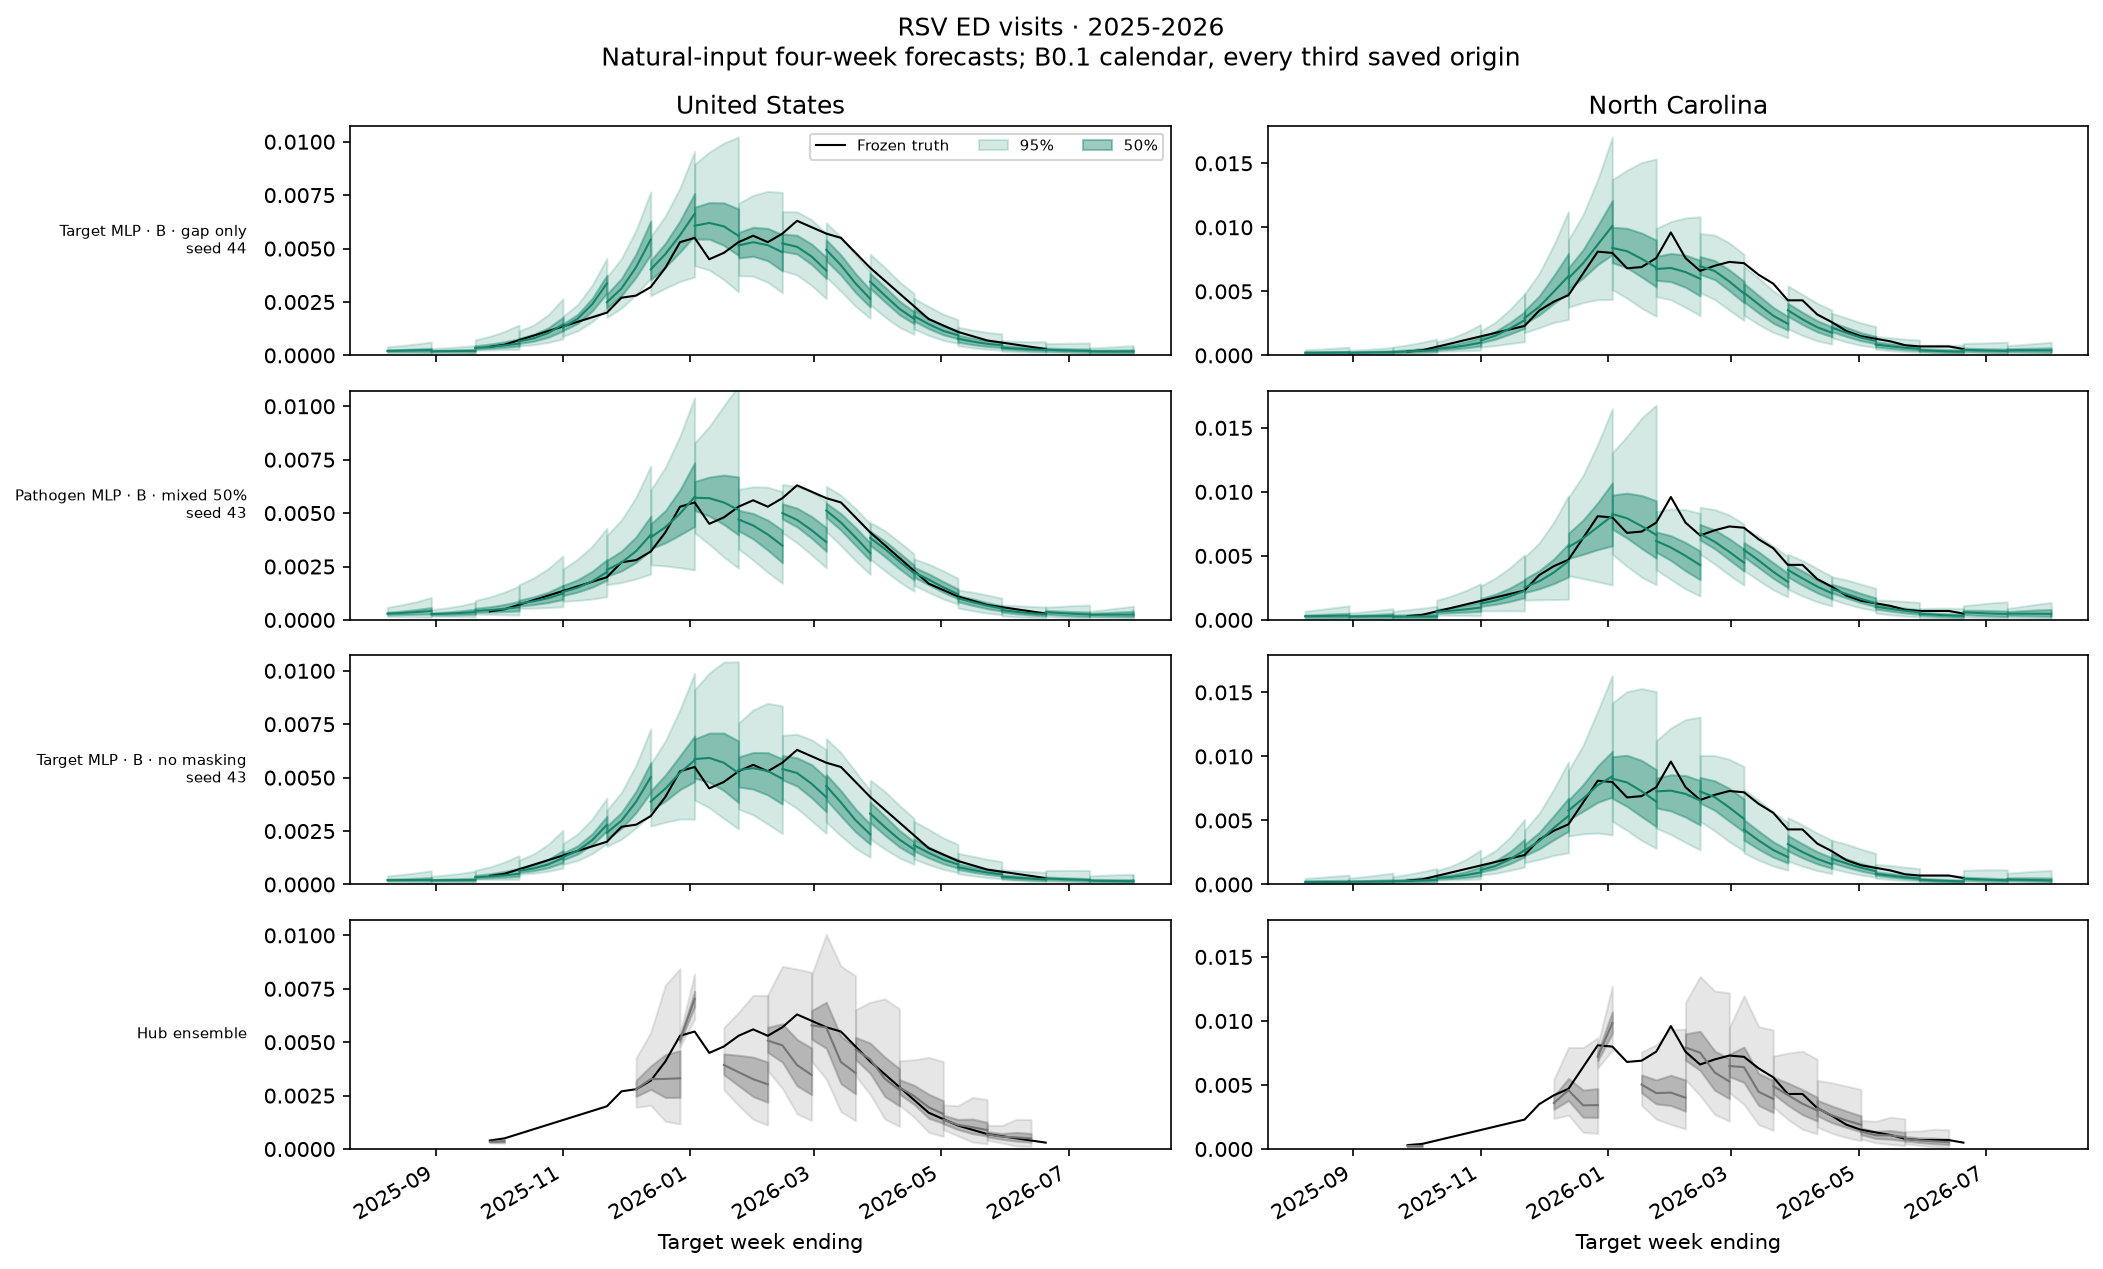
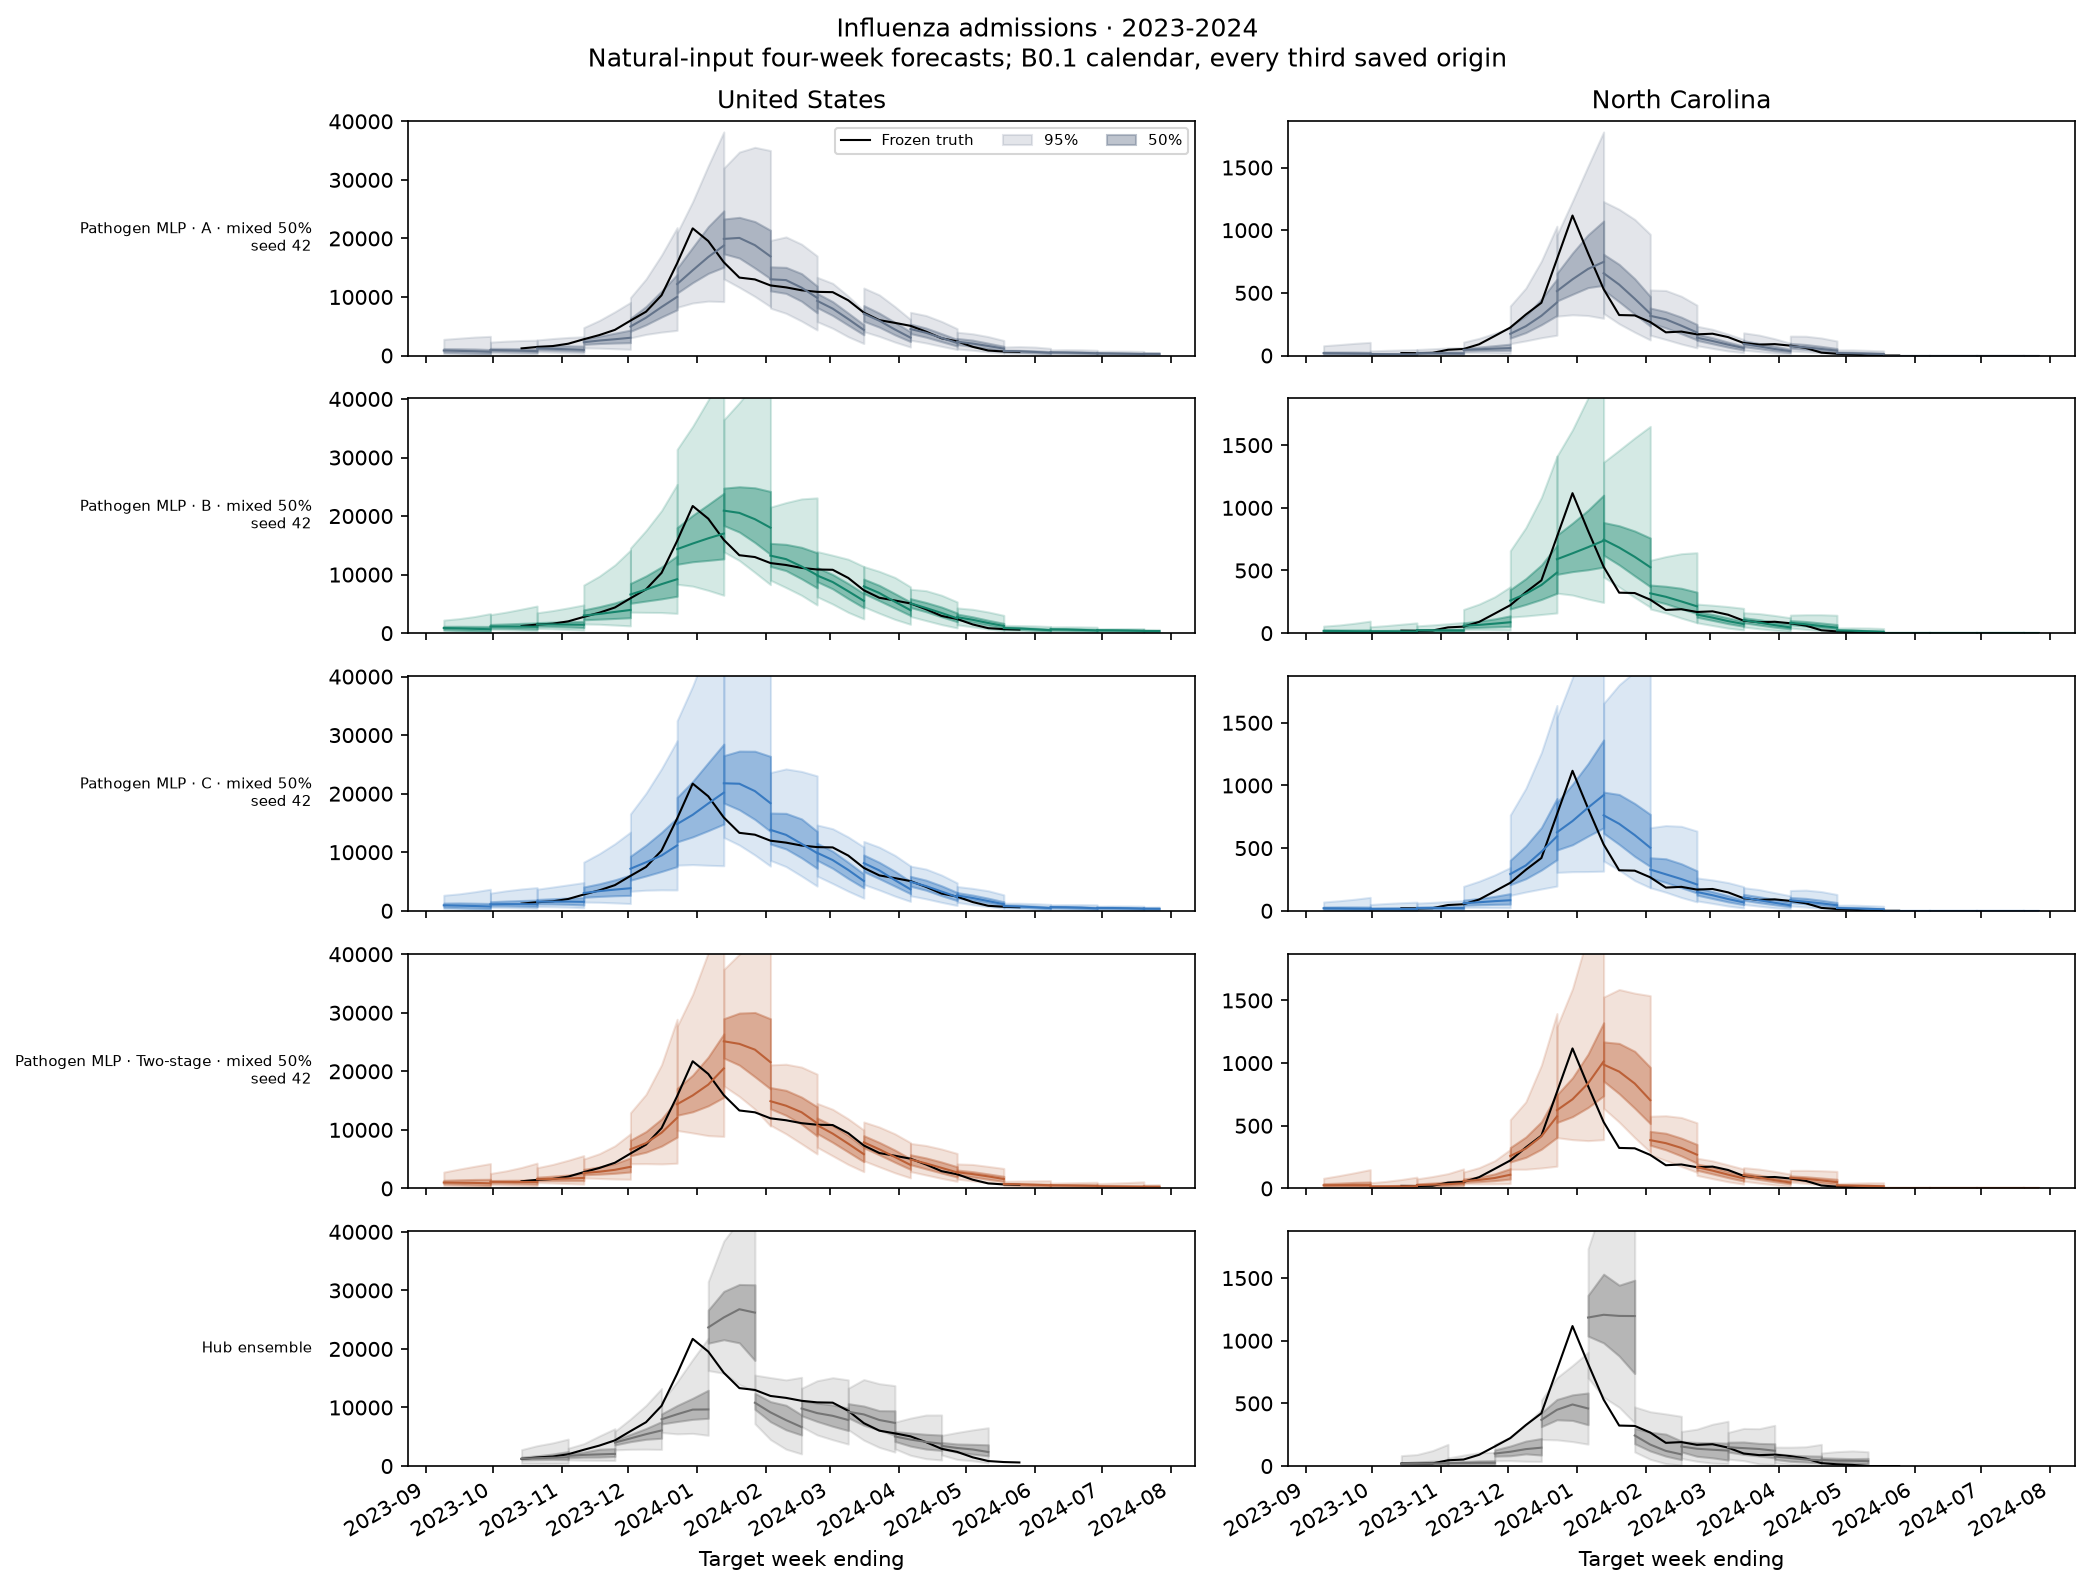
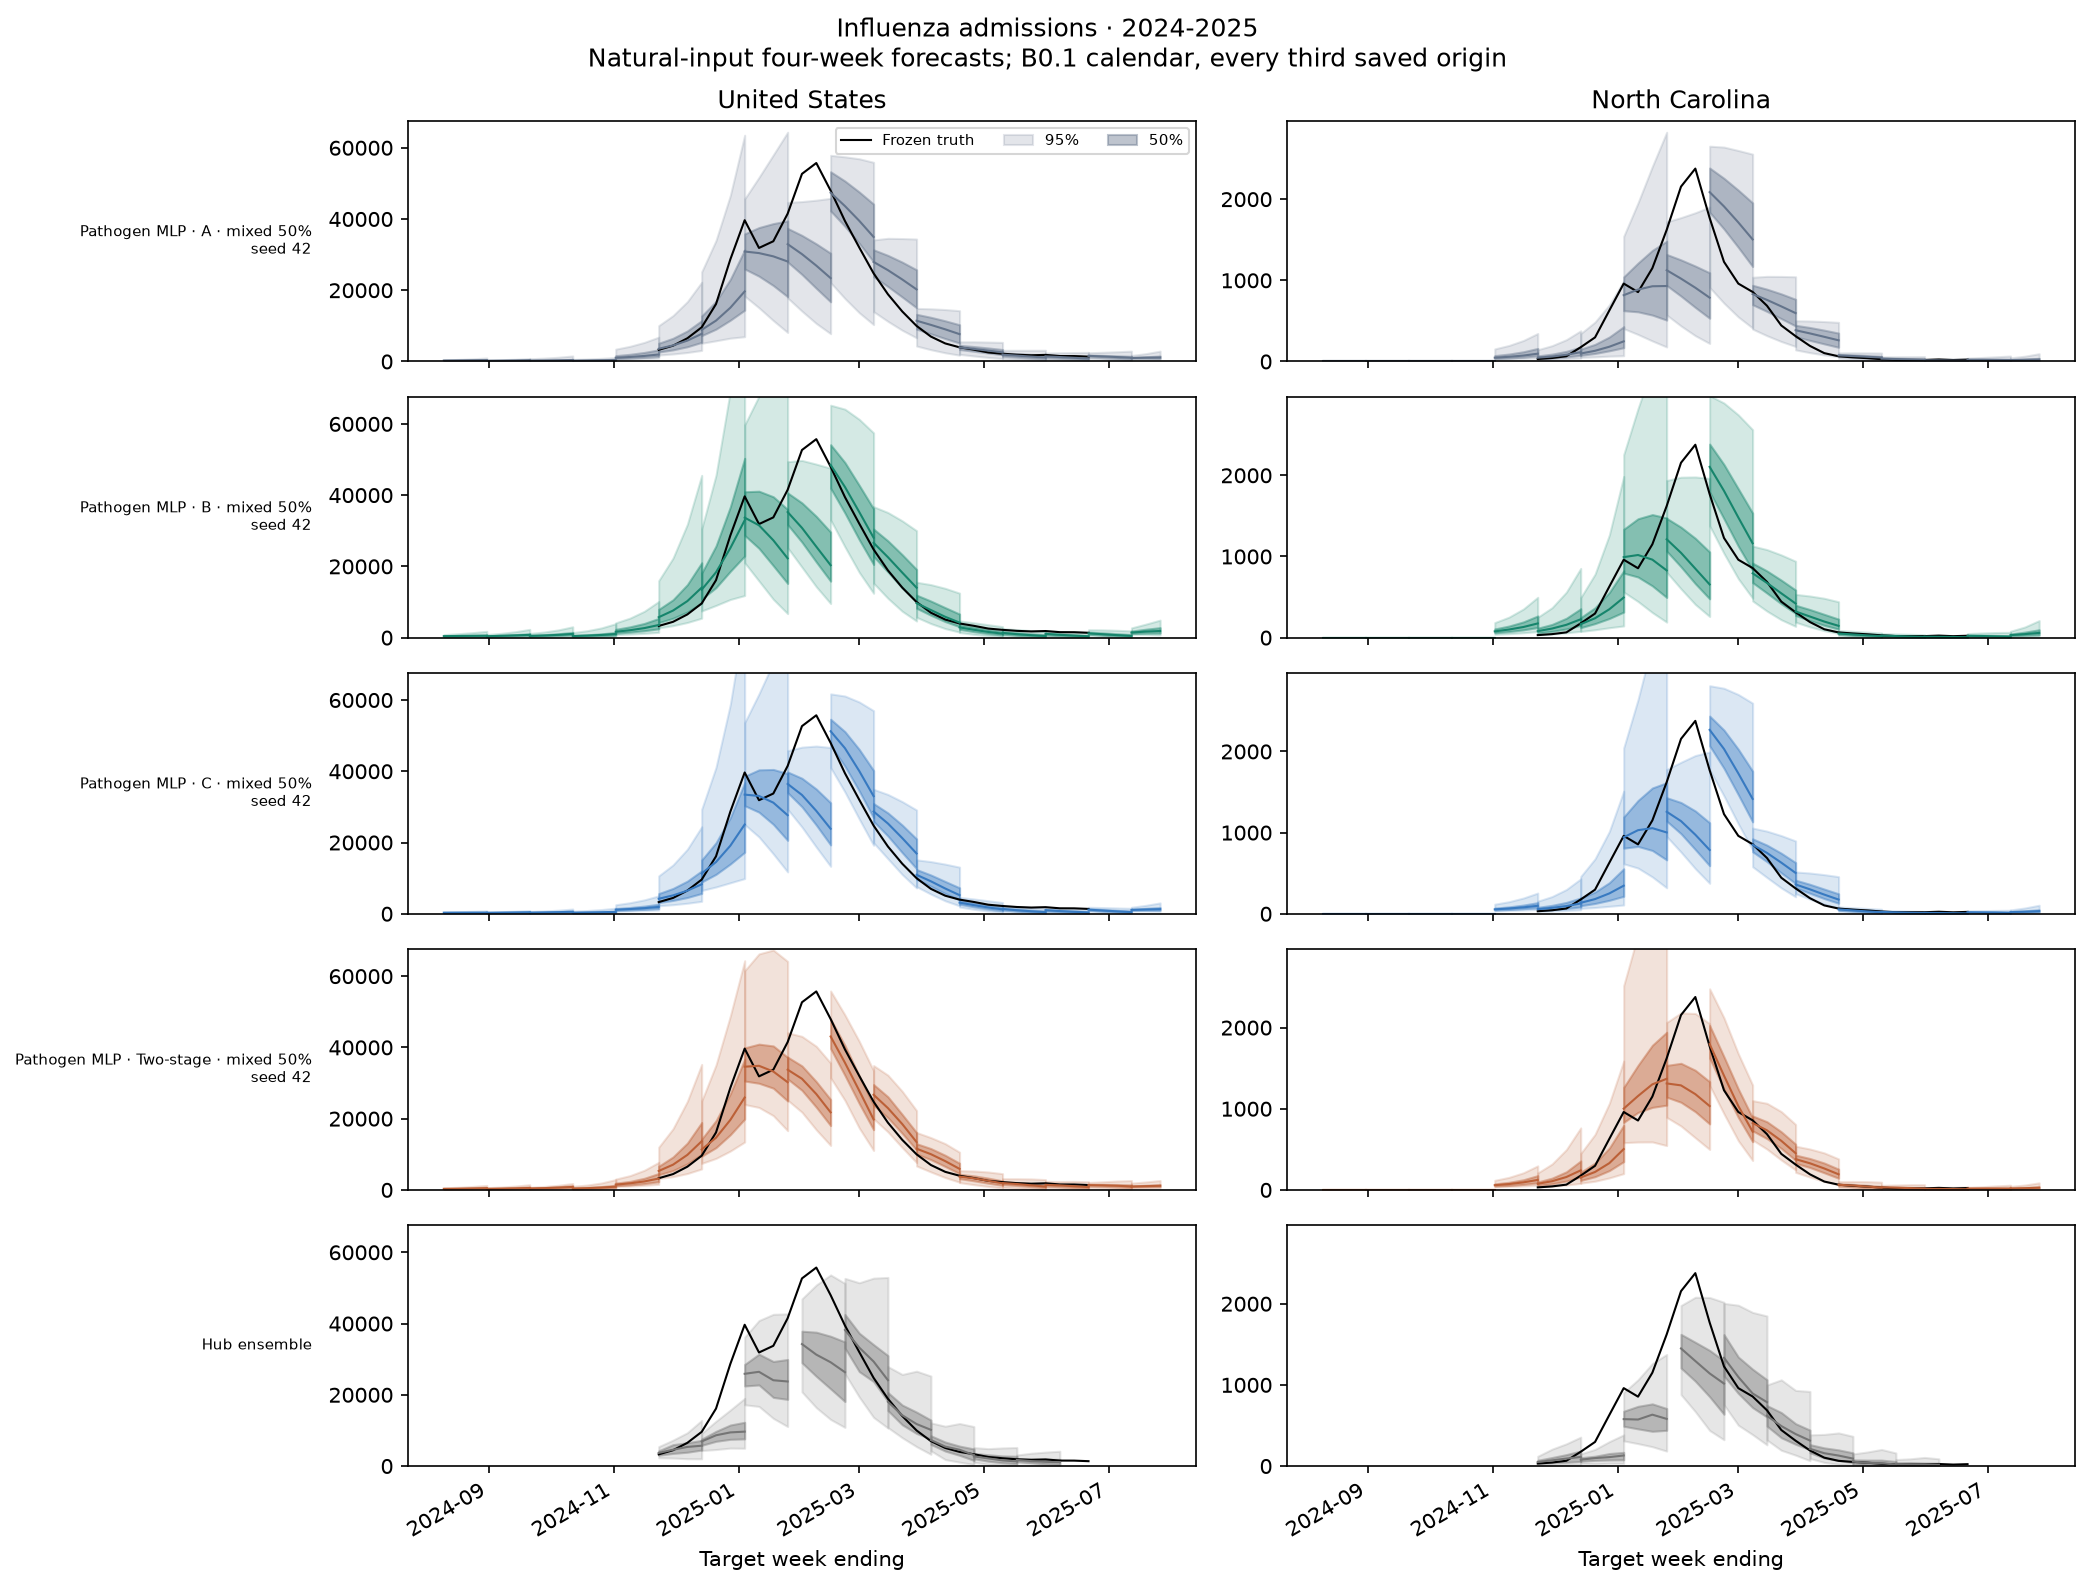
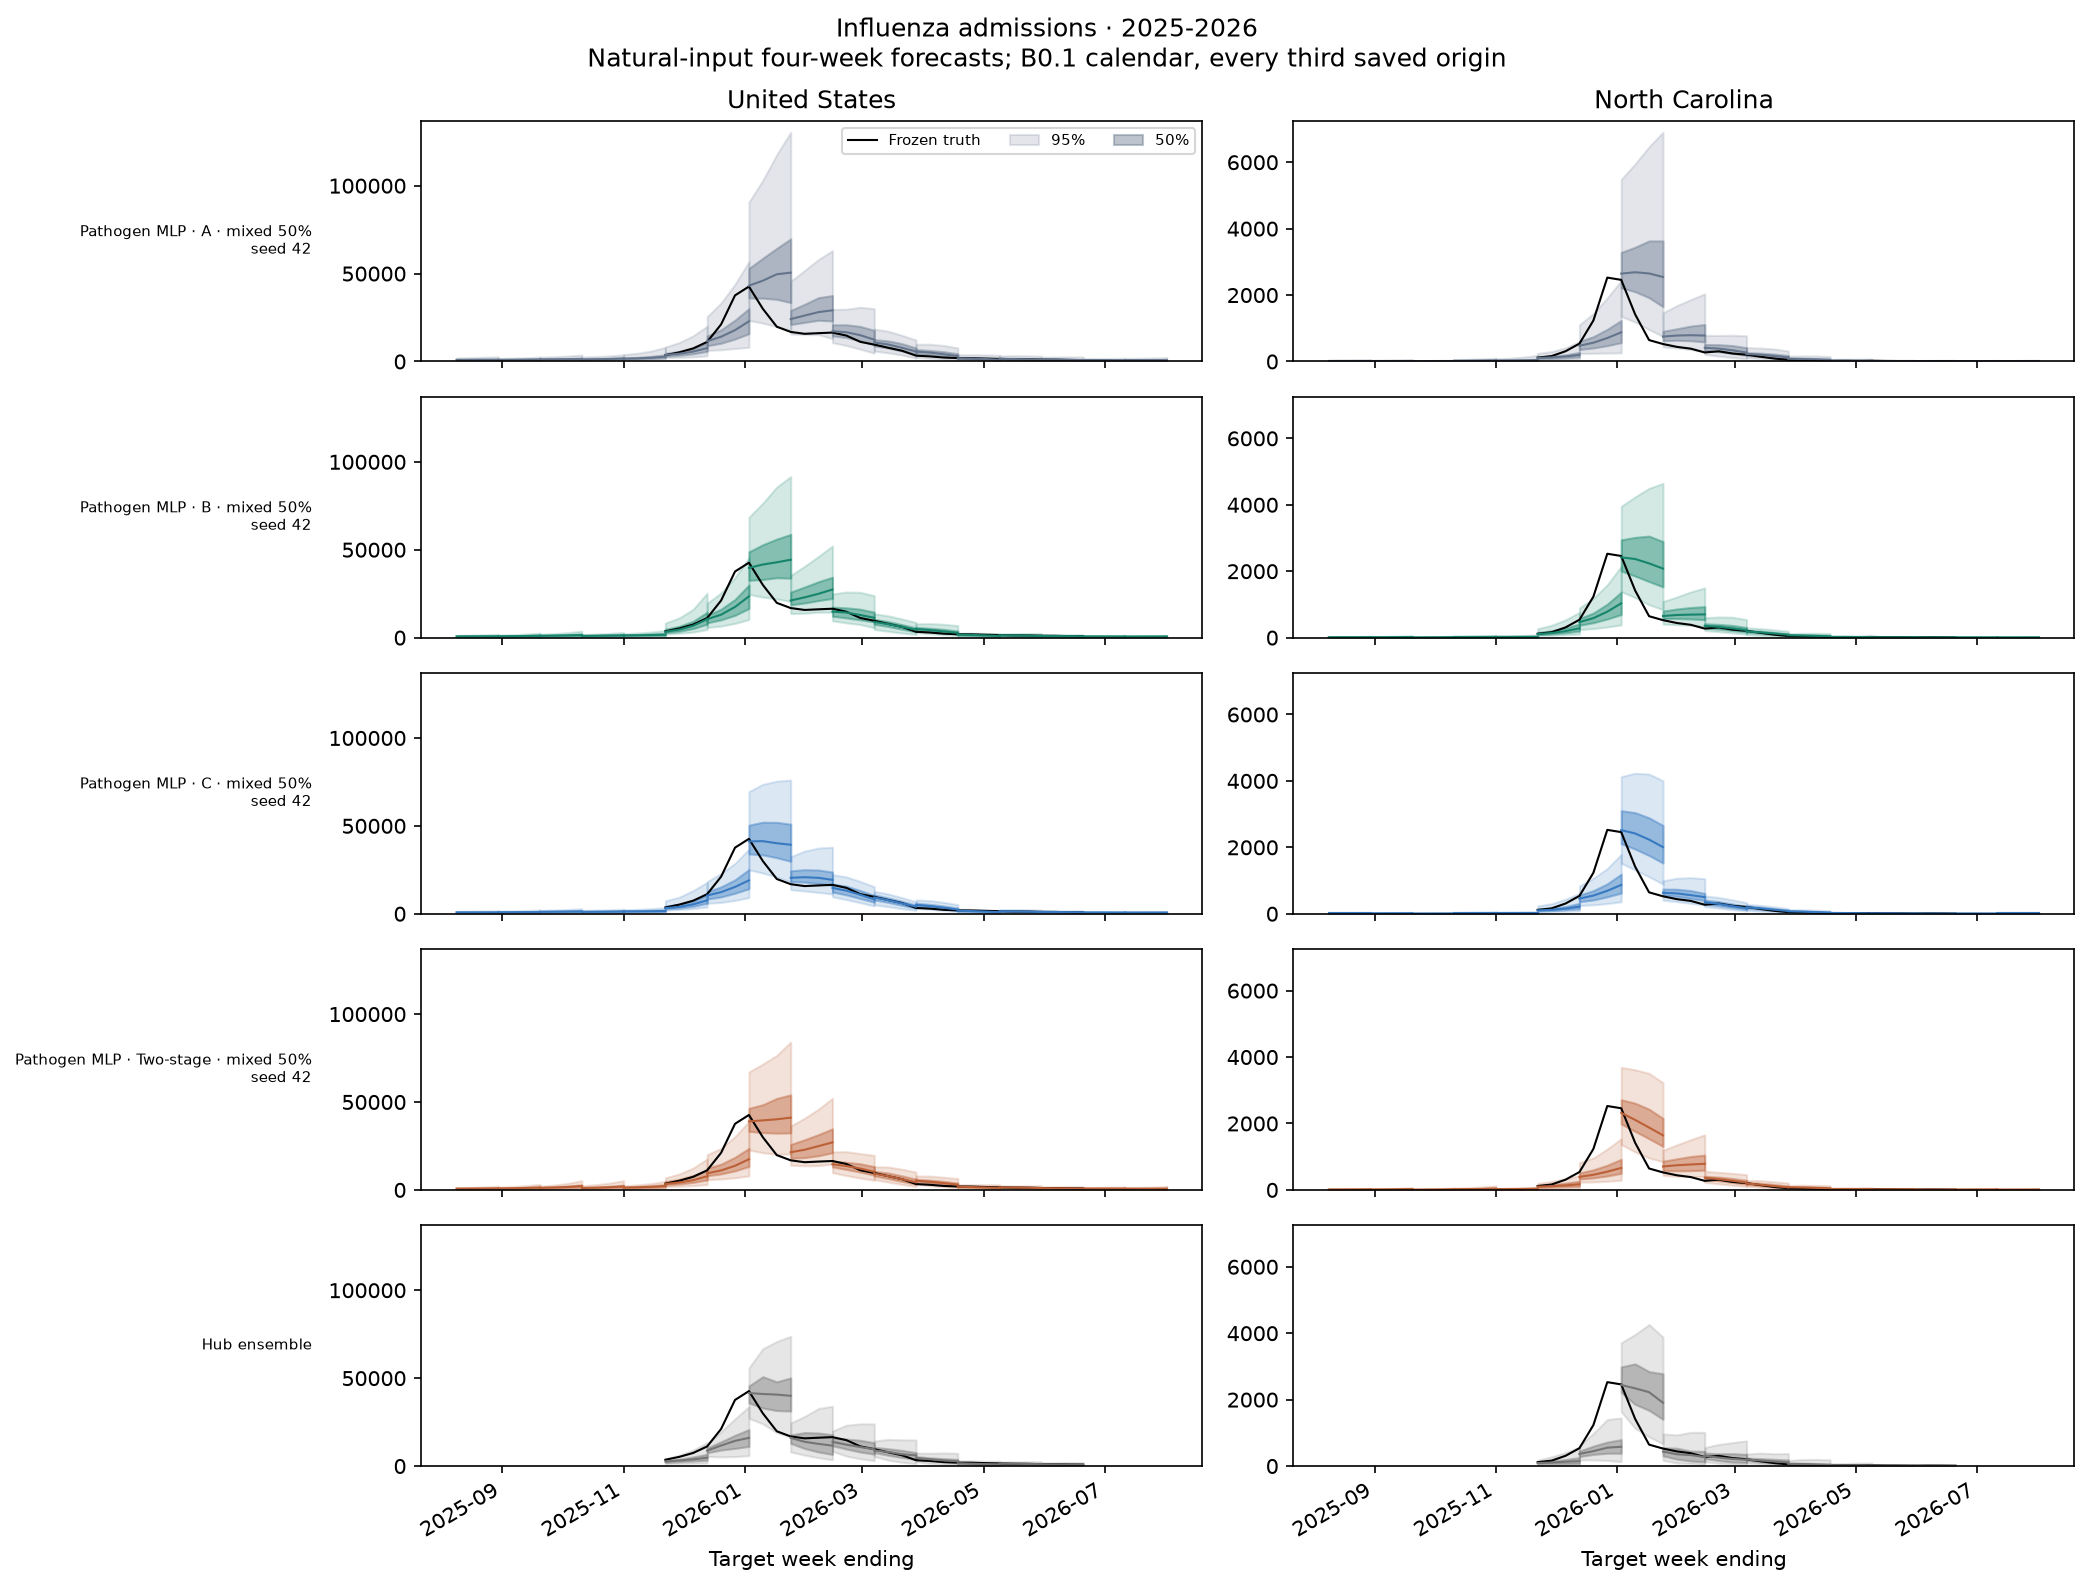
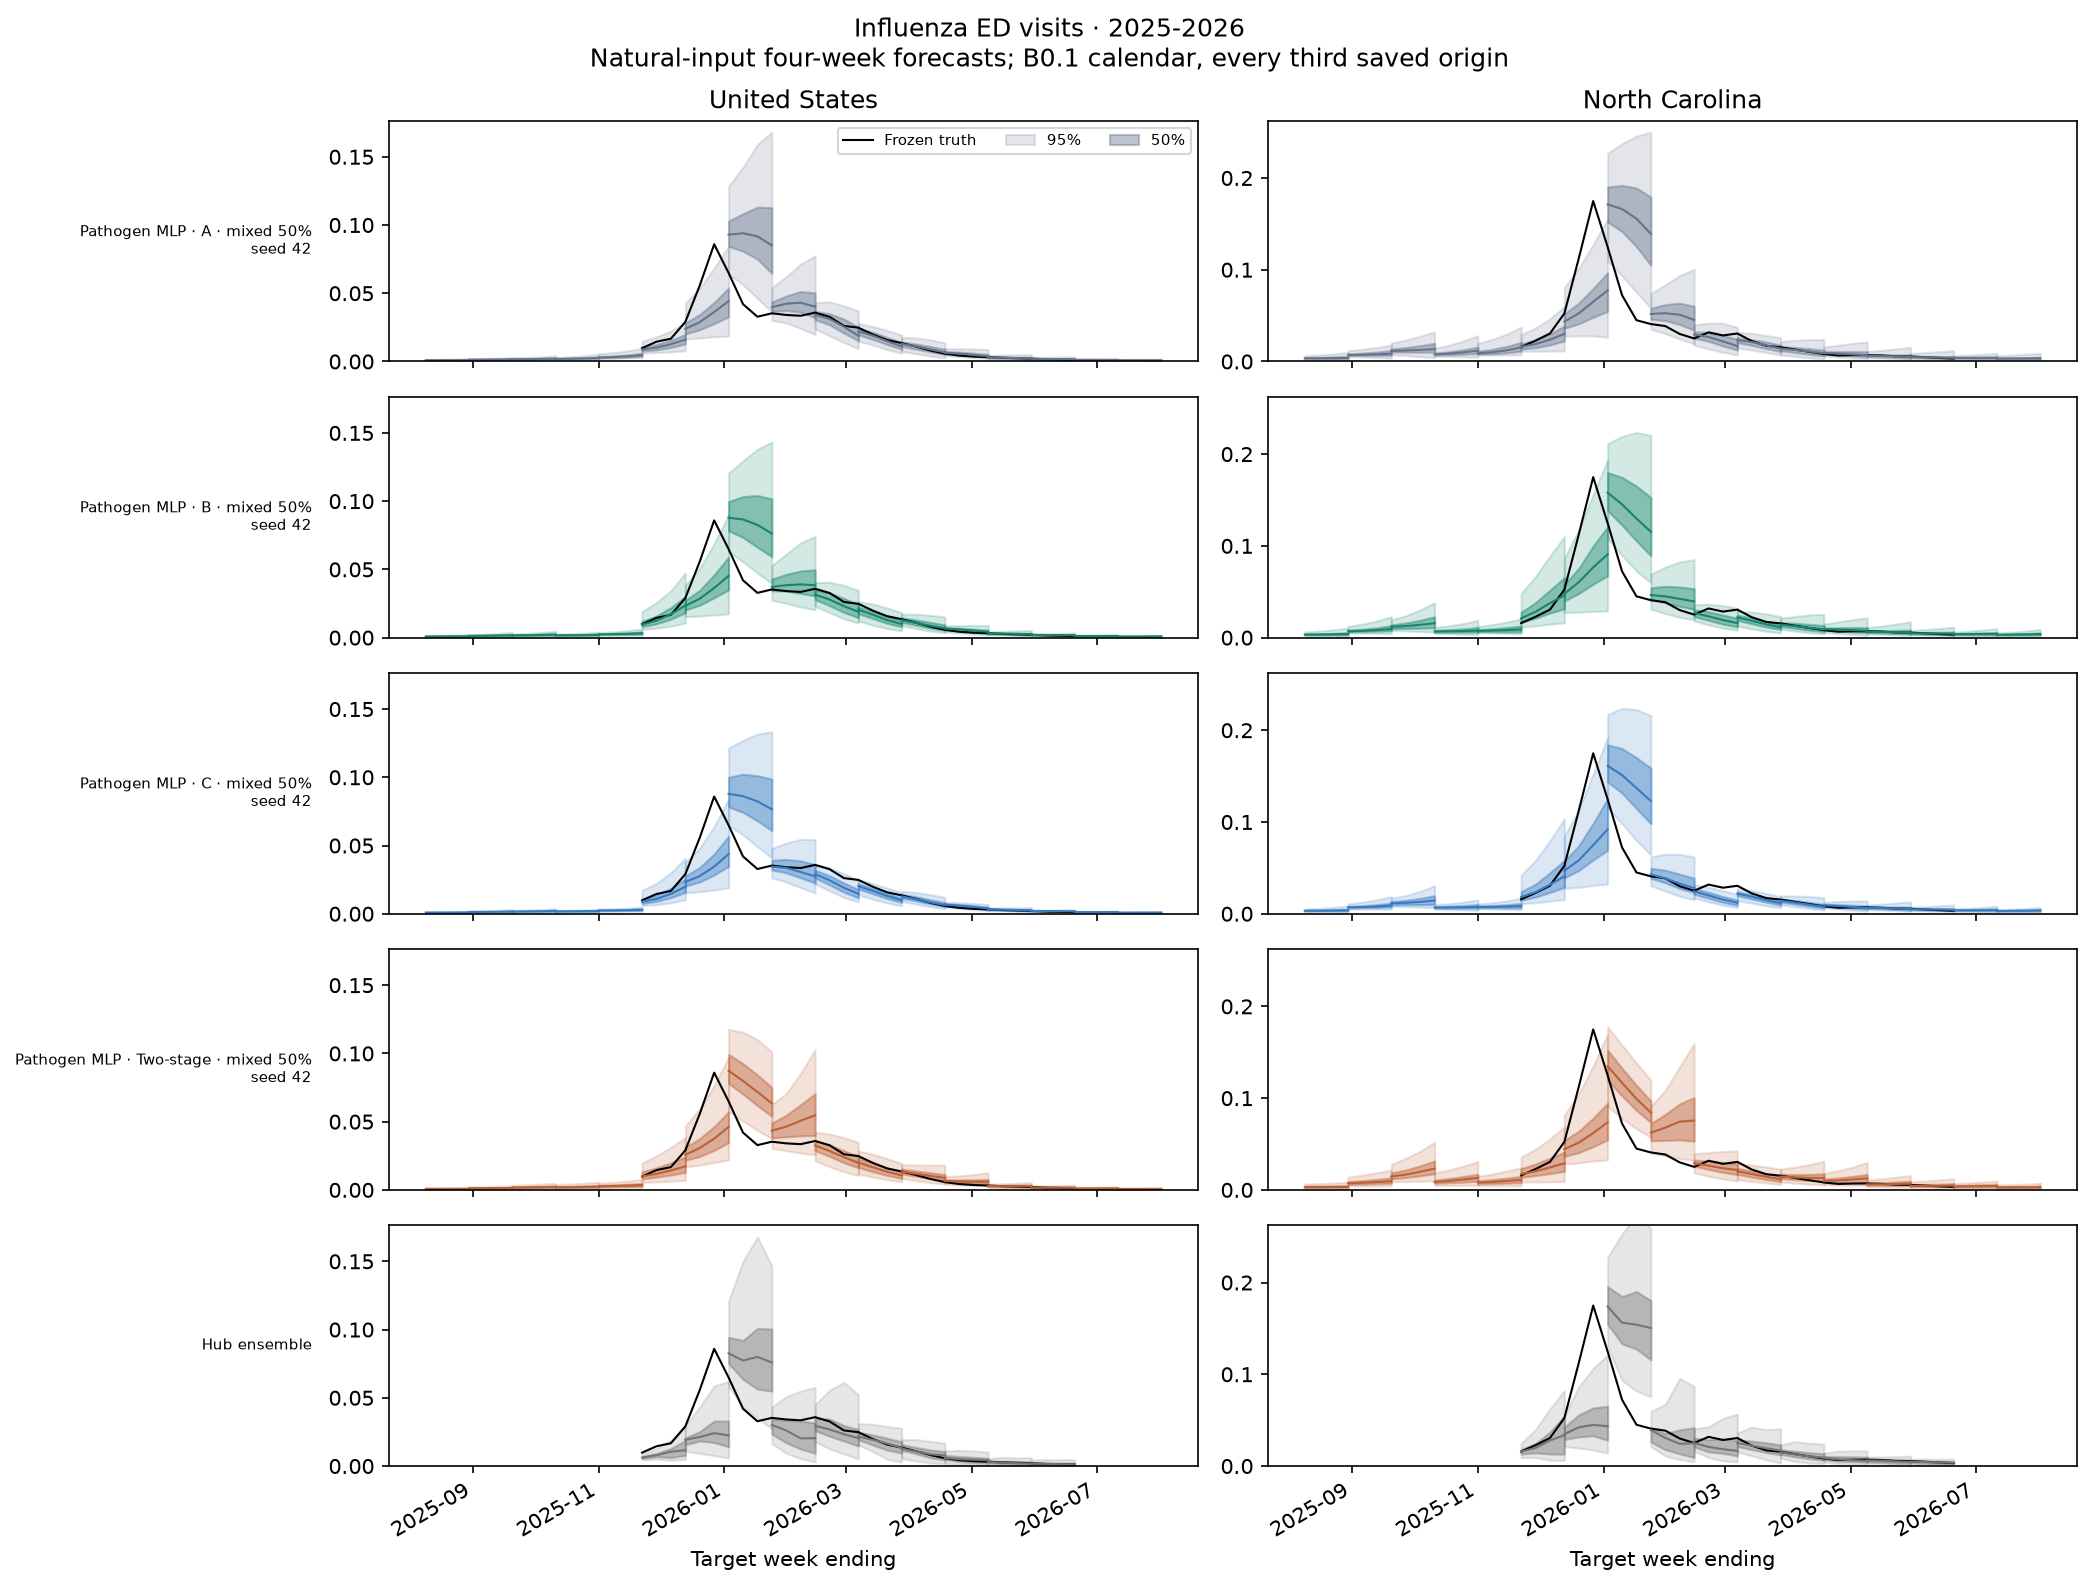
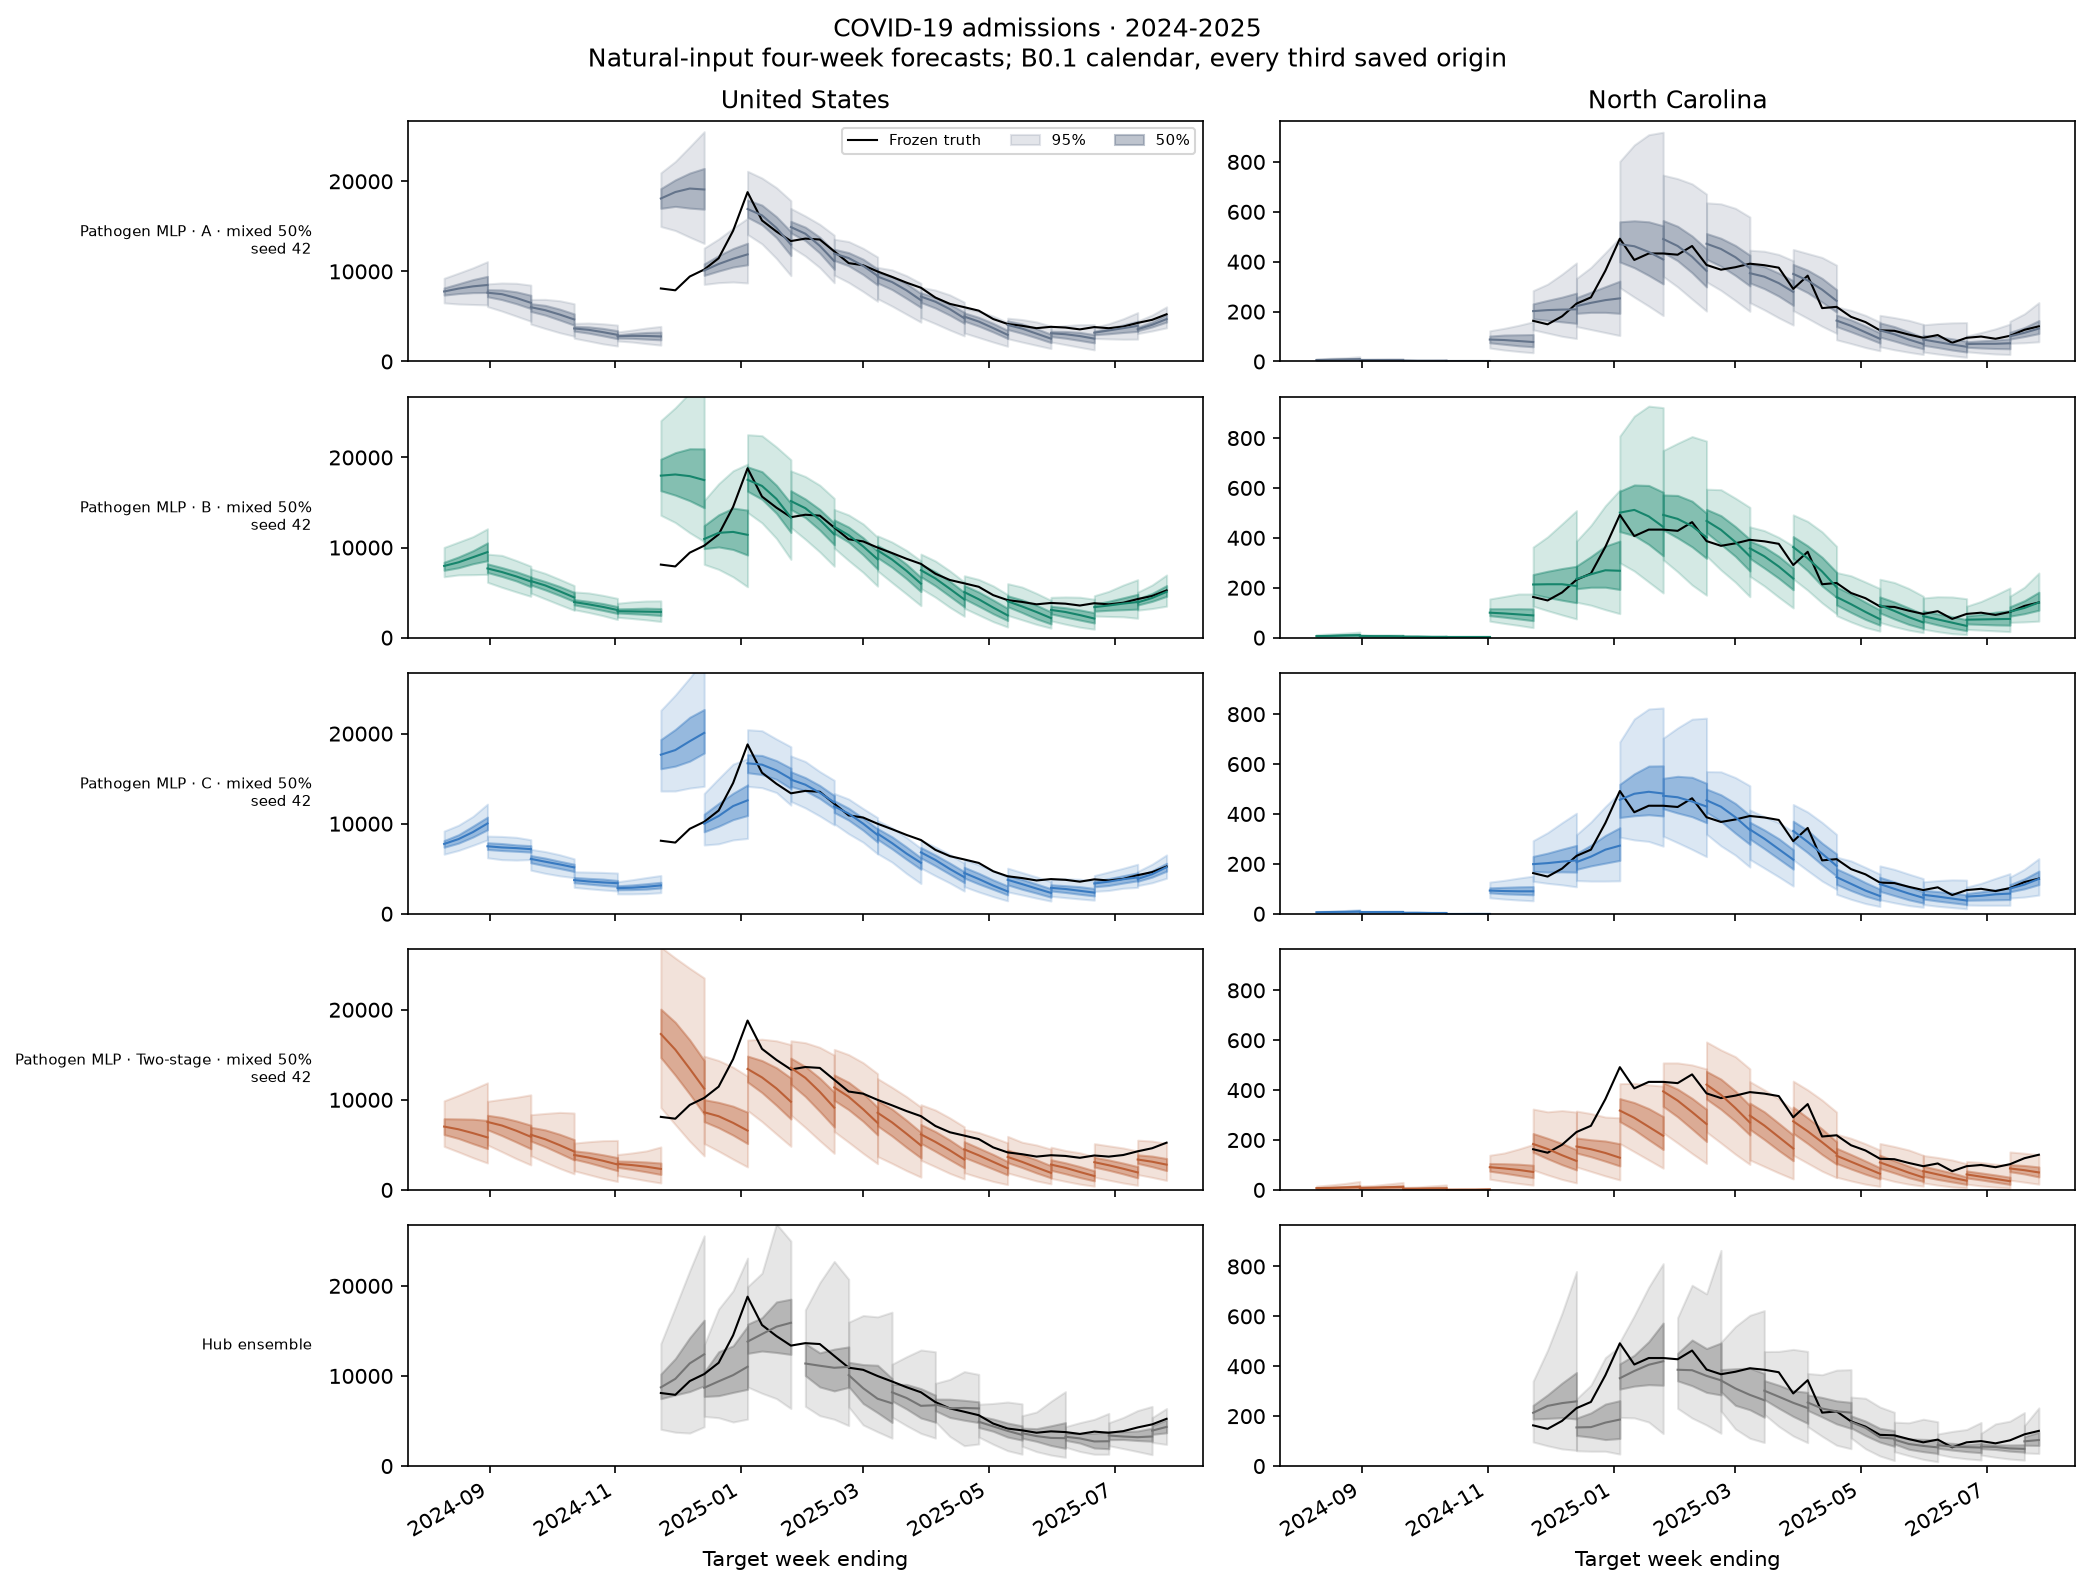
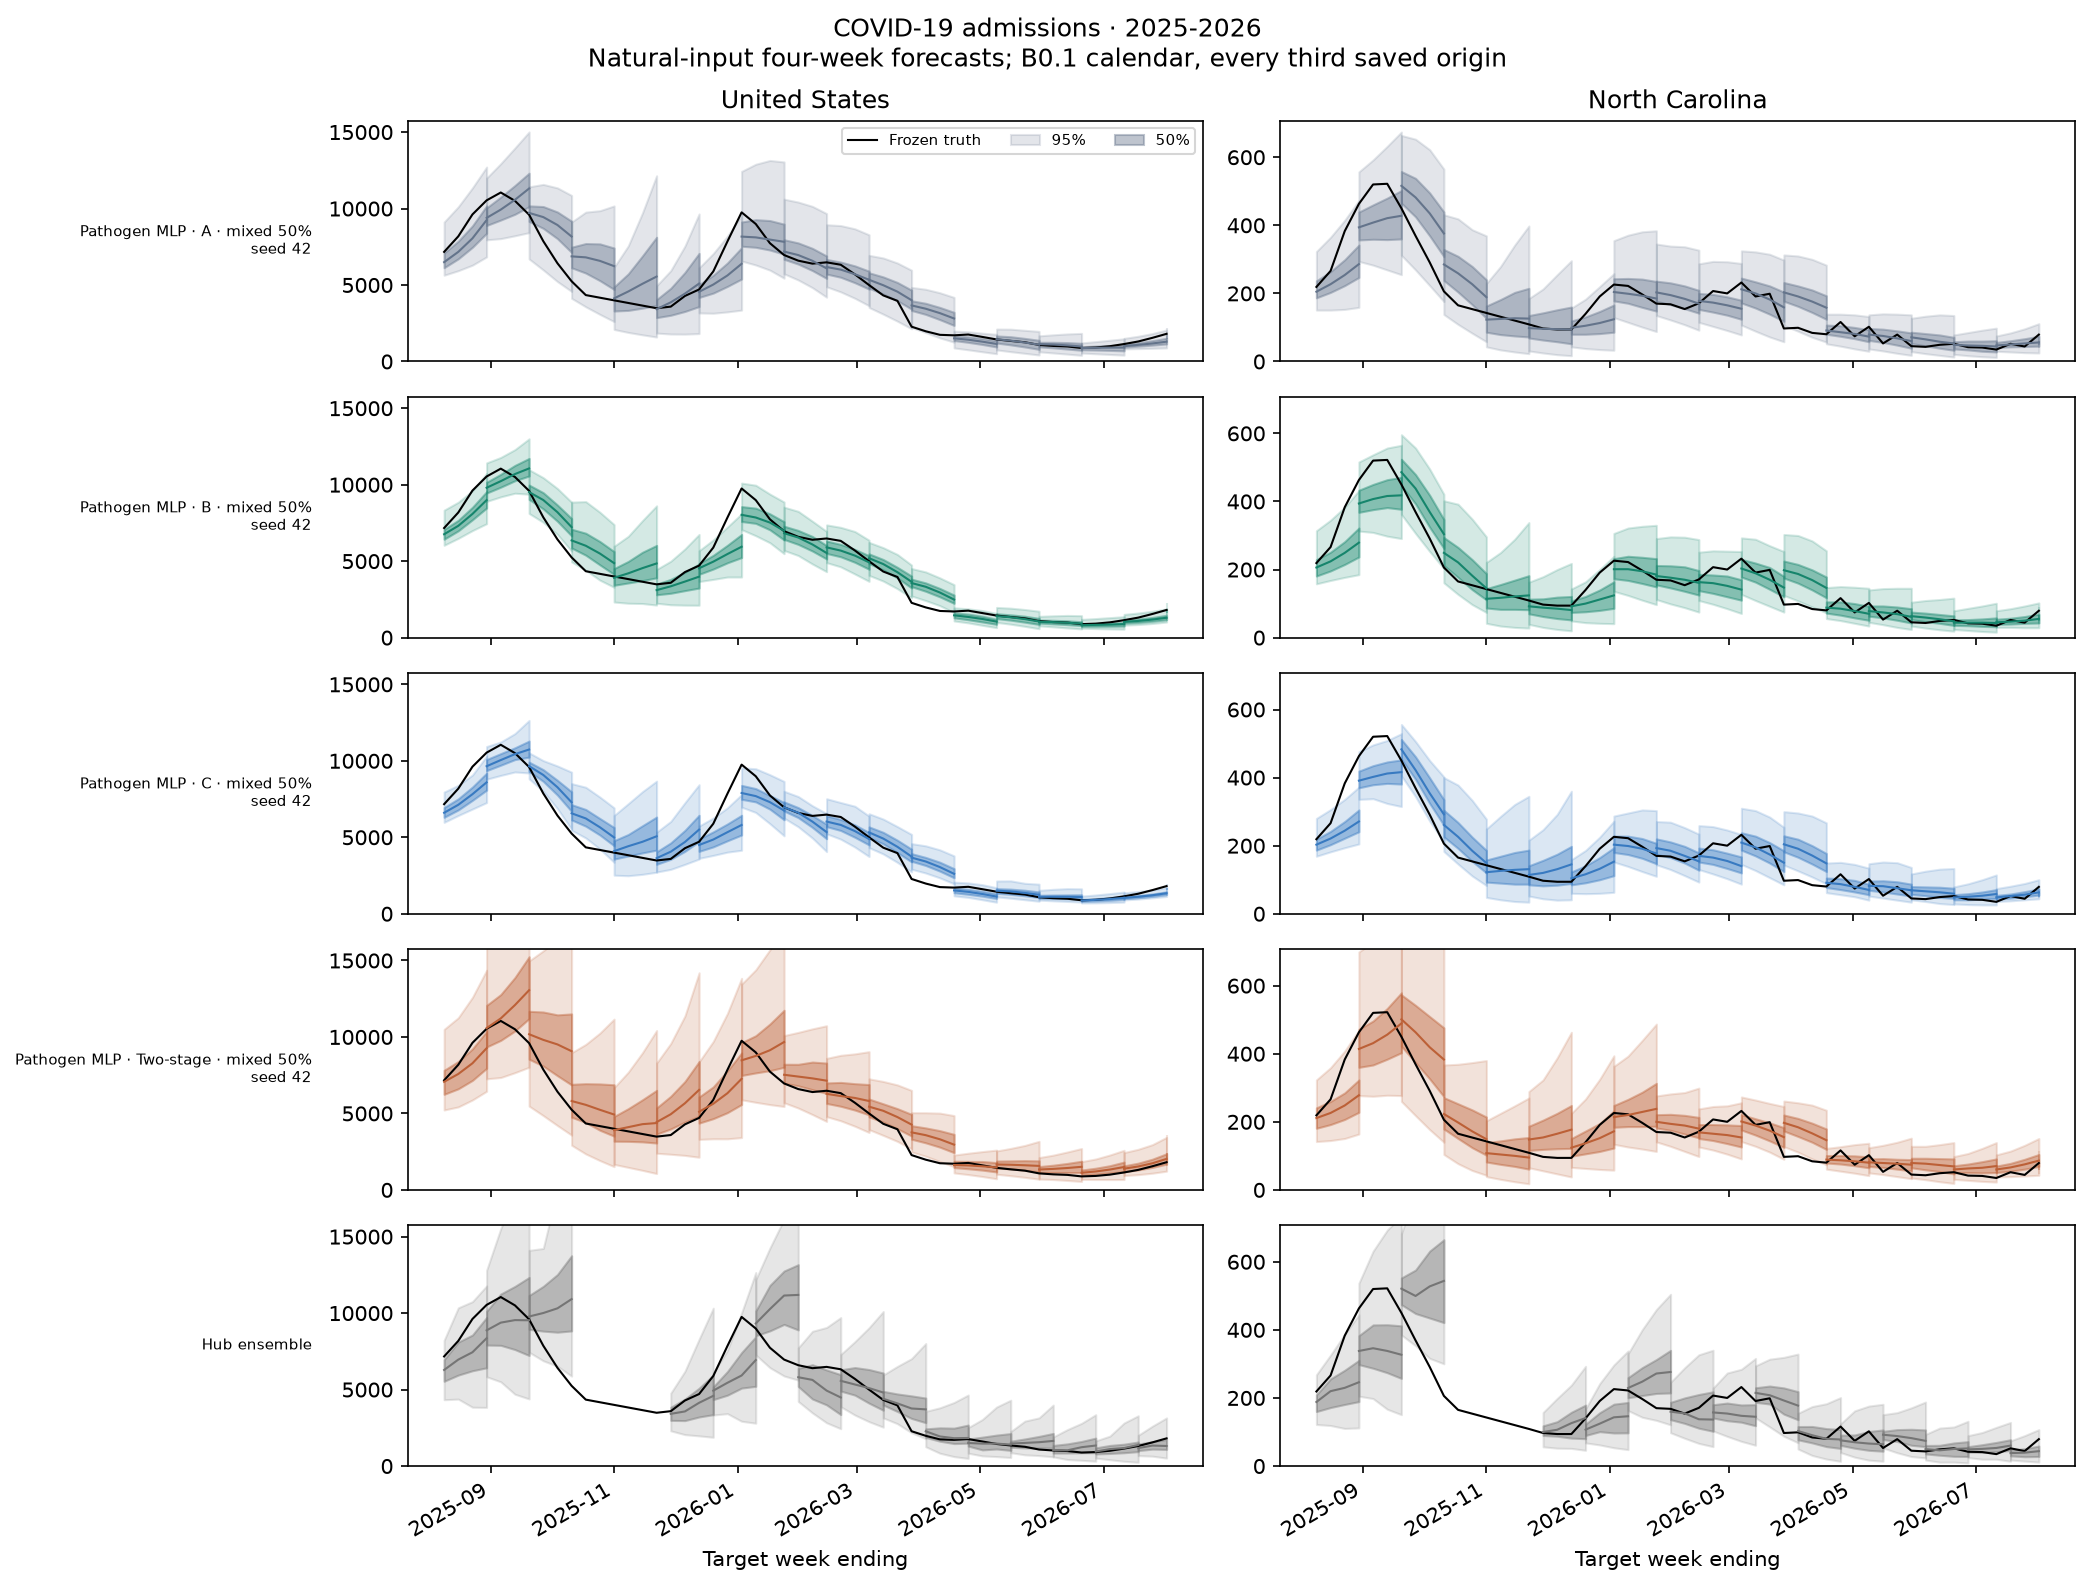
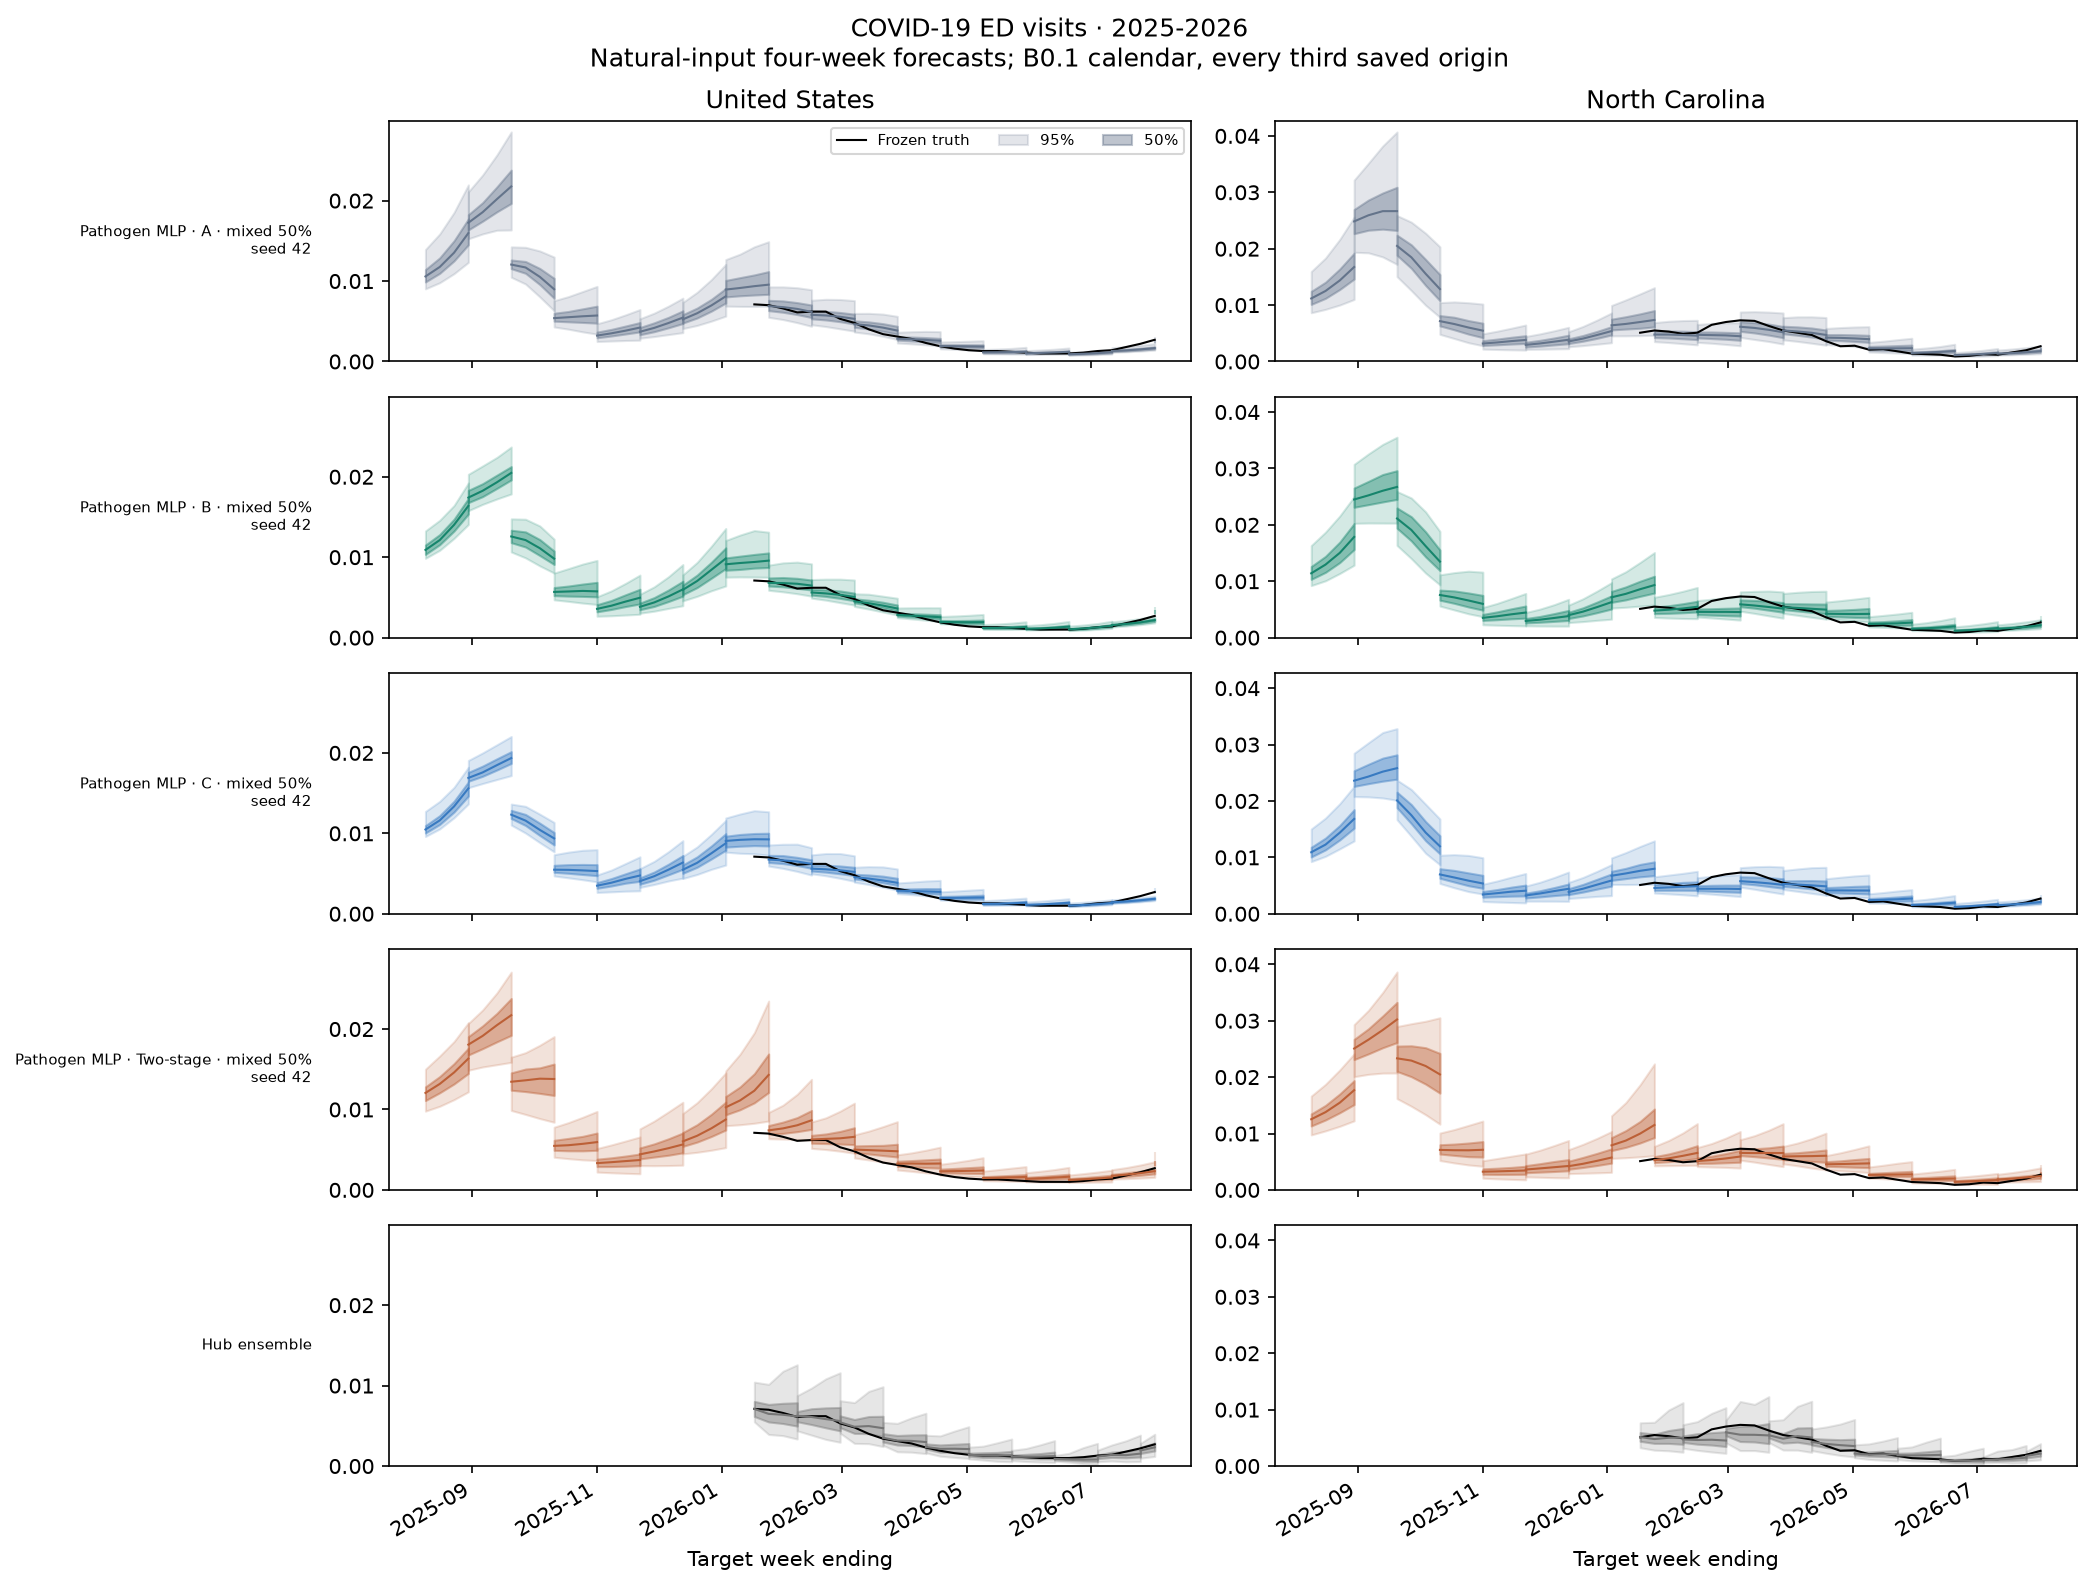
Natural-input four-week forecasts at every third saved origin, using the same full seasonal calendar and plotting rule as B0.1, for the United States and North Carolina. Black is frozen truth; colored bands are 50% and 95% intervals, with median lines. Y scales match across models within each location. These examples illustrate forecasts and do not replace the all-location scoring. Forecasts extend beyond the scored Hub window; truth and ensemble remain limited to their available frozen dates. No missing forecast or truth value is filled in. The ranking still uses only identical frozen Hub support. Each row samples its own available origins, as in B0.1.
The standard order throughout the target/season panels is influenza → COVID-19 → RSV, then admissions → ED visits, then oldest → newest season. Saved model dates span September 9, 2023–July 27, 2024; August 10, 2024–July 26, 2025; and August 9, 2025–August 1, 2026, respectively. The final fan can have fewer than four available horizons at the held-out season boundary.
Leading configurations
The top three configurations with all three seeds complete, each at its median-scoring seed: Target MLP · B · gap only — seed 44; Pathogen MLP · B · mixed 50% — seed 43; Target MLP · B · no masking — seed 43.
Matched A/B/C/two-stage comparison
Pathogen MLP, mixed masking 50%, fixed seed 42 for every formulation, followed by the Hub ensemble. This seed was fixed for comparability, not chosen for its score.
Score diagnostics
Matched comparisons
Masking around B
Mask rates are episode probabilities, not percentages of cells. Natural missingness remains in every configuration. A recent mask hides recent observations across locations; a gap hides a short channel/location block; an outage removes a channel across the full context. Validation masks follow the candidate mixture, so these comparisons change both training and checkpoint-selection conditions.
| Architecture | None | Mixed 25% | Mixed 50% | Recent only | Gap only | Outage only |
|---|---|---|---|---|---|---|
| Target MLP | 0.953 (3/3) | 0.982 (3/3) | 0.980 (3/3) | 1.006 (3/3) | 0.939 (3/3) | 1.092 (3/3) |
| Pathogen MLP | 0.956 (3/3) | 1.053 (3/3) | 0.952 (3/3) | 1.021 (3/3) | 0.975 (3/3) | 0.964 (3/3) |
| Target convolution | 0.980 (3/3) | 1.037 (3/3) | 1.031 (3/3) | 1.071 (3/3) | 0.978 (3/3) | 1.073 (3/3) |
| Joint MLP | 1.063 (3/3) | 1.058 (3/3) | 0.990 (3/3) | 1.055 (3/3) | 1.055 (3/3) | 0.981 (3/3) |
Full ranking
Ranking
| Rank | Configuration | WIS ratio | Seed SD | Seeds / 3 | States/DC | US |
|---|---|---|---|---|---|---|
| 1 | Target MLP · B · gap only | 0.939 | 0.019 | 3 | 0.958 | 0.863 |
| 2 | Pathogen MLP · B · mixed 50% | 0.952 | 0.055 | 3 | 0.971 | 0.875 |
| 3 | Target MLP · B · no masking | 0.953 | 0.035 | 3 | 0.970 | 0.885 |
| 4 | Pathogen MLP · B · no masking | 0.956 | 0.039 | 3 | 0.972 | 0.894 |
| 5 | Pathogen MLP · C · mixed 50% | 0.957 | 0.039 | 3 | 0.975 | 0.885 |
| 6 | Pathogen MLP · B · outage only | 0.964 | 0.034 | 3 | 0.977 | 0.911 |
| 7 | Joint MLP · C · mixed 50% | 0.972 | 0.054 | 3 | 0.980 | 0.941 |
| 8 | Pathogen MLP · B · gap only | 0.975 | 0.028 | 3 | 0.989 | 0.921 |
| 9 | Target convolution · B · gap only | 0.978 | 0.050 | 3 | 0.984 | 0.953 |
| 10 | Target convolution · B · no masking | 0.980 | 0.062 | 3 | 0.982 | 0.972 |
| 11 | Target MLP · B · mixed 50% | 0.980 | 0.042 | 3 | 0.993 | 0.932 |
| 12 | Joint MLP · B · outage only | 0.981 | 0.044 | 3 | 0.985 | 0.967 |
| 13 | Target MLP · B · mixed 25% | 0.982 | 0.052 | 3 | 0.994 | 0.933 |
| 14 | Target MLP · C · mixed 50% | 0.985 | 0.029 | 3 | 0.998 | 0.931 |
| 15 | Joint MLP · B · mixed 50% | 0.990 | 0.054 | 3 | 0.997 | 0.965 |
| 16 | Target convolution · C · mixed 50% | 1.005 | 0.078 | 3 | 1.023 | 0.932 |
| 17 | Target MLP · B · recent only | 1.006 | 0.046 | 3 | 1.016 | 0.969 |
| 18 | Joint MLP · A · mixed 50% | 1.012 | 0.117 | 3 | 1.014 | 1.003 |
| 19 | Pathogen MLP · B · recent only | 1.021 | 0.046 | 3 | 1.029 | 0.991 |
| 20 | Target MLP · C · outage only | 1.025 | 0.088 | 3 | 1.035 | 0.981 |
| 21 | Target MLP · A · mixed 50% | 1.029 | 0.031 | 3 | 1.032 | 1.017 |
| 22 | Target convolution · B · mixed 50% | 1.031 | 0.041 | 3 | 1.044 | 0.980 |
| 23 | Target convolution · B · mixed 25% | 1.037 | 0.071 | 3 | 1.043 | 1.014 |
| 24 | Pathogen MLP · A · mixed 50% | 1.045 | 0.152 | 3 | 1.049 | 1.029 |
| 25 | Target convolution · C · outage only | 1.047 | 0.044 | 3 | 1.061 | 0.990 |
| 26 | Pathogen MLP · B · mixed 25% | 1.053 | 0.014 | 3 | 1.054 | 1.051 |
| 27 | Joint MLP · B · recent only | 1.055 | 0.018 | 3 | 1.048 | 1.086 |
| 28 | Joint MLP · B · gap only | 1.055 | 0.122 | 3 | 1.047 | 1.091 |
| 29 | Joint MLP · B · mixed 25% | 1.058 | 0.074 | 3 | 1.052 | 1.082 |
| 30 | Joint MLP · B · no masking | 1.063 | 0.099 | 3 | 1.056 | 1.093 |
| 31 | Pathogen MLP · C · outage only | 1.067 | 0.069 | 3 | 1.065 | 1.071 |
| 32 | Target convolution · B · recent only | 1.071 | 0.059 | 3 | 1.064 | 1.097 |
| 33 | Target convolution · B · outage only | 1.073 | 0.042 | 3 | 1.084 | 1.028 |
| 34 | Target MLP · B · outage only | 1.092 | 0.222 | 3 | 1.093 | 1.088 |
| 35 | Target convolution · A · mixed 50% | 1.100 | 0.093 | 3 | 1.105 | 1.079 |
| 36 | Pathogen MLP · Two-stage · mixed 50% | 1.104 | 0.025 | 3 | 1.105 | 1.099 |
| 37 | Joint MLP · C · outage only | 1.112 | 0.109 | 3 | 1.107 | 1.129 |
| 38 | Target MLP · Two-stage · mixed 50% | 1.179 | 0.016 | 3 | 1.176 | 1.191 |
| 39 | Target convolution · Two-stage · mixed 50% | 1.206 | 0.062 | 3 | 1.210 | 1.191 |
| 40 | Joint MLP · Two-stage · mixed 50% | 1.211 | 0.081 | 3 | 1.196 | 1.272 |
Seed SD measures variation across the available seeds, not a confidence interval or significance threshold. All 40 configurations · Per-seed scores.
Appendix
No known result or figure.